There are tons of free ZK resources out there. The hard part is knowing what to learn, and in what order.
So I built a curated ZK learning roadmap:
Math → Cryptography → SNARKs/STARKs → Prover Engineering → zkVMs
https://t.co/wbPMce0dCN
Did some reading on formal verification this weekend:
https://t.co/rP80c2LBG7
https://t.co/Zftj8u11OE
https://t.co/P73BX5TM29
Absolutely worth reading. Especially vitalik's post if you want spark notes version. FV is hot these days, and it's not just empty hype.
If you're trying to understand why the quantum threat has become such a hot topic recently, it's worth understanding three things:
There are three factors that determine how close we are to having a quantum computer capable of breaking cryptography like Bitcoin's:
1. Algorithms: finding ways to break cryptography using fewer qubits.
2. Hardware: building quantum computers with more physical qubits.
3. Error correcting code: making those qubits reliable enough to perform complex computations.
We're seeing progress on all three fronts: algorithms that require fewer qubits, better error-correcting codes, and new ways to build quantum hardware.
When all three improve together, the gap to breaking today's cryptography can close much faster than we might expect.
And that's why people like me are increasingly concerned that Q-day may be closer than we think.
Q. Why is a power-of-2 modulus dangerous for lattice-SNARK soundness, unlike prime-field SNARKs?
In prime-field SNARKs, using a modulus where (p-1) is divisible by a large power of 2 is useful because it allows efficient NTT operations.
However, in lattice-based protocols like LaBRADOR, soundness relies on differences between verifier challenges being invertible in the underlying ring. This prevents a dishonest prover from using zero-divisors to make different, inconsistent witnesses pass verification.
A power-of-2 modulus creates many non-invertible elements, increasing the possibility of such attacks and weakening the soundness assumptions.
This makes choosing the modulus particularly important in lattice-based protocols. zkSecurity's review identified this parameter-selection issue in code that was close to production.
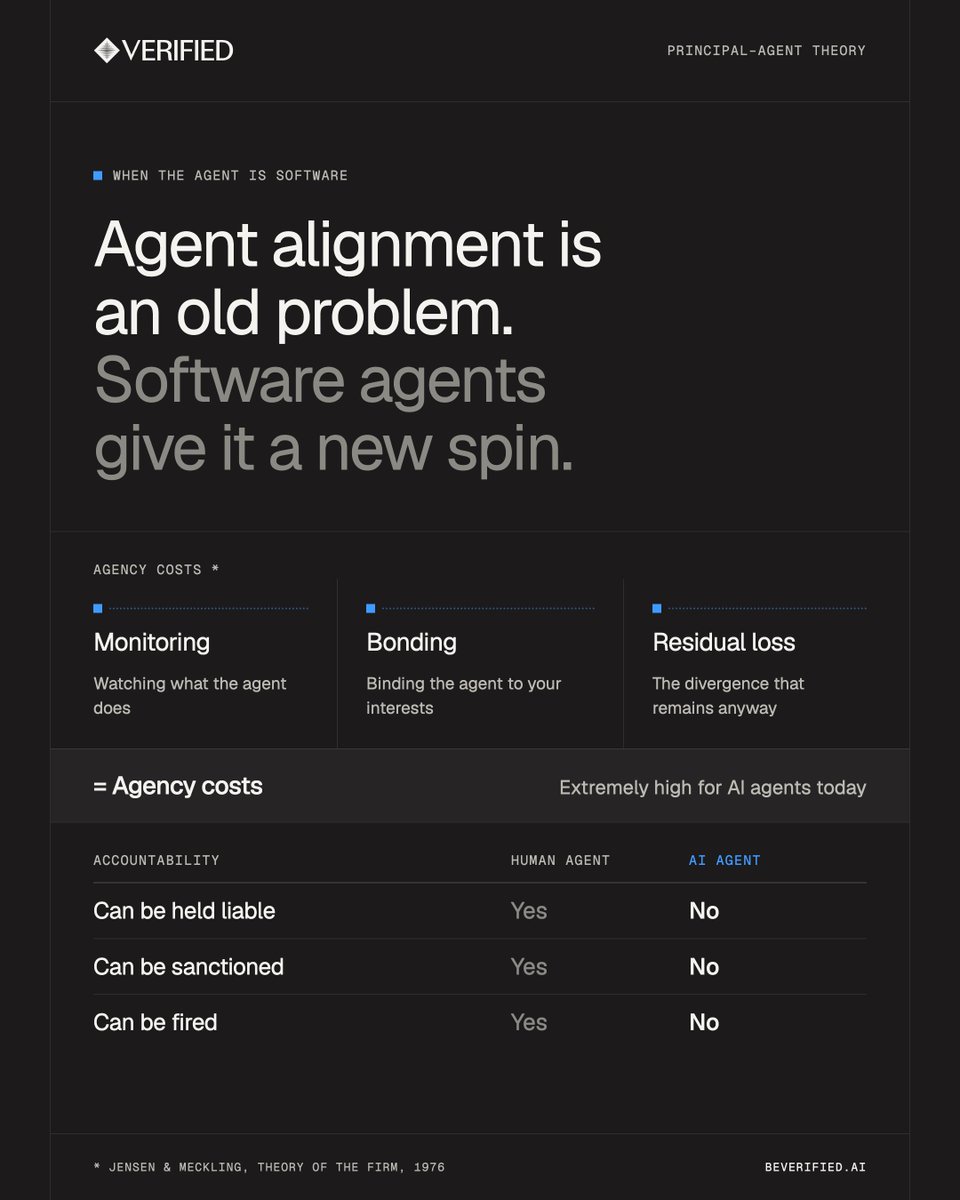
Extremely interesting to see how surprised people and companies are that AI agents and their principals might have different interests.
Principal-agent theory (PAT) is decades old and backed by a huge body of research. But when the agent is a software system, it gets a completely new spin.
PAT calls the cost of this divergence agency costs: the cost of monitoring the agent, of binding it to your interests, and the loss that remains anyway. Right now, for AI agents, these costs are extremely high. If you want to understand what’s going on, learn PAT.
It’s great to see researchers already applying these long-established frameworks to autonomous systems. The early findings point in one direction: whether the agent is a human or software, the same problems apply, with one HUGE difference. Software agents lack accountability. They can’t be held liable, sanctioned or fired, and that amplifies agency costs.
This field is young, but it will shape the broader questions around alignment. And aligning autonomous systems with humans and society is the make-or-break issue for actually scaling this technology. If we fail here, it will be regulated out of the market and simply rejected by people. That’s why we’re building solutions to exactly these problems.
Leading researchers worth following:
🔹 Noam Kolt (Hebrew University): Governing AI Agents, agency law and economics applied to AI agents
🔹 Gillian K. Hadfield (Johns Hopkins): incomplete contracting and the economy of AI agents
🔹 Dylan Hadfield-Menell (MIT): the principal–agent alignment problem
🔹 Alan Chan (GovAI): visibility and infrastructure for AI agents
🔹 Iason Gabriel (Google DeepMind): alignment between user, developer and society
🔹 Mihaela van der Schaar (Cambridge): multi-agent systems as principal–agent problems
🔹 Lewis Hammond & Vincent Conitzer (Cooperative AI Foundation / CMU): multi-agent risks
🔹 John Horton, Andrey Fradkin & Peyman Shahidi (MIT / BU): The Coasean Singularity, markets with AI agents
🔹 Steve Phelps (UCL): early experiments on LLM agents in principal–agent conflicts
🎙️Last week @annarrose, @nico_mnbl, @kobigurk spoke with @rotn256 & @g_dellimmagine from @zksecurityXYZ about zkGolf, a competition to build the most efficient, formally verified ZK circuits.
They dug into Clean, AI-driven circuit optimisation and more!
https://t.co/1aCUobdgwB
Software Verification in Lean on November 7 has reached in-person capacity! If you're interested in attending live, please join the waitlist: A livestream link will be shared with all waitlisted registrants a few days before the event.
Really looking forward to giving a workshop on the math behind the Ethereum proximity prize with @aiv768 at @EFDevcon! We will explain the prize problem from the basics, then explain latest research results related to proximity gaps!
https://t.co/FBEcO43lzG
ZK is now being used my millions of people, in 100s of applications. If you haven't been paying attention, now might be a good time to refresh!
Check out our report (It's free!)
https://t.co/gdMJdD04Ki
This weekend we launched EthLib, a Lean4 library for Ethereum!
The goal is to bring Ethereum's primitives, specifications and theorems into one place, building a shared foundation for formally specifying and proving things about Ethereum.
https://t.co/Tt1xpckV7h
@dhsorens recently kicked off a massive effort to formally verify Plonky3 crates in Lean4 using Hax, Charon and Aeneas!
Still very experimental, but exciting progress so far!
I wouldn't have thought this possible just 3 months ago!
https://t.co/3UOFdw1B4e
Q. "Lean Ethereum" versus "Lean," the proof assistant: coincidence, or the same underlying idea?
They are formally two different things that share a philosophy. Lean Ethereum is Vitalik's name for Ethereum's next multi-year protocol redesign, covering the consensus layer ("Lean Consensus"), data handling ("Lean Data"), and a minimal, SNARK-friendly execution environment ("Lean Execution," potentially using RISC-V or a purpose-built "leanISA"). The goal is to reduce the protocol to its smallest rigorous core rather than continuously adding features.
Lean, the proof assistant, is an entirely separate piece of software: a dependently typed functional programming language and interactive theorem prover.
The names converge because both projects share the same underlying instinct: minimize the trusted, unverified surface area of a system until it is small enough to reason about rigorously, rather than trying to secure an ever-growing collection of features after the fact.
That shared philosophy is exactly why formal verification using the other Lean is one of the explicitly named pillars of the Lean Ethereum roadmap, rather than an unrelated side project that happens to share a similar name.
A few reflections on the lattice vs. hash-only debate that our recent Aerie post sparked:
1. Cryptographic ossification for blockchains was never safe. Until the day we know with certainty that P ≠ NP, that finding short vectors in lattices is intractable, that Keccak effectively behaves like a random oracle in deployed SNARKs, and that every single bug has been eliminated from our codebases, blockchains cannot ossify. That is simply not how safe systems are built. Issues will arise, and the system will have to respond.
It’s a double standard to reject lattices because blockchains are hard to upgrade if lattices break, while counting on upgrades if AI breaks your hash function or finds a critical zkVM bug.
The best counterargument is that hash-only designs are more agile: if your hash function breaks, just swap out the hash. But we must aspire to a higher level of agility than this. Indeed, as I cover next, if SNARK recursion itself turns out to degrade security, the proposed hash-only blockchain designs would need to be rethought from the ground up.
2. The real security debate is not lattices vs. hashes — it is lattices vs. building everything on SNARK recursion. That’s because “hash-only” is not really hash-only: it rests on hashes plus the soundness of deep SNARK recursion. Ethereum’s roadmap relies on exactly that: hash-based aggregation needs recursion to keep up with a slot’s worth of signatures, and EIP-8288 would send other signature schemes and users’ own proofs through the same recursive pipeline. In contrast, Aerie proves a slot’s worth of signatures on one laptop without any recursion.
All deployed post-quantum SNARKs rely on the Random Oracle Methodology (via Fiat–Shamir) to establish their security. This is an idealization we know fails in the real world: we have explicit counterexamples where “SNARKs” coming out of this methodology are totally insecure when instantiated with any concrete hash function.
We generally ignore these counterexamples in part because they only arise when proving contrived, self-referential statements about the very hash function used by the SNARK verifier.
But proving statements about the verifier’s own hash function is the exact thing you do in SNARK recursion. That’s why the security of recursive SNARKs can’t be established even in the random oracle model.
On top of that, the standard security proofs for recursion (in other models) suffer an “extractor runtime” blowup that is exponential in the recursion depth, suggesting that security may degrade as more recursion is applied. Yet Ethereum’s own EIP-8288 enables unlimited-depth recursion, even as it lists soundness of recursive SNARKs as a trust assumption. Proofs in more idealized models avoid the blowup, but they mainly tell us that an attack on SNARK recursion would have to exploit the concrete hash function, which is exactly what the Fiat–Shamir attacks above do.
To be clear, we don’t know of any outright attacks on SNARK recursion, and I very much hope it is secure. But some of us who have studied the question have a lingering sense that an attack may be possible in some settings. And if AI is going to supercharge cryptanalysis, there is no reason to expect it to spare Fiat–Shamir for SNARKs, let alone SNARK recursion, both of which have had far less scrutiny than lattices.
So, I do not concede that a “recursion everywhere” hash-only approach is clearly more conservative than one built on standard lattice assumptions.
3. “Just wrap everything in a hash-based SNARK” (like EIP-8288) faces challenges.
Aggregating signatures and proofs off-chain into a single block-level proof is a powerful design independent of the hash-only vs. lattice debate, and I am not telling people to avoid it. But claiming, as Vitalik Buterin did this week, that users can run whatever cryptography they want locally and wrap it in a client-side leanVM proof glosses over major hurdles.
For example, leanVM today is a minimal VM designed almost entirely to prove hash-based signatures and recursion, not general-purpose computation. And binary-field SNARKs like leanVM remain slow at proving the integer multiplications that lattice cryptography does en masse.
I am optimistic that many of these zkVM challenges can be met (including via my own work, binary-field Twist and Shout, which are now implemented in Magnetar). But regardless, if lattices can make aggregation simpler and faster, then they should be leveraged. We need to be agile no matter what.
4. For chains whose reason for existence is privacy, I truly struggle to understand the pushback. Public-key encryption (and fast single-server PIR) cannot be built from hashes alone, at least not in any black-box way. If lattices break, it is going to be very, very hard for these chains to provide acceptable levels of privacy and functionality. For a project whose entire reason for existence is privacy, a loss of confidentiality is an existential failure. Next to that, a second signature upgrade (after the first one, from elliptic curves alone to, hopefully, a hybrid lattice scheme) is easy.
Summary: We don’t know for sure what is secure and what isn’t. We are all weighing unquantifiable risks against each other, and we do not need to agree on a total order on them. But hash-only solutions face many open engineering challenges, and they are not more “conservative” in the way some have argued. Some of those challenges are entirely prosaic and have nothing to do with bugs or cryptography, like hardware support for custom schemes whose hash function is still undecided. I hope we can overcome those challenges within the appropriate timelines, but they must be acknowledged and portrayed realistically.
Overall, cryptographic agility and defense in depth (e.g., hybrid signatures) are the answer, which is why we are building both lattice-Jolt and hash-Jolt. In practice, the positions are less polarized than social media discourse suggests: for example, StarkWare is working to make Falcon verification cheap (https://t.co/FM68hmkqRx), which is great to see.
Here is the (apparently) controversial take I am sticking to: Conditioned on agility, whenever lattices make systems simpler or more functional, we should embrace them rather than default to “hash-only” designs. Lattices are what the rest of the world will depend on, with decades of study and hardening behind them, and at the system level, less functional often means less secure. Where hash-only designs are just as simple and functional, by all means use them.
The KYC vultures are coming for basic business tasks, like signing up for an innocuous online service or opening an online shop
In the real world, flashing your ID is pretty harmless. online your ID usually sits on some server and is exploitable
Even more so now...