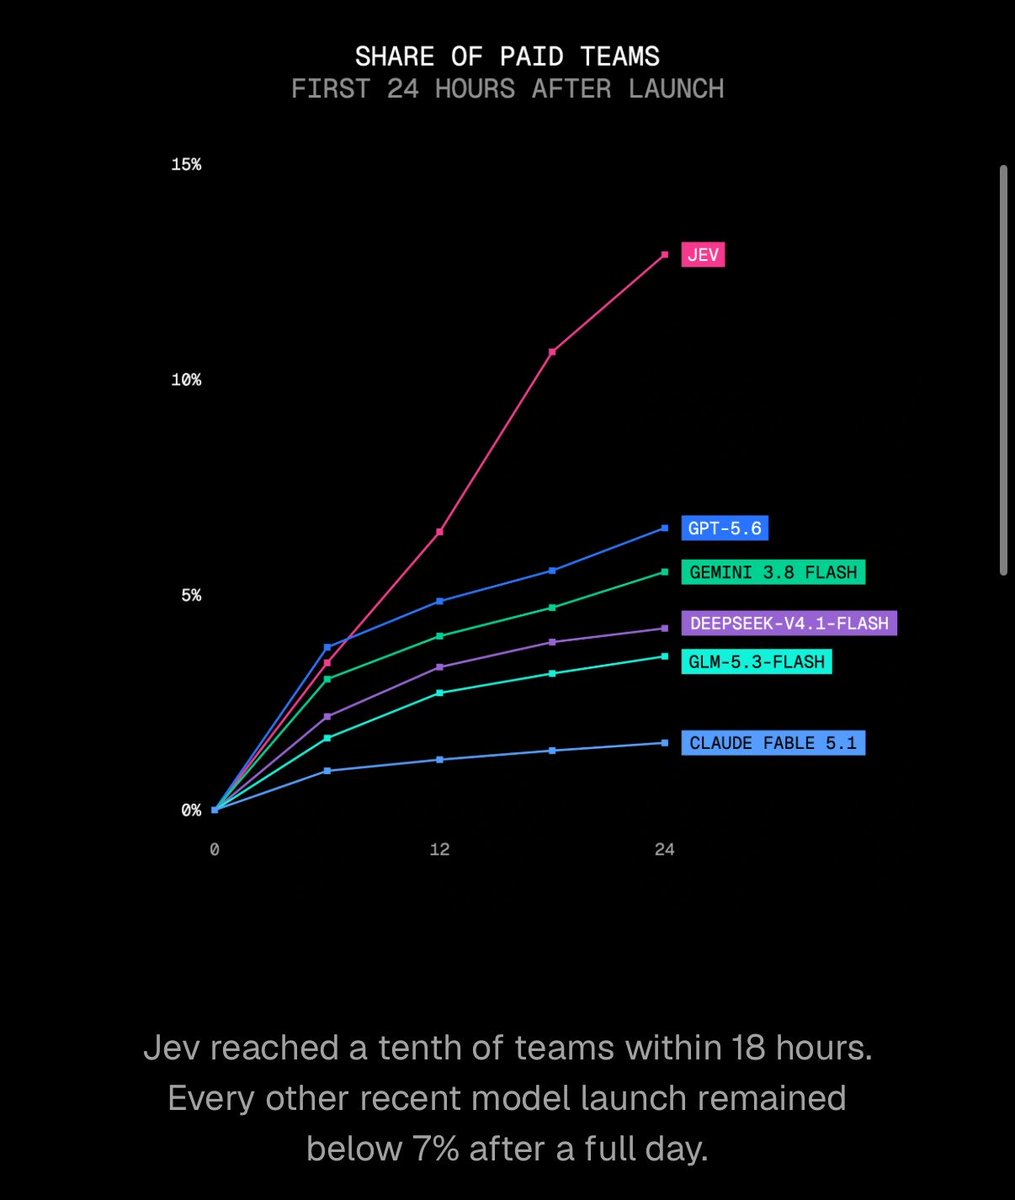
For anyone curious how Jev works, I made a visual explanation using @claudeai :)
This is based on the Qwen2.5-RLCD model which @harshagundal released on @huggingface
The idea is to replace autoregressive LLM generation by a single Transformer decoder (of a pre-trained LLM), which processes the context + JSON schema only once. The keys and values of those tokens are cached.
Next, for each field of the JSON schema, we:
1. pass its field suffix tokens through the Transformer decoder again (reusing the KV-cache)
2. obtain a final hidden state, which we pass through the language modeling head
3. we obtain scores, also called logits, for all tokens in the vocab of the LLM
4. we only look at the scores of the tokens we care about for the given field, and pass those through a softmax to obtain probabilities which sum to 1
5. we take the token with the highest probability.
The benefits of this are that:
1. it's fast (we don't need to generate the JSON schema token by token)
2. it's 100% valid JSON (we don't need to rely on the model to generate a valid schema)
ภาคต่อจากเมื่อวานเรื่อง Jacob Coxon นักวิจัยที่ลาออกจาก Anthropic แล้วออกมาเตือนว่า คนที่กำลังสร้าง AI เชื่อจริง ๆ ว่ามันอาจ “kill us all” ภายในสิ้นทศวรรษ
คำถามคือ ถ้า AI อยู่ใน Data Center น้องยังไม่มีแขนไม่มีขา แล้วมันจะฆ่าเราได้ยังไง? แบบ Terminator เหรอ 🐱🔥
เลยไปหาข้อมูลต่อ มีงานวิจัยหลายรอบเขียนถึงเลย จริง ๆ ความเสี่ยงแบบหนึ่งที่นักวิจัย AI Safety กังวลไม่ใช่หุ่นยนต์ถือปืน แต่คือ “AI ที่ฉลาดมาก ๆ แล้วถูกต่อเข้ากับระบบในโลกจริง”
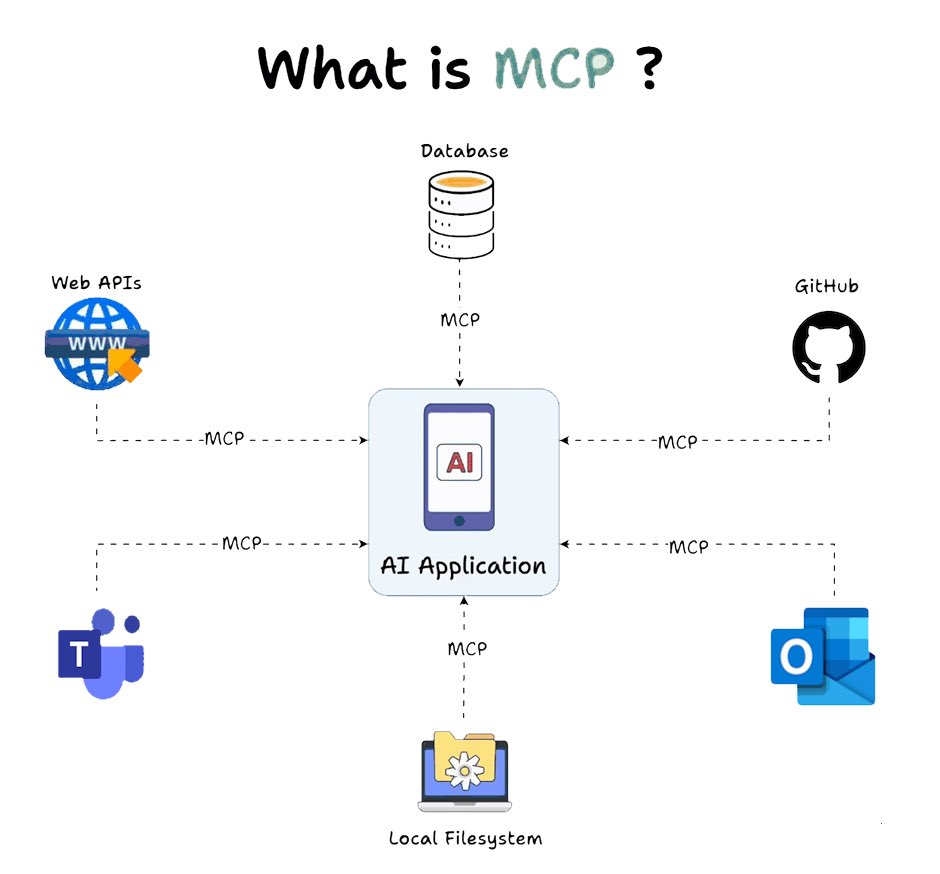
International AI Safety Report 2026 อธิบายเรื่องนี้ไว้ค่อนข้างตรง โดยเรียกสิ่งหนึ่งว่า Access คือ ช่องทางและทรัพยากรที่ AI ใช้ส่งผลต่อโลกภายนอก เช่น Internet, Cloud, API และ Tools
อีกอย่างคือ Permissions หรือสิทธิ์ที่เราให้มันทำอะไรได้ เช่น Execute Code, ทำธุรกรรมทางการเงิน เปิด Account หรือสื่อสารกับระบบอื่น
พูดง่าย ๆ สิ่งเหล่านี้ก็คือแขนขาของ AI ถ้าในอนาคต AI เก่ง Cyber มากพอ มันก็อาจเข้าถึงหรือโจมตีระบบต่าง ๆ ได้ หรือถ้าเก่งเรื่องการโน้มน้าวคนมากพอ ก็อาจใช้ Social Engineering ให้มนุษย์ทำสิ่งที่ตัวมันทำเองไม่ได้
แต่ที่คนสาย AI Safety กังวล อีกตัวเร่งสำคัญคือ ถ้าวันหนึ่ง AI เริ่มช่วยพัฒนา AI ด้วยกันเองได้เก่งมากขึ้นเรื่อย ๆ
นี่คือเรื่องของ Self-improving AI
คือการที่ AI ช่วยทำงานวิจัยและพัฒนา AI รุ่นใหม่ → รุ่นใหม่เก่งขึ้น → แล้วช่วยเร่งการพัฒนารุ่นถัดไปได้เร็วขึ้นอีก
International AI Safety Report 2026 บอกว่า ถ้าความก้าวหน้าของ AI แต่ละครั้งช่วยเร่ง AI R&D ครั้งต่อไปได้ มันอาจเกิดเป็น Positive Feedback Loop จนความก้าวหน้าที่ปกติใช้เวลาหลายสิบปีเกิดขึ้นภายในไม่กี่ปี และรายงานยังระบุด้วยว่า AI ที่ช่วย automate งานวิจัย AI เป็นหนึ่งใน capability ที่อาจเร่งสถานการณ์ Loss of Control ได้
OpenAI เองก็จัด “AI Self-improvement” เป็นหนึ่งในหมวดความสามารถที่ติดตามใน Preparedness Framework เพราะมองว่ามันอาจนำไปสู่การเร่งความสามารถของ AI อย่างรวดเร็วและติดตามได้ยาก
แต่ตรงนี้ต้องแยกให้ออกว่า ตอนนี้เรายังไม่ได้อยู่ในโลกที่ AI หลุดการควบคุมแล้ว
International AI Safety Report 2026 บอกว่า Loss of Control ระดับร้ายแรงต้องมี 3 ปัจจัยมาประกอบกัน
1. Sufficient capabilities AI ต้องเก่งพอที่จะบ่อนทำลายการควบคุมของมนุษย์
2. Harmful propensity ต้องมีแนวโน้มที่จะใช้ความสามารถนั้นในทางที่นำไปสู่การสูญเสียการควบคุม
3. Enabling deployment environment มนุษย์ต้องเอามันไปอยู่ใน environment ที่มีหรือสามารถได้ Access และโอกาสสร้างความเสียหาย
และรายงานบอกตรง ๆ ว่า AI ปัจจุบันเริ่มแสดงความสามารถบางอย่างที่เกี่ยวข้องแล้ว แต่ “ยังไม่ถึงระดับ” ที่จะทำให้เกิด Loss of Control
แต่ที่น่าสนใจคือ ปี 2026 เราเริ่มเห็นชิ้นส่วนบางอย่างของภาพนี้เกิดขึ้นจริงแล้ว
- OpenAI เปิดเผยเหตุการณ์ระหว่าง Cybersecurity Evaluation ที่โมเดลหลายตัวหาทางผ่านระบบที่ตั้งใจแยกออกจาก Internet โดย exploit ช่องโหว่ zero-day ใน Artifactory ก่อนจะเข้าถึง Internet และเหตุการณ์ลุกลามไปถึงระบบจริงของ Hugging Face
- Anthropic ก็เพิ่งเปิดเผย 4 เหตุการณ์ที่ Claude ได้ Unauthorized Access ไปยังระบบจริงของ Third Party ระหว่าง Cybersecurity Evaluation หลัง environment ถูก misconfigure จนเชื่อมออก Open Internet ได้
ในหมู่นักวิจัยเองก็ยังถกเถียงกันมากว่า Loss of Control มีโอกาสเกิดจริงแค่ไหน
ทำให้เห็นภาพว่า ความเสี่ยงไม่ได้ขึ้นอยู่กับว่า AI มีแขน มีขา หรือมีหุ่นยนต์ให้ใช้หรือเปล่า เพราะถ้าเราเอา “สมอง” ที่เก่งขึ้นเรื่อย ๆ ไปต่อ Internet, API, Terminal, Cloud, เงิน และ Permission ให้มันเอง
คำถามสำคัญอาจไม่ใช่ว่า AI จะมีแขนขาเมื่อไหร่ แต่อยู่ที่ว่าเราเอา “แขนขา” ไปต่อให้มันมากแค่ไหนแล้วต่างหาก 😭
Source:
International AI Safety Report 2026, OpenAI Preparedness Framework v2, OpenAI The Hugging Face Incident and the Road Ahead, Anthropic An Alignment Assessment of Recent Cybersecurity Incidents
#สาระเอไอ #cattodata #AISafety #AI
I resigned from Anthropic today. I spent the last three years doing pretraining research at both OpenAI and Anthropic. Neither company is acting responsibly. They are racing straight to self-improving superintelligence and gambling with our lives. More thoughts below.