Day 6 of Inference engineering:
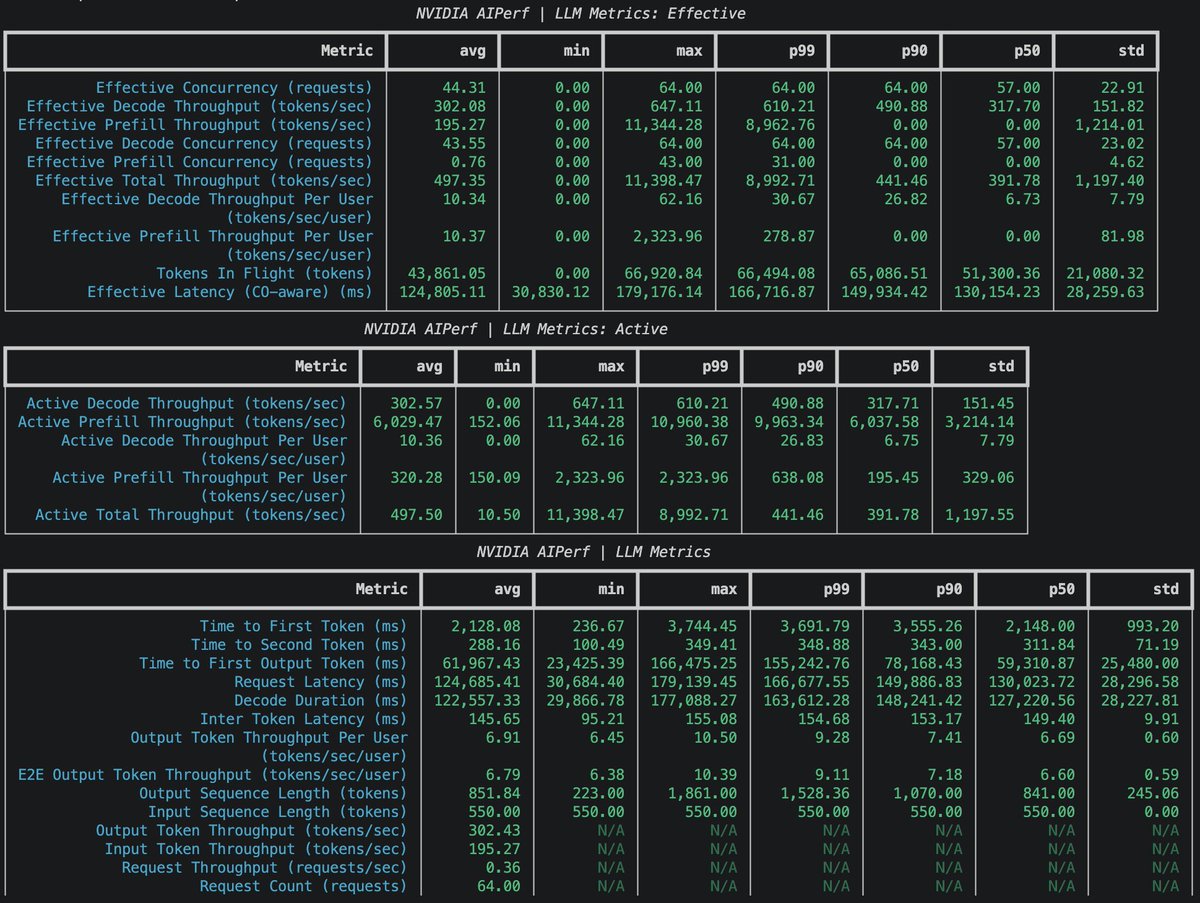
Ran the same aiperf benchmarks(from Day 5) on SGLang server and compared results with vLLM -
- SGLang had 2.4x higher total throughput
- SGLang had 65% lower avg request latency
- SGLang had 73% lower ITL
Started studying https://t.co/0kPNyFFENu
zero-to-sglang just hit 1,000 GitHub stars! Thanks for all your support!
Our new chapters:
📖 Chapter 2.1: mini-sglang — What Does an Inference Engine Look Like?
📖 Chapter 2.2: The Journey of a Request + Code Walkthrough
Find the course following link in comment section👇
In the recent past, loop engineering and Openclaw were the buzz words everyone was after, which I didn't get on and seems like I didn't miss much.
Is Jev the next such buzzword or is it actually something you seem to be using 3-4 months down the line?
@kodejeet Continuing on prev response:
There might be remote roles available but very hard to get into for Indians.
Relevant post for context: https://t.co/VfrnedI9fg
@jaga_prasanna care to provide more insights?
Bro I wish some of these guys were willing to give remote outside US
since we have US visa problems thats side also blocked
from what Ive seen india doesnt have frontier inference company yet and outside india they are not willing to provide remote and Ive been rejected for this reason alone! Mostly
If you looking for AI infra role the market is really bad for us! need to find a way soon!
Day 5 of inference engineering:
Came across this super cool benchamarking repo: https://t.co/HXDApOi8gz
Ran it on T4 machine against Qwen3-0.6B. Would be diving ddep with different models and configs.
PS: Got busy with career stuff and had a break :p
@kodejeet Not much from what I know. AFAIK there's only 2 ways to get into this field (in India):
1) Startups where you have to do lot of other ML work along with inference
2) Top companies like Nvidia, Sarvam etc. which require significant YOE and big names in resume (IIT, FAANG etc).
@jaga_prasanna If people you like you with hands on experience are finding it difficult to land an opportunity in this field. Job market’s cooked for newbies
Day 3 of Inference engineering:
- Deployed Llama-3.2-1B on 2xT4 using vLLM
- Wrote benchmark scripts for measuring latency(non streaming) of varied prompts
- Measured e2e p50, p90, p99 latency times
- e2e_time summary: n=50, mean ~2.92s, p50 ~1.89s, p90 ~7.64s, p99 ~8.48s