Sharing my internship work @GoogleAI: 1) w/ Soft Prompt Transfer, Prompt Tuning matches or significantly outperforms Model Tuning across model sizes, 2) tasks can help each other via their prompts & task prompts can be used as task embeddings to formalize task similarity.
🧵 1/8
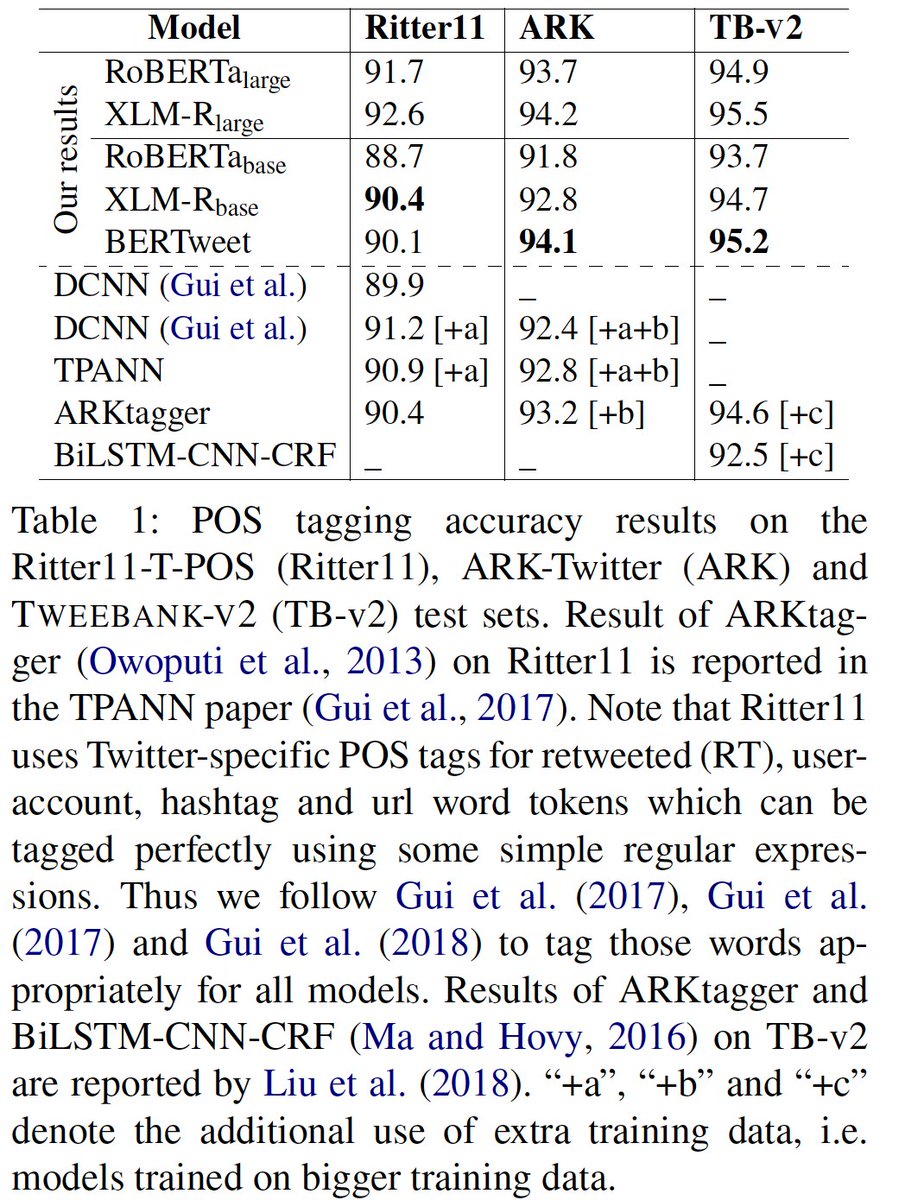
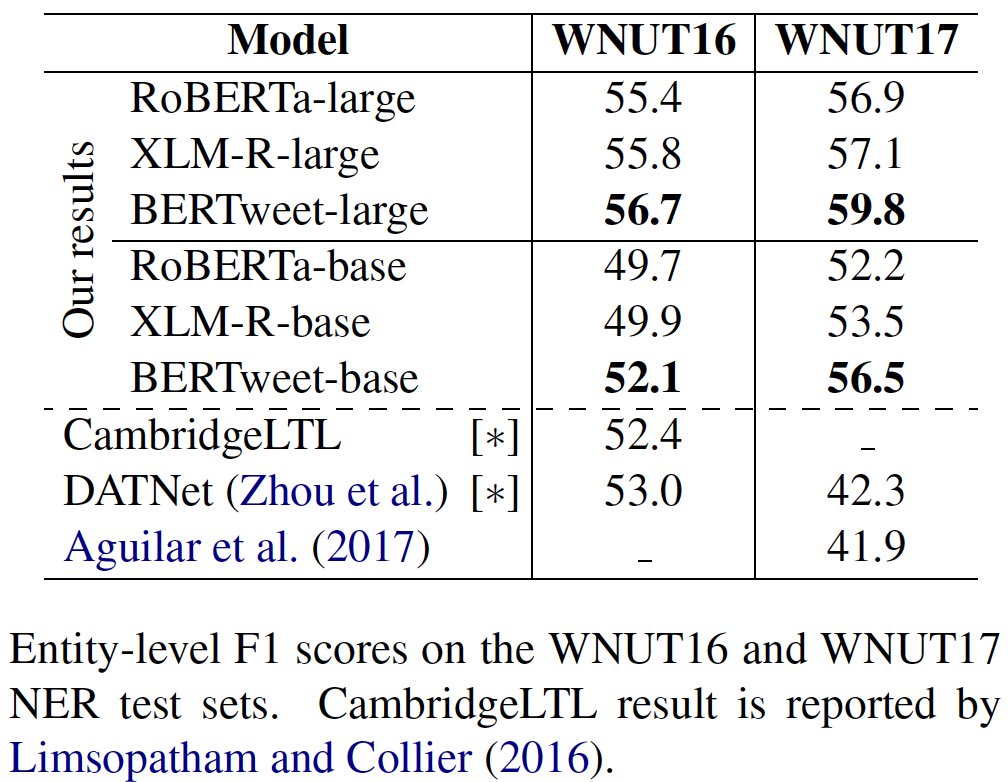
I recently trained and released a large version of BERTweet, that provides a substantial performance boost compared to the previous BERTweet base version. This BERTweet large version is also available on @huggingface transformers, referred to as “vinai/bertweet-large” #NLProc
Recent Advances in Language Model Fine-tuning
New blog post that takes a closer look at fine-tuning, the most common way large pre-trained language models are used in practice.
https://t.co/A5KYoq5zuw
At the @IJCAIconf today with @d_q_nguyen to present our work on "A Label Attention Model for ICD Coding from Clinical Text" https://t.co/fy4GAJU4rA. Please attend our presentation and poster (G8) if you are attending #IJCAI2020!
BERTweet paper is accepted as an #emnlp2020 demo paper. We also released its two variants "cased" and "uncased" BERTweet-COVID19, which are specified to help analyze COVID-19 Tweet content. All 3 models can be used with @huggingface transformers: https://t.co/XMcJbXFCBT
At @ehealthresearch we use artificial intelligence and machine learning to power our digital health research and technologies. Find out how we use AI and Ml in health across data, analytics, imaging, genomics and more in our new report! https://t.co/ut3sye455v
Very excited to share that the PyTorch implementation of our #IJCAI2020 work on large-scale multi-label text classification "A Label Attention Model for ICD Coding from Clinical Text" at available at https://t.co/Y0gNvpVqlN
#textclassification#multilabel#clinicaltext
Our paper "A Label Attention Model for ICD Coding from Clinical Text" got accepted to #IJCAI2020 (Main Track), w/@d_q_nguyen and Anthony Nguyen #IJCAI@IJCAIconf Our model achieves new SOTA results on 3 benchmark MIMIC datasets!
The Pytorch implementation for our knowledge graph embedding model ConvKB is now released at https://t.co/rAkH45aDk1. ConvKB can be used as a decoder to improve the task performance as we show in our ACL 2020 paper for triple classification ( https://t.co/Gv4XOXl7hf).@d_q_nguyen
@EdwardSun0909 To be fair, you should also mention that this issue only happens on FB15K-237, not in FB13 or WN datasets: https://t.co/ufefipOq3x I believe your work contributes a nice finding to the evaluation protocol, but it does not mean baselines are not good. @riedelcastro@sameer_
We're pleased to release BERTweet, the first public large-scale language model pre-trained for English Tweets. The pre-training corpus (850M Tweets ~ 16B words) contains 5M Tweets related the COVID-19 pandemic.
Paper: https://t.co/y9sCXlpGat
Model: https://t.co/Ojg3ctS0As #NLProc
We're pleased to release BERTweet, the first public large-scale language model pre-trained for English Tweets. The pre-training corpus (850M Tweets ~ 16B words) contains 5M Tweets related the COVID-19 pandemic.
Paper: https://t.co/y9sCXlpGat
Model: https://t.co/Ojg3ctS0As #NLProc
“Cloud” use is growing to be key in the delivery of science and healthcare. Our bioinformatics lead @allPowerde talks “science at the speed of cloud” and how her team released an @awscloud health product on @awsmarketplace. @CSIRO https://t.co/5FKDGDoJur