Standard reasoning indexes: Grok 4.7 beats DeepSeek V4.1 Flash 1017 (35.0 vs 32.5).
GDPx 8-hr agentic tasks: Flash 1017 flips it (5.4% vs 3.9%).
Plus it runs ~2x faster (~200 vs 97 tok/s), holds 1M context, and costs ~90% less ($0.15/$0.60 vs $2/$6).
@Kedeodev Without a doubt. You can go from an idea to a global business with almost no capital. That's what makes software such a powerful field, even with AI changing everything.
@ash_twtz It has Video and Audio support as Input but so does Clef Omni.
Its very expensive than all other competing models. Considering its benchmarks on AA Decision Index where it ranks at no. 9 (66), I don't think price is justifiable.
@ArtificialAnlys@GoogleDeepMind It's significantly more expensive than competing decision models, although native audio and video support could justify the cost for some workflows.
A decision model that can watch video and listen to audio is more interesting to me than another 2-point benchmark gain.
Google's new Decisions API does both, though at a higher price.
Where would this actually be useful beyond content moderation?
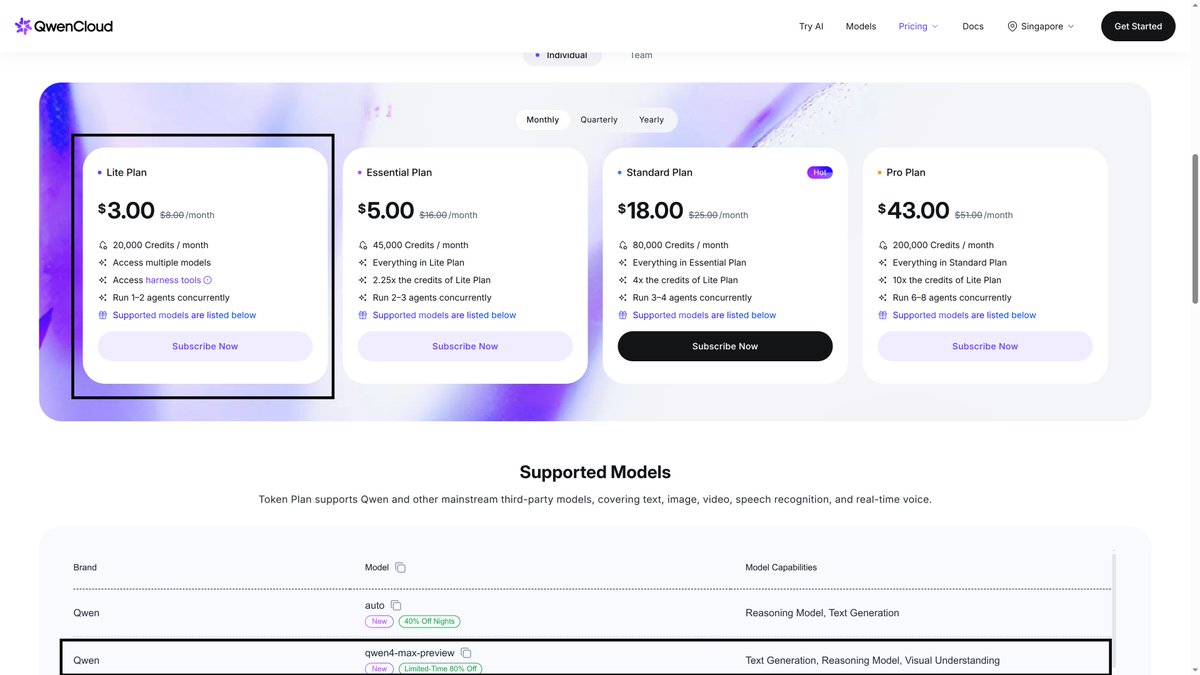
Qwen4-Max-Preview is out. The cheapest way I found to try it is QwenCloud’s $3/month plan.
I haven’t seen any official benchmarks yet. If you’ve tested it, how does it perform in real-world use?
@aiwithadb The difference between subscription value and raw API billing isn't normal either.
A $200 Ultra plan gives you ~$10k+ worth of Opus 5.5 tokens and already has no 5h limit.
@Venkydotdev A $10 Claude plan would last a serious dev about 15 minutes.
Professionals use Claude for Opus 5.5 and Fable 5.2, not Haiku 5.5 and at frontier token prices, $10 of agentic coding is basically a free trial with a paywall.
@aiwithadb Cross-model PR reviews. Never let the model that wrote the code review its own PR. It shares the same project memory and blind spots
For example if I write the PR with Claude, then run Codex cold on the diff to catch what Claude missed.
@elshayib_ Same feeling here. Not expecting miracles from Qwen 4, but I really hope the 27B delivers. Even beating Luna 6 would make it interesting.
https://t.co/esoJMyokC6
Qwen4 benchmark bets (not leaks):
27B: AA Index 27–30 | Terminal-Bench 4.0 13–17% | FrontierCode 2.0 21–25%
Max: AA Index 43–47 | Terminal-Bench 4.0 49–53% | FrontierCode 2.0 33–37%
Too bullish or too conservative?
@uzair__afridi History says yes.
Opus 5.5 cleared Fable 5.1 by 10 points on the AA Index (59 vs 49).
Only question is whether Anthropic actually calls it 5.6 or skips straight to 5.8 / Opus 6.
@coryalthoff Because developer time matters too. Python makes research and iteration faster, while optimized C++/CUDA kernels handle the expensive computations.
@codevsdev Wiser, I think. AI made me realize coding was never the real bottleneck. Knowing what to build and how to reach customers is much harder than code itself.