maybe they could theoretically run manipulations/experiments because they have access to both the platform AND the data--but I don't think the ability to amass the data *itself* poses a unique risk
I'm very confused about why data collected via TikTok poses *such* a compelling national security risk, when foreign powers could attain analogous data from domestic companies directly or via data brokers--am I missing something? https://t.co/4xoB2OyJsD
*Or* comment on the template directly https://t.co/ae6bVDHpRe
*Or* ping me or one of my amazing collaborators
@natolambert @sociotiose @aaronsnoswell + Sarah Dean.
.
Anticipating and responding to feedback is crucial to keeping ML systems equitable and safe–see how documentation can help!👇🧵
Paper: https://t.co/V7vju3axC0
Template: https://t.co/ae6bVDHpRe
Blog Post: https://t.co/vF12n2vqXb
Workshop June 11: https://t.co/N0ULOsHLhf
Do you work on RL or frequently updated ML systems in the wild? Would Reward Reports fit in you workflow? What would you change?
Let us know at out (un)workshop at the RLDM conference on June 11th
https://t.co/VKlozKDGHJ
🚨 Incredible opportunity alert 🚨
The @pulitzercenter is giving 6-8 journalists up to $20k each to report on the social impacts of AI & automation. So excited to see such a major journalism institution put their weight behind these kinds of stories. 😍
https://t.co/ceHuXYdiZo
Ramon @vilarinoramon is leading a summer program held at @Berkeley_EECS
The program will focus on auditing of software tools used in criminal legal systems and disproportionately impact AfroLatinx communities.
Program details: https://t.co/Ko1NHGggm1
Priority deadline: March 2
More work on this and how it might fit into legal accountability frameworks is forthcoming so get in touch if you're interested!
Thanks for reading (:
Want more? Here's a technical summary on @natolambert's blog if you're into that: https://t.co/c5oLmGPiAQ
I’m excited to share a @CLTCBerkeley project I had the opportunity to work on with @sociotiose
@natolambert and Sarah Dean,
Choices, Risks, and Reward Reports: Charting Public Policy for Reinforcement Learning Systems.
Press release: https://t.co/FYowubd0vr…
🧵
The big thing here is the *iterative* aspect. Static documentation for dynamic systems can't anticipate feedback.
To summarize:
a) RL can be dangerous
b) traditional methods fall short
c) Doom loops = bad
d) Some ideas on how to fix it
More work on this and how it might fit into legal accountability frameworks is forthcoming so get in touch if you're interested!
Thanks for reading (:
For a more technical summary see @natolambert's blog: https://t.co/c5oLmGPiAQ
But which exact algorithmic change(s) did this? Not actually clear.
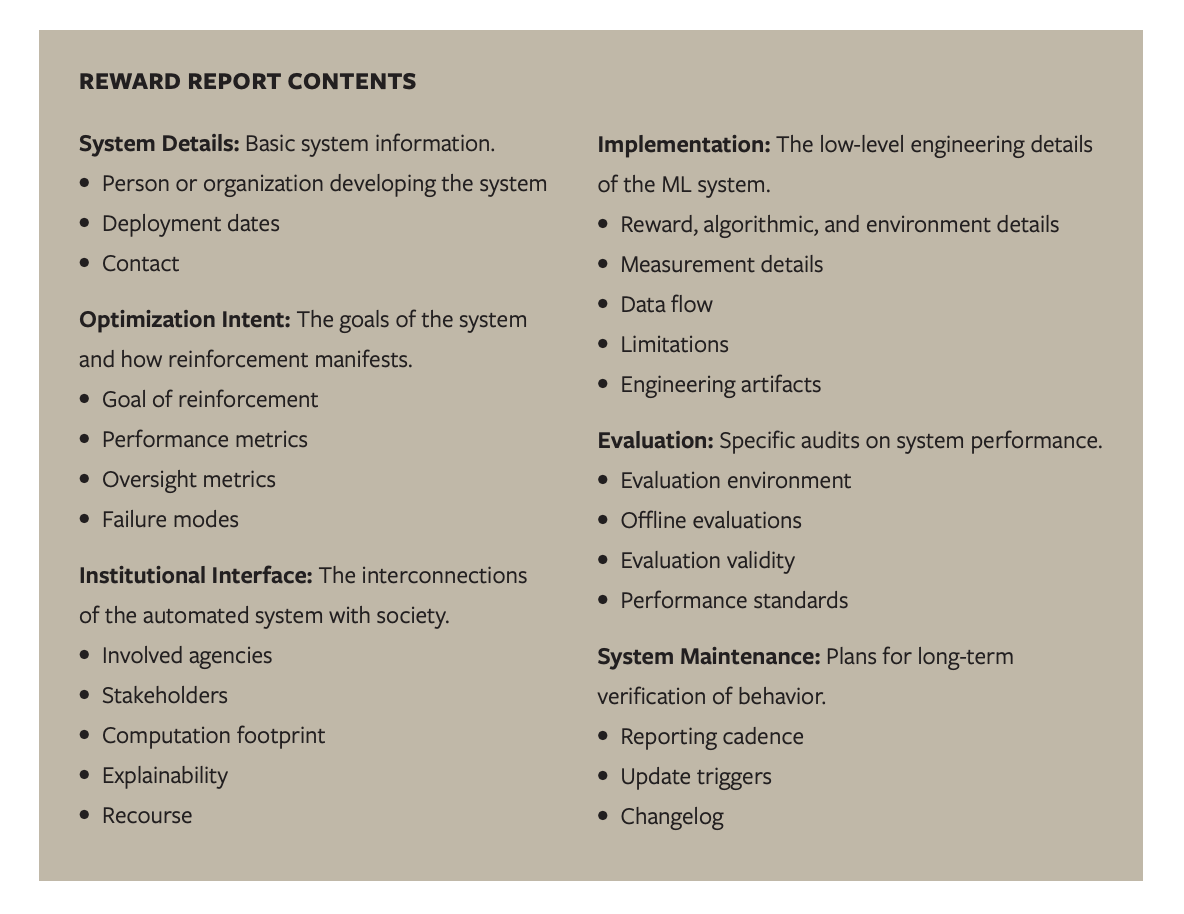
To address this, we propose "Reward Reports" an iterative documentation framework that prompts system designers to anticipate (and account for) feedback.
Here is an early version of what that might entail: