Most SWE benchmarks tell an agent exactly what to fix + where to look.
Imagine if an agent could instead *proactively* surface and fix issues themselves (before a developer even runs into them!)
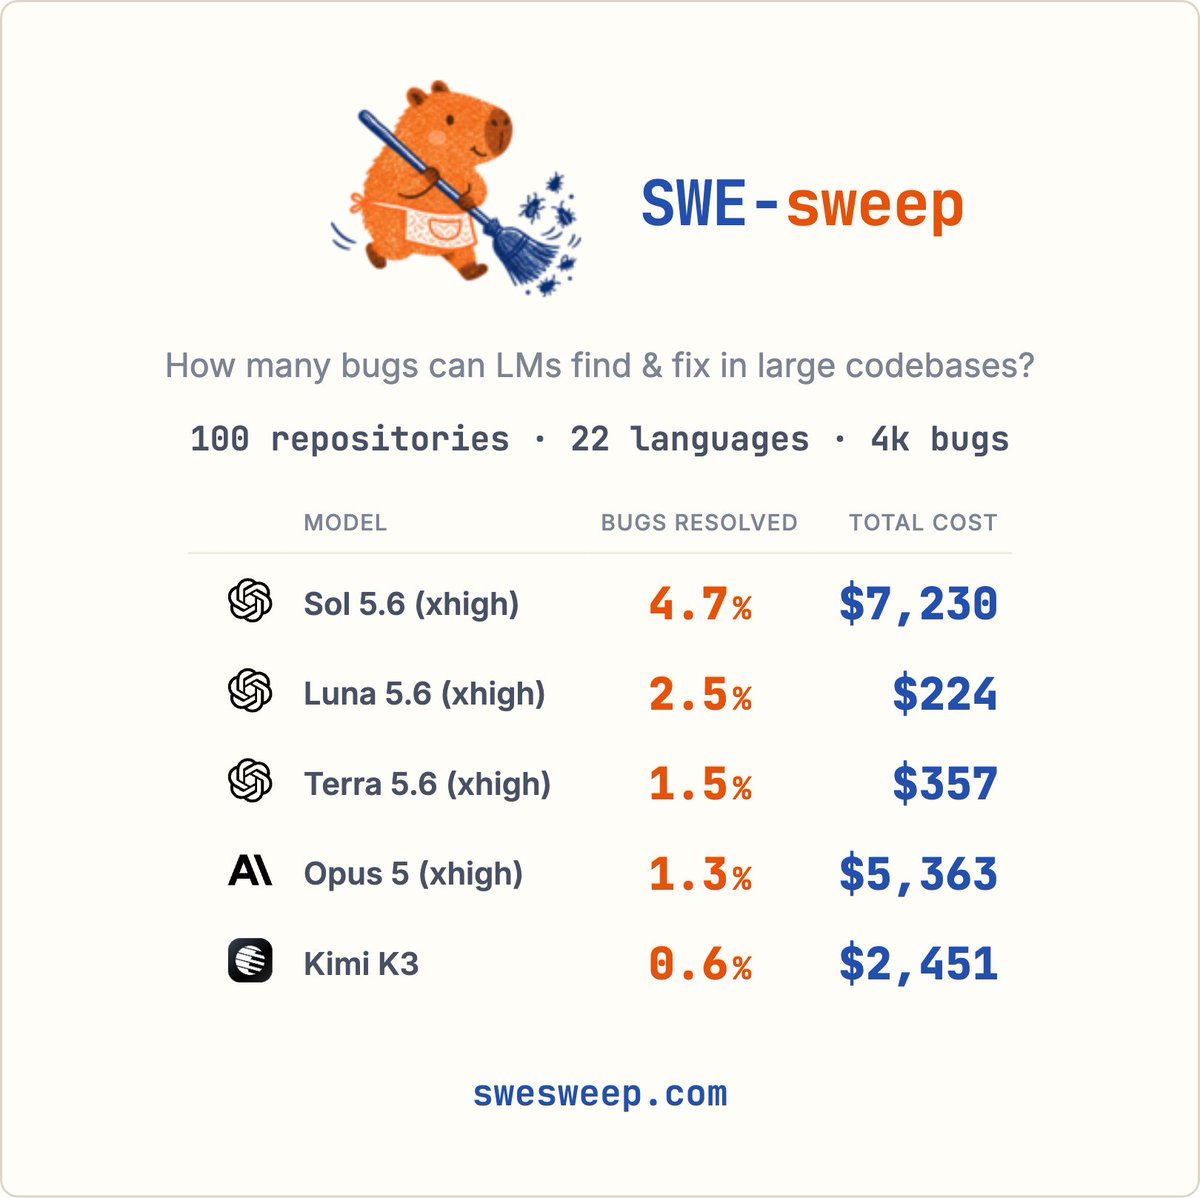
We evaluate this capability at scale. Introducing SWE-sweep! Led by 🐐 @KLieret
Can LMs discover & fix bugs if you don't tell them what went wrong? To proactively maintain a repo, agents need to find problems before users do.
SWE-sweep benchmarks this on 100 repos, 22 languages, 4k real bugs (numpy, php interpreter, lean kernel). Top models get <5%.
@harborframework Thanks for the prompt support. Looks Harbor only supports the single submission mode, doesn't yet support the submission/feedback loop @AlexGDimakis
@jxmnop The name means that’s the last benchmark human can given an answer. After it’s saturated there’re still further benchmarks but may without human answers