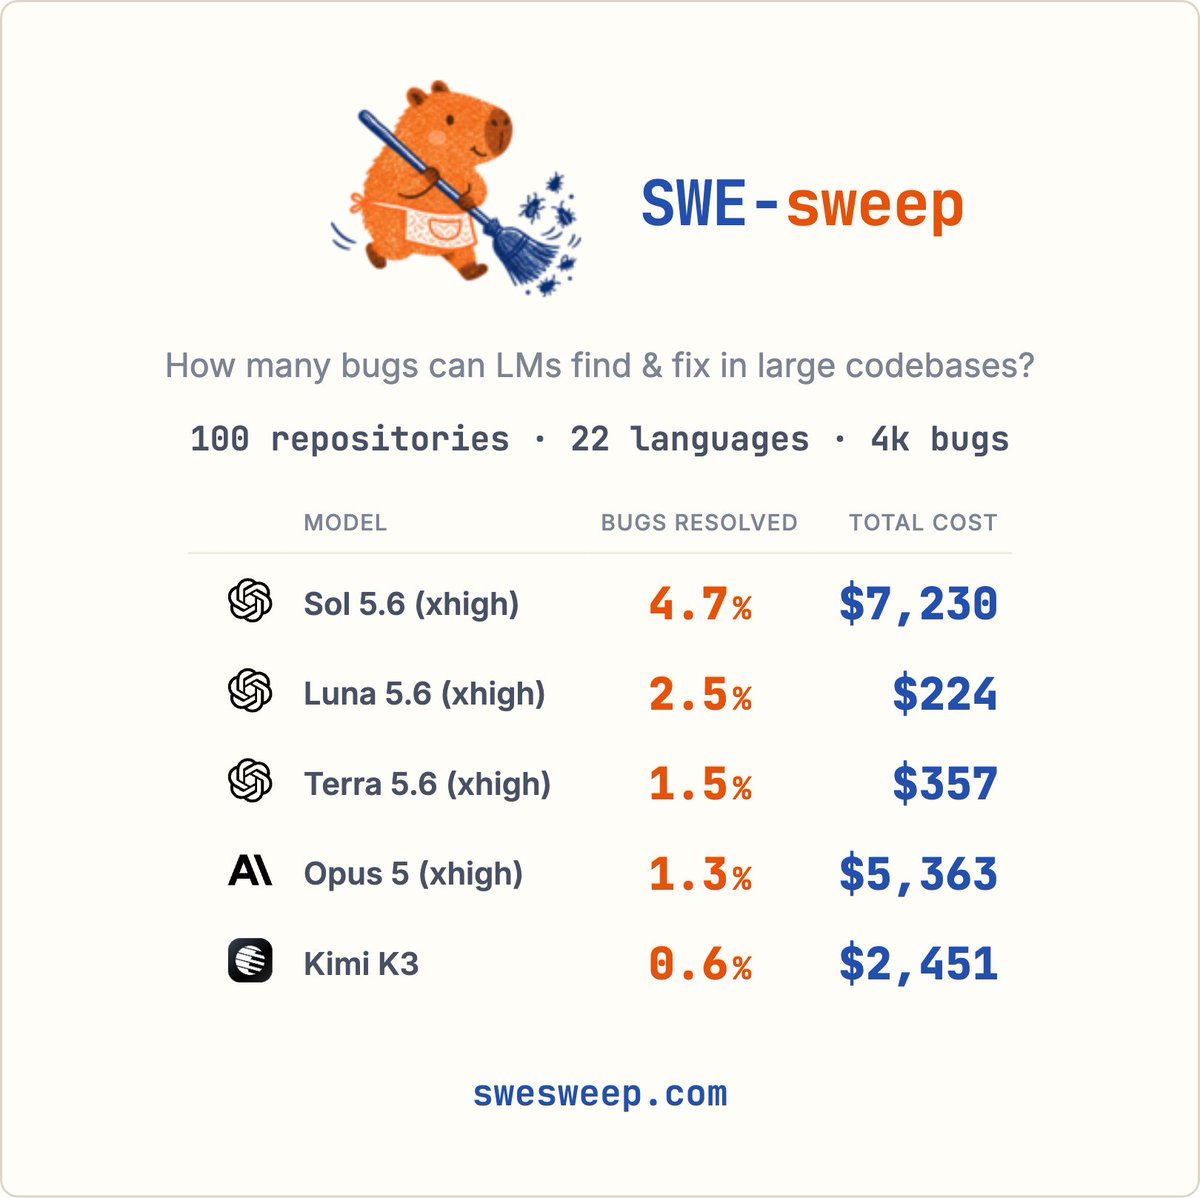
Can LMs discover & fix bugs if you don't tell them what went wrong? To proactively maintain a repo, agents need to find problems before users do.
SWE-sweep benchmarks this on 100 repos, 22 languages, 4k real bugs (numpy, php interpreter, lean kernel). Top models get <5%.
I burned a shitload of compute so you don't have to. Releasing the Harness Leaderboard.
Which harness should you run your open model in? I ran 28,849 trials to find out.
The leaderboard compares nine coding-agent harnesses on open models. In each comparison only the harness changes: the model, provider and reasoning effort stay fixed, and every task gets three attempts.
The trials ran GLM-5.3-Flash, DeepSeek-V4.1-Flash and Flint on Terminal-Bench 2.1 and DeepSWE, for $4,746 of inference.
Averaged over the three models, mini-swe-agent (@KLieret), a bash-only agent, solves 51.4% of tasks and @openclaw 27.3%. Four others are statistically tied with mini-swe-agent.
One of them is Pi (@pidotdev), at 49.4% for $0.29 per solved task, about 45% less than mini-swe-agent's $0.53.
The best harness depends on the model: mini-swe-agent on GLM-5.3-Flash, Hermes Agent (@NousResearch) on DeepSeek-V4.1-Flash and Kimi Code (@Kimi_Moonshot) on Flint.
@opencode costs $3.35 per solved task, 11.7 times as much as Pi.
See Harness Hub's Harness Lens for what the nine harnesses do differently. It documents the prompts, tools and compaction of 34 coding-agent harnesses and links every claim to its source.
Leaderboard: https://t.co/AiWiQtBOz5
Harness Lens: https://t.co/I8jbcWa9JH
I burned a shitload of compute so you don't have to. Releasing the Harness Leaderboard.
Which harness should you run your open model in? I ran 28,849 trials to find out.
The leaderboard compares nine coding-agent harnesses on open models. In each comparison only the harness changes: the model, provider and reasoning effort stay fixed, and every task gets three attempts.
The trials ran GLM-5.3-Flash, DeepSeek-V4.1-Flash and Flint on Terminal-Bench 2.1 and DeepSWE, for $4,746 of inference.
Averaged over the three models, mini-swe-agent (@KLieret), a bash-only agent, solves 51.4% of tasks and @openclaw 27.3%. Four others are statistically tied with mini-swe-agent.
One of them is Pi (@pidotdev), at 49.4% for $0.29 per solved task, about 45% less than mini-swe-agent's $0.53.
The best harness depends on the model: mini-swe-agent on GLM-5.3-Flash, Hermes Agent (@NousResearch) on DeepSeek-V4.1-Flash and Kimi Code (@Kimi_Moonshot) on Flint.
@opencode costs $3.35 per solved task, 11.7 times as much as Pi.
See Harness Hub's Harness Lens for what the nine harnesses do differently. It documents the prompts, tools and compaction of 34 coding-agent harnesses and links every claim to its source.
Leaderboard: https://t.co/AiWiQtBOz5
Harness Lens: https://t.co/I8jbcWa9JH
Running AI is expensive! @AnthropicAI's amended S-1 today shows $895B committed to compute and infrastructure but with Q3 revenue $17B and $567M loss, mostly from short-term compute.
@makermaker_ai can make it cheaper, better and faster with RSI. https://t.co/4BTjgaraqt 🧵1/7
@xeophon the other reason to use mini for benchmarks/research is that it's not going to really change. All other more complex agents are constantly evolving, so you can never quite compare model performance over time etc.
@xeophon (Wouldn't count litellm as an opinion, you can also write your own model class if you don't like it) My main claim is that mini is a good proxy for single agent performance and that gains on mini transfer to other (more complex) scaffolds.
I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model.
Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching.
We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards.
As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!
Congratulations to the Gemini team on reaching SoTA on SWE-sweep, scoring 9.6% (narrow leaderboard over Astra 6)! Hoping to update leaderboard with details soon!
Introducing Gemini 4 Carbon, it's a big jump over Argon which we released just 2 weeks ago.
Gemini 4 Carbon is SOTA on cyber, long horizon tasks, ranks #1 on Artificial Analysis V5, significantly improves on usability in domains like coding, and is more aligned.
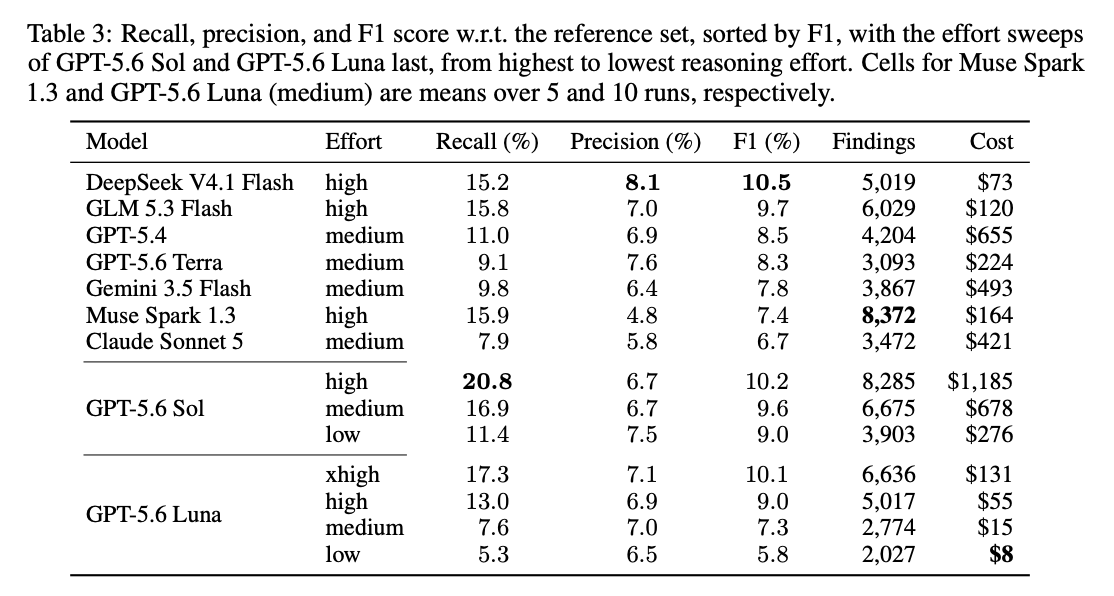
Very interesting study about proactive bug finding agents. Recall and precision are with respect to a holdout set of bugs that humans found, findings is the total number of bugs found
New paper: Frontier Coding Agents Find Different Bugs Than Maintainers Fix
In proactive bug finding, agents report fewer than 20% of the bugs humans fixed. But they report a lot of other bugs, most of which are valid. This points towards an important distributional mismatch.
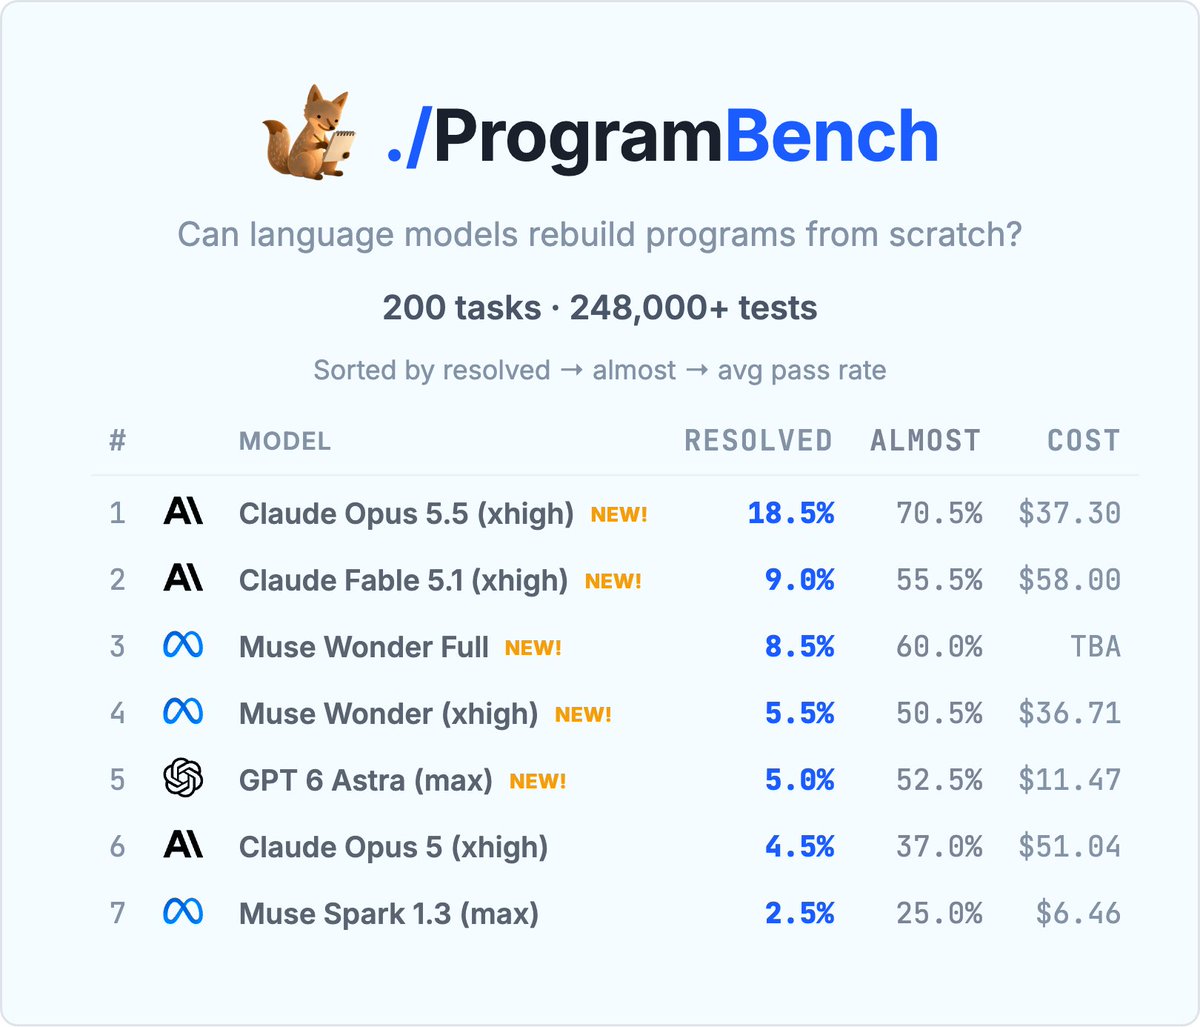
Progress on ProgramBench is crazy! When it was launched, every model had a flat 0% score and we were worried enough to introduce weaker metrics ("almost resolved" etc.), but things have certainly changed!
Agents can often fix a mistake by retrying, then forget what they just learned! Next session, same mistake 🥲
Introducing Self-Direction: each failure becomes a small, procedural adapter the agent trains on its own reflection and reuses later 💪🏽
🌐 https://t.co/SCCrlSf5ZT
🧵1/n
Saturating a benchmark that tests models on rebuilding ffmpeg is gonna take a fraction of the 3 yrs it took to saturate GitHub issue resolution.
Crazy times we live in.
We create SCARCE (Shared Compute ARena for Coding agEnts), where agents are given one execution sandbox and an independent ProgramBench task in which they have to reconstruct a real program from only its binary and docs, and execution time becomes a real bottleneck. Before every execution window, agents go through a time-slot auction: they declare a queue position, window length, and bid, optionally DM other agents, then rank everyone. We explicitly instruct them that bid price is the primary signal for resolving conflicts, so whatever emerges can’t be blamed on underspecification. Agents work through a sequence of tasks with a persistent memory tool and a self-written after-action report carried from one task to the next.