Model shaping is still a craft of a few. That's what AI agents are for: learning it and doing it for everyone else.
As a part of FrontierSWE benchmark we built a 20-hour post-training task on @tinkerapi and found the real bottleneck is research intuition.
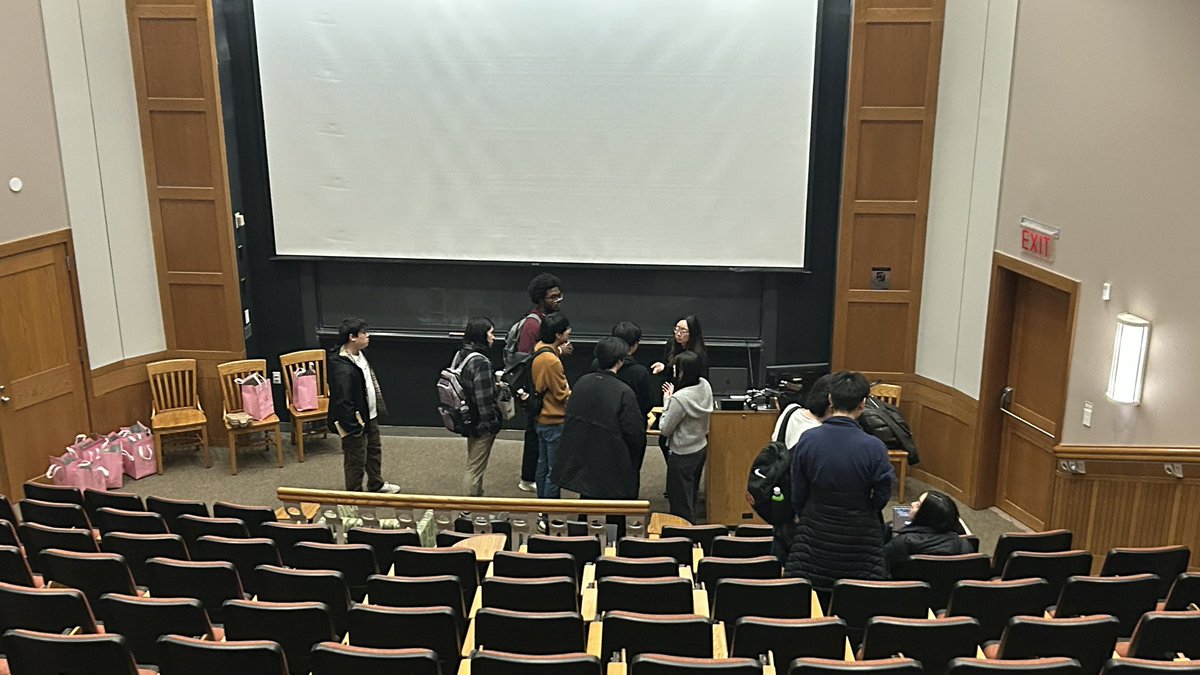
so happy and honored to have hosted @karinanguyen at Princeton last sunday!
loved hearing her insights on frontier LLM post-training, forecasting, and exciting evals. can't wait to see more from @thoughtfullab to bring RSI to the real world!
please come back! 💗
I'm excited to launch Benchmark Almanac! It tracks 3,322 benchmarks from 1,746 leaderboards, 522 launch posts, 346 system cards, and 1,233 open-source GitHub repos. To my knowledge, it's the most comprehensive repo out there.
Website: https://t.co/ARgu9TdU6x
We updated the eval table of the model card (https://t.co/AOUTemzyv8) with results from a few more private and semi-private benchmarks, along with official result verifications.
Big little announcement: @karinanguyen and I are excited to announce a brand new course on Full-Stack Post-Training, RL & RSI at @UCBerkeley.
If you are a Berkeley student and want to learn about the frontier, enroll for the next semester.
Excited to teach at @UCBerkeley again this spring! We’ve expanded the class to 200 seats for advanced undergrads and grad students.
We’ll explore the full frontier of AI: from pre-training, post-training, RL / inference-time scaling to autonomous agents, long-horizon reasoning & infra, and ultimately, applied RSI — systems capable of recursively improving themselves in real world.
after a year of deploying AI, i've learned that the tasks it performs best per unit of energy aren’t always the ones that create the most economic value. the counterintuitive part is that not everyone should own their intelligence bc the same compute can be worth much more in one business than another. hence, choosing where to deploy AI matters as much as how good you make it!
At Thoughtful, we’re studying the economics of intelligence through net value per joule (NVJ): how much economic value AI creates per unit of energy.
We were excited to collaborate on this paper, with @Mersad_Abbasi from our team contributing to the research. These ideas are already informing where and how we deploy self-improving AI in the real world. Learn more:
AI is using more and more of the world’s energy. But how much economic value are we getting from AI?
We’re introducing Joules-to-GDP (J2G), a framework that measures how well AI turns energy into economic value and shows which tasks, models, and hardware give the best return.
Across 44 occupations in finance, engineering, law, administrative work, and more in @OpenAI's GDPval, we arrive at three findings:
1) The tasks with the highest economic value are not the tasks with the highest economic value per joule. For example, CAD design earns ~10% more per task than building websites, but the latter earns ~27% more value per joule.
2) The most powerful model isn’t always the best use of energy. Gemma 4 31B delivers 56% of GLM 5.2’s net value with 23% of the energy, for 2.5x the value per joule.
3) More chips don’t guarantee proportionate returns. Moving the same model from 1 to 8 NVIDIA H100s uses 3.2x the energy but cuts completion time by only 22%, with about the same value.
With @SnorkelAI, we’re also releasing GDPWorks, a benchmark for economically valuable tasks across 36 additional occupations.
Joint work co-led by @amirzeinaalii and @Avanika15, with @Mersad_Abbasi, @Jon_Hartley_, John Hennessy, @HazyResearch, and @Azaliamirh.
More details below 🧵
On PostTrainBench, the top score for AI agents post-training a model went from 23% in March to ~45% in October. The labs' own models score ~51%. Asking @karinanguyen what's still missing.
https://t.co/HM9ow6XdgX
Nine frontier AI agents forecast all 863 midterm races and traded real money on them. The best forecaster lost 77%.
@karinanguyen (@thoughtfullab) on what BallotBench learned and whether agents can train models yet. 9:30a PT on AI:AM w/ @labenz + @8teAPi
https://t.co/HM9ow6XdgX
On Arena-Hard Writing, it read the judge's feedback and changed its diagnosis: "This is an INSTRUCTION-FOLLOWING problem, not just style." Inkling 2 generated ~6k writing briefs with explicit constraints and distilled a local open 72B model on them. Gemma 3 4B went from 0.3% to 23.9%.
PostTrainBench is one of the first benchmarks for autonomous post-training: AI agents source data, train smaller models, and evaluate their performance. It’s part of our growing work on applied recursive self-improvement.
Inkling 2 Small is a great American open model, showing frontier-level performance at autonomously improving other models.
With just 17B active parameters, it scores 31.87 on PostTrainBench, ahead of Kimi K3 (31.48) and GLM 5.2 (30.40), and on par with GPT-5.6 (Sol) and Opus 4.8 (~31).
We’re excited to have partnered with @thinkymachines to evaluate Inkling 2 Small, a promising step forward for American open-source AI.
On HealthBench, its first model scored 2%, because most answers were empty. A next-token probe and a look at the data showed why: "HealthBench conversations are ALL multi-turn." 99% of its training data was single-turn.
Inkling 2 added synthetic multi-turn data and brought its official score up to 31.4%.
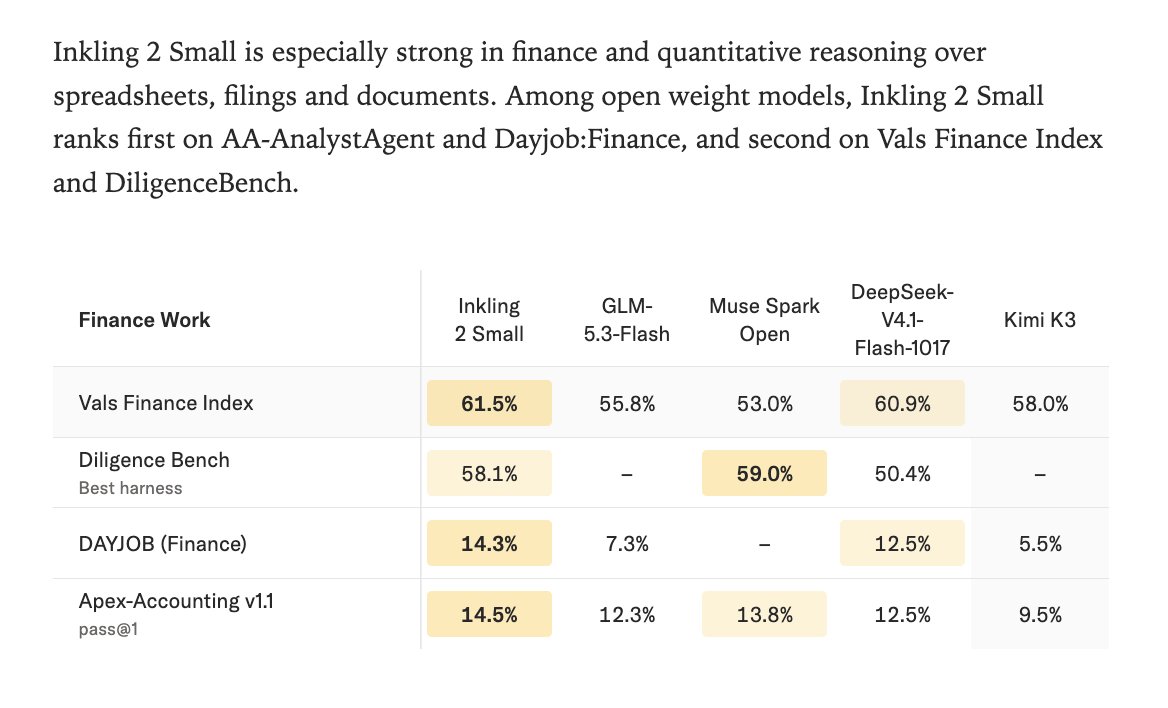
5/ Despite having no dedicated SEC tools, Inkling 2 Small scores 58.1, compared to 57.5 with them. This suggests that, at least for this benchmark, a sufficiently capable agent can reconstruct much of the functionality of specialized tools from a general-purpose execution environment.
DiligenceBench is an public equity research agent evaluation measuring factual accuracy, analytical reasoning, and risk awareness across 150 tasks spanning energy, banking, biotech, insurance, technology, REITs, restaurants, industrials, and utilities.
Learn more: https://t.co/VfrCutui9X
Inkling 2 Small can generate a full public equity diligence memo for just $0.69 using our finance harness.
We got early access to the model from @thinkymachines and have been evaluating it on DiligenceBench, where it’s performing remarkably well. It’s a 594B-parameter MoE model with 17B active parameters, priced at $0.30/M input and $1/M output tokens.
4/ One interesting behavior is how it uses a shell environment. On 149/150 tasks, the agent wrote or ran Python, downloaded SEC filings directly from EDGAR, and worked around 90% of the access blocks it encountered.