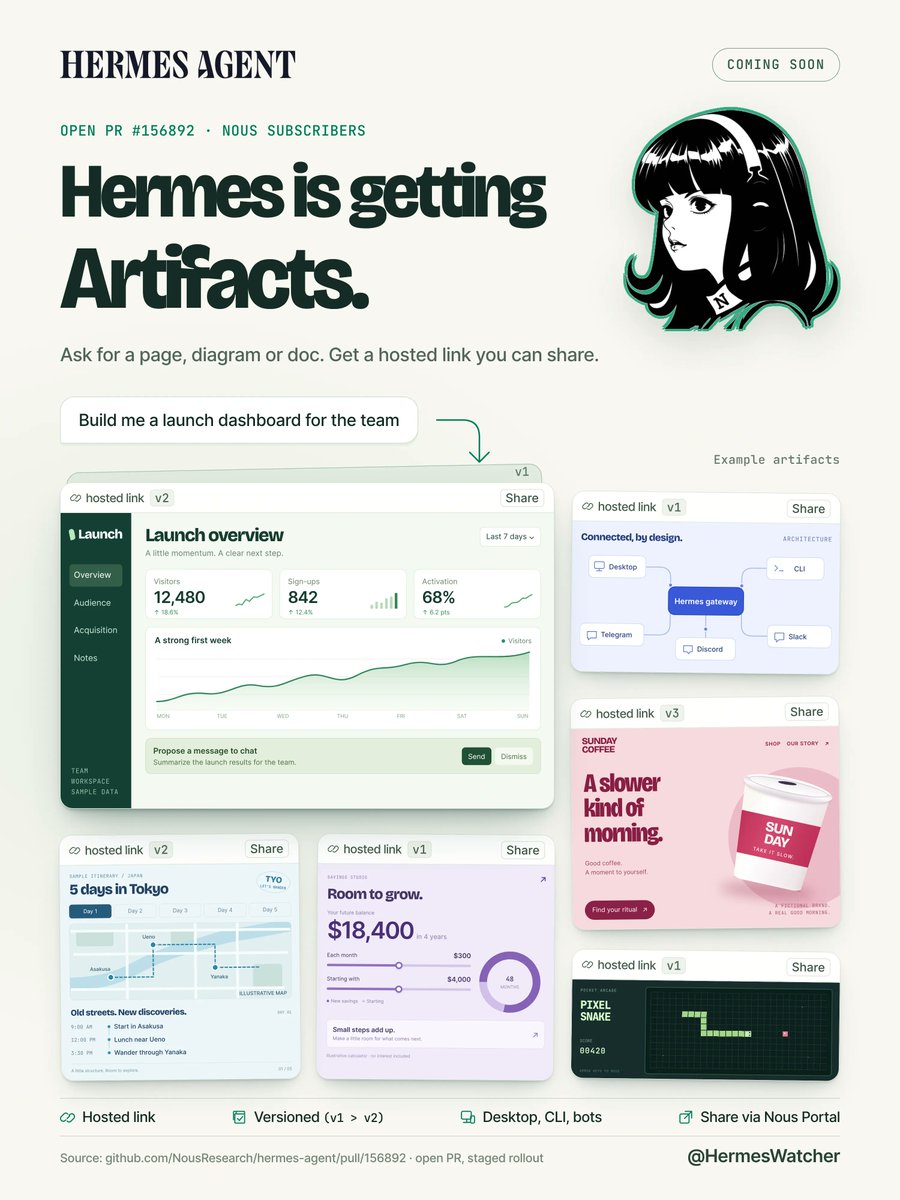
🚨 BREAKING: HERMES IS GETTING HOSTED ARTIFACTS.
Ask Hermes for a page, a diagram or a document, and it should come back as a real link you can share.
Here's what's coming for Nous subscribers:
▸ Hosted by Nous, with a link you can send your team
▸ Versioned, so Hermes can update the same one in a later session
▸ Interactive, so a page can send a message back to your chat
▸ Works from Desktop, the CLI and your messaging bots
▸ On Desktop it should open right inside the chat
▸ View and share them in Nous Portal
Rollout should go in stages, so not everyone gets it on day one.
You'll hear it here when it lands.
Something is going on at Google
I think they might have hit RSI
They’ve released new frontier models FOUR TIMES in less than a month. And each is an actual MAJOR improvement
Carbon is the most intelligent model I’ve ever used
While everyone is talking about Anthropic and OpenAI, Google quickly caught up
What I absolutely love about these models too is they were clearly trained in a completely different way than Claude or ChatGPT. 0 distillation.
They talk, think, write, and code COMPLETELY differently than any other model
I can always count on Carbon to give me a novel insight no other model has given me
If you haven’t incorporated Gemini into your tool belt yet, you absolutely need to
BRIDGEWATER:
“.. we are managing money based on a one-in-three chance of an economically destabilizing attack within the next year.”
https://t.co/Y7URGCN8zg
Venezuela ETF finally listing today!
• Teucrium Venezuela Future Opportunities ETF | Ticker: VEN
Expense ratio: 0.95% | CUSIP: 53656H660
Tracks the MarketVector™ Venezuela Future Opportunities Index.
This is an example of an "access" ETF strategy. As the Venezuelan market is probably not ETF-investable yet, the index is a mish mash of local and international companies. In the absence of any other ETFs this is the only option for Venezuela exposure in an ETF wrapper for now. The expense ratio, high by any measure and especially for an equity index ETF at more than 4x the average ETF fee, reflects this exclusivity.
The only other ETFs close to this $VEN are two Corgi filings from January:
• Venezuelan Liberation ETF
• Venezuelan Liberation 2x Daily ETF
Strategy is similar to $VEN but actively managed. Prospectus is here:
https://t.co/PPZYdH0BiI
$VEN index could evolve at some point into a full blown Venezuela stock index, and fees could come down as the local market matures and other issuers Venezuela ETFs.
Index: Venezuelan companies, or companies with exposure to Venezuelan economy: those with joint ventures with the country's oil company, holding OFAC licenses to do business in Venezuela, have claims against Venezuela, industrial suppliers to Venezuela. Indeed had 51 names as of October 31.
ETF website:
https://t.co/Clt1PQaKwd
$VEN summary prospectus @ the SEC:
https://t.co/I7RdOFz13q
#Venezuela @TeucriumETFs
How much does an American family need to never work again?
A family of four in the main city of each state: a three-bed in a good neighbourhood, one kid in private school, two cars, part-time help at home, health insurance and a few trips a year. All paid by ETFs, after tax, forever.
The answer: somewhere between three and seven and a half million, depending on the state.
The Dakotas are the cheapest. New York is evidently in a league of its own, because Manhattan rent and city tax push it past seven million.
Health insurance alone costs a family around thirty thousand dollars a year, which is why the US never gets really cheap.
Florida and Texas don't tax your gains, but rent and insurance eat most of the advantage. Miami ends up pricier than most of the country.
The criteria: city costs and rent (Livingcost), what a family pays for health insurance in 2026 in each state (KFF), a global ETF portfolio averaging about 7% a year with a couple of points left in for inflation, grossed up for federal, state and city tax on gains.
Looking at your state, does this estimate feel right?
BREAKING: A major submarine internet cable "SEA-ME-WE 5" has suffered an unknown fault near the Gulf of Oman, 11 km off Pakistan's shore, causing a decline in internet connectivity across the country, per Pakistan's telecom authority.
SMW5 is one of the main Asia-Europe backbone cables, running roughly 20,000 km from Singapore through Karachi, Oman, the UAE and Saudi Arabia to Europe.
It comes a month after Iran drew up detailed plans to target the 7 undersea cables in the Gulf if it is attacked again, and said it would aim to prevent repairs to prolong the disruption.
I don't think prompt-injection filtering can be a security boundary for agents on its own. OWASP maps nine dimensions of prompt injection, and a filter tuned for one misses the others, so enforcement has to sit at the action layer.
For each agent-to-tool integration, decide which layers you rely on: input filtering, a logged runtime check per action (allow, ask or block against a declared policy), and a sandbox that limits the damage if the model gets it wrong.
For an agent with database access, reads are allowed, writes need human approval, schema changes and exports are blocked, and everything runs in an isolated sandbox with scoped credentials. If you can only name the first layer, I think that is your real answer.
🚨We urge orgs to immediately patch the recently disclosed Oracle Java vuln CVE-2026-114938. This critical memory-corruption vulnerability, known as “Java4Shell,” affects the Base64 decoder of the x86-64 HotSpot JVM, part of the Java Development Kit. 🔗https://t.co/SwrhdPFlZF
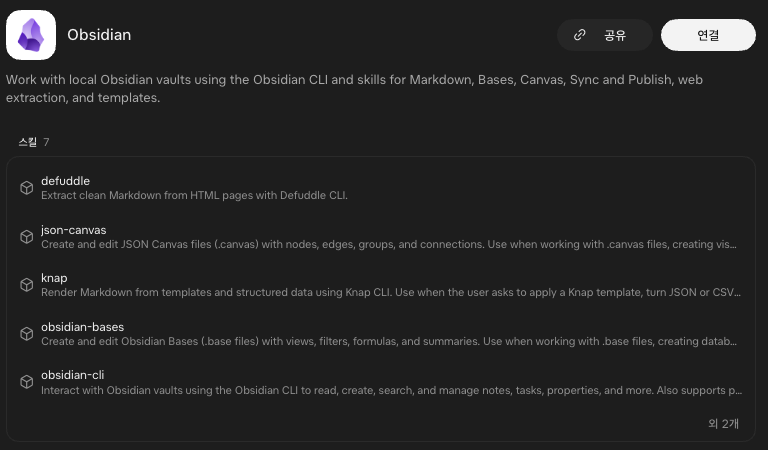
그록봇에 공식적으로 옵시디언이 들어왔습니다.
이제 봇들에게 세컨드 브레인이 생겼습니다!
대박입니다.
네이티브하게 @bot 이 이제 옵시디언을 사용하게 되었습니다.
진짜 이제 더욱더 옵시디언이 쉬워지며,그록봇들간의 브레인을 공유하며,실수를 기억하고 자가진화하는 봇으로 만들수 있습니다.
기본적으로 어떤 스킬을 제공하는지 알고 옵시디언을 시작하시면 진짜 사람이 할게 없다는걸 아실겁니다.
1. defuddle.웹페이지(HTML)에서 깔끔한 마크다운만 뽑아내는 스킬.
웹페에지에서 광고나 메뉴 같은 잡동사니 빼고, 본문 내용만 깨끗하게 가져와서 옵시디언 노트로 넣을 때 쓰임.
2. json-canvas.옵시디언의 Canvas(캔버스) 기능을 다루는 스킬.
캔버스는 노트를 카드처럼 배치하고 선으로 연결하는 시각적 보드(마인드맵 같은 것)인데, 이걸 JSON 파일로 만들고 수정할 수 있게 해줌.
3. knap.템플릿을 써서 데이터를 마크다운으로 만들어주는 스킬.
JSON이나 CSV 같은 구조화된 데이터를 미리 만든 템플릿에 넣어서, 보기 좋은 옵시디언 노트로 자동 변환할 때 사용.
4. obsidian-bases.옵시디언의 Bases 기능을 다루는 스킬.
Bases는 여러 노트를 테이블이나 데이터베이스처럼 보고, 필터·정렬·계��·요약을 할 수 있게 해주는 기능인데, 그걸 파일로 만들고 편집할 수 있다.
5. obsidian-cli.가장 핵심적인 스킬.
옵시디언 앱을 켜지 않고도 명령줄로 Vault 안의 노트를 읽고, 만들고, 검색하고, 수정하고, 태스크나 속성을 관리할 수 있게 해준다. AI가 옵시디언을 직접 조작할 때 주로 이걸 씀.
6. obsidian-headless.옵시디언 데스크톱 앱 없이도 Vault를 동기화하고 퍼블리시할 수 있게 해주는 도구스킬.
서버나 다른 환경에서 Vault를 최신 상태로 유지하거나, 웹으로 공개하고 싶을 때 사용.
7. obsidian-markdown.옵시디언만의 특별한 마크다운 문법을 제대로 써서 노트를 만들고 수정하는 스킬.
일반 마크다운과 달리 [[위키링크]], ![[임베드]], 콜아웃(강조 상자), 속성(Properties) 같은 옵시디언 전용 문법을 정확하게 다룰 수 있다.
제가 GrokBot의 메모리 시스템을 어떻게 만들었는지 궁금하시다면,인용한 ���시글을 참고하세요.👇
https://t.co/2z5L0YdegC
5 charts suggesting Warsh has hiked interest rates into the largest deflationary event in history-the advent of AI.
Greenspan early on the job hiked rates in '87, Bernanke similarly kept policy tight into summer of '07. Both had to reverse...
But only after the mkt revolted.
Commodities have been the best-performing asset class of the decade. So why is one of the world's leading commodity strategists telling investors to take profits?
Jeff Currie @CommodMkt called the commodity supercycle in 2020, but he's no permabull. Ahead of the U.S. midterms, he made a tactical short call, warning that the geopolitical forces driving the latest rally were about to shift.
But don't mistake his short-term caution for a change in conviction. Currie argues the biggest opportunities come from massive, unmistakable supply-demand imbalances—not trying to predict every twist and turn in the market.
So where does he see the next big opportunity, and why does he believe the commodity supercycle is far from over?
🎥 Watch the full conversation on In the Money with Amber Kanwar. https://t.co/LKWFqI9PA3
#JeffCurrie #Commodities #Investing #CommoditySupercycle #StockMarket #InTheMoney
Introducing Qwen3.8-27B-pi-adapted 🤗
We adapted Qwen's model specifically for the pi coding agent using reinforcement learning and a LoRA adapter.
The results, measured as pass@1:
🚀 SWE-bench Pro (Hard 51): 29.4% → 62.7%
💻 Terminal-Bench 2.1: 39.5% → 55.8%
⚡ 55–62% fewer tool calls per task
This is the power of open models: you can adapt them to YOUR tools and YOUR use cases. Let’s build! 💛
Open weights: https://t.co/aH4cl2qnED
Methodology: https://t.co/avSfF93K4V
Snowbird's 15.7 inches of water since the start of the water year (Oct 1) is the most ever on this date! Yet, we are only at 67% snowpack. Not to beat a wet and warm horse, but that's a crazy statistic.
This is insane. Hermes is making films on your own machine now. 🎥
A trailer. A product ad. A music video. A short film.
You pitch it in chat. Hermes shoots the clips, casts the voices, scores it and adds the sound effects.
Directed by Hermes.
Imagination Studio for Hermes plugs Hermes into a full AI film studio running on your own hardware. From any chat, Hermes makes:
▸ Pictures
▸ Video clips with sound
▸ A voice line in any voice you describe
▸ Songs
▸ Sound effects
Every file lands back in the conversation, and long renders run in the background while you keep going. Works from Hermes Desktop, the terminal or Telegram.
Inside the Studio itself you can write the script, plan every shot, pick the look and cut the film.
It all renders locally, from DGX Spark and RTX PCs to Apple Silicon Macs, and your files stay on your machine.
Setup: install Imagination Studio on your machine, add the plugin from the official Hermes catalog, then ask Hermes.
Built by @u1tra_instinct and @SamJWasserman.
🆕 A new 9B model beats Qwen3.6-35B and Qwen3.6-27B in some benchmarks. New local model winner?
RTX 3060 12GB owners, are you watching?
And @SenseTime_AI says it runs w just ~9GB of GPU memory at 64K context.
🎯 What's the trick? Make the same model layers work twice.
This is SenseNova-Loop-9B and it was recently released.
Model Stats ...
🧠 ~9B stored parameters
⚙️ ~14.6B inference-equivalent parameters
📚 Up to 512K context
👁️ Text + image inputs
🔓 Apache 2.0
💾 Official 4-bit AWQ weights ~4.9GB
Look at the architecture
Normally, a Transformer runs each layer once.
SenseNova does something different.
👉 32 distinct decoder layers
👉 Layers 4–27 execute TWICE
👉 56 total layer executions per token
👉 Shared weights between passes
👉 2-stream manifold-constrained hyper-connections (mHC)
👉 Hybrid linear + full attention
It uses more computation without storing more copies of the model weights.
Reported results
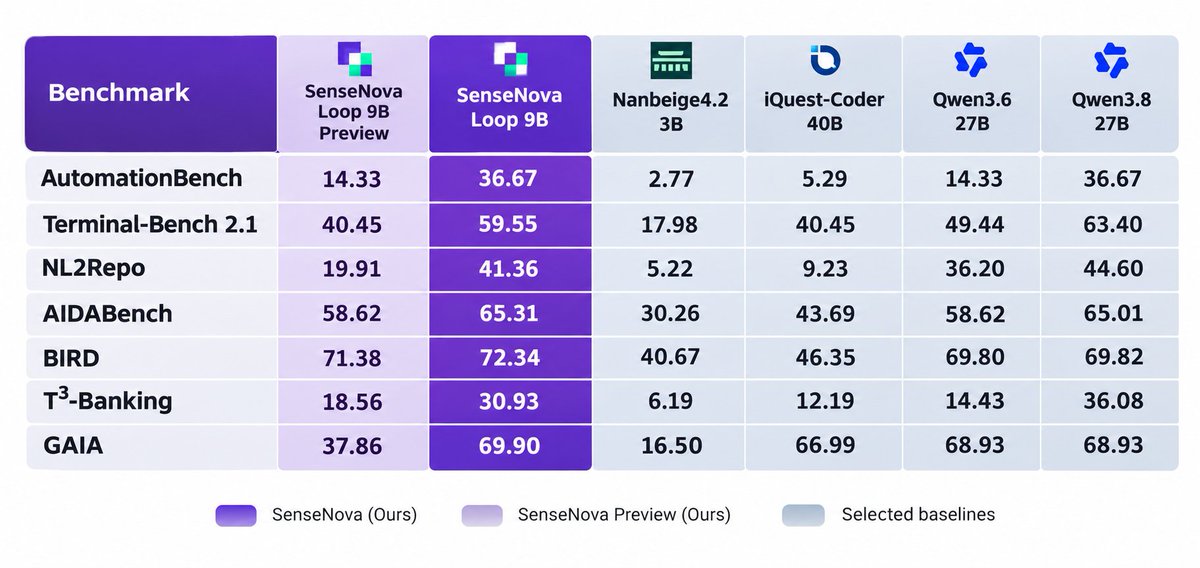
Preview → New Release
🤖 AutomationBench
14.33 → 36.67
💻 Terminal-Bench 2.1
40.45 → 59.55
🧑💻 NL2Repo
19.91 → 41.36
🔎 GAIA
37.86 → 69.90
And compared with Qwen3.8-27B:
Model → SenseNova 9B / Qwen 27B
⚙️ AutomationBench → 36.67 / 36.67
📊 AIDABench → 65.31 / 65.01
🔎 GAIA → 69.90 / 68.93
💻 Terminal-Bench → 59.55 / 63.40
🧑💻 NL2Repo → 41.36 / 44.60
Not a complete win, but impressive for a model with roughly one-third the stored parameters.
SenseTime's estimated GPU memory requirements for 4-bit weights:
💾 64K context → ~9 GiB
💾 128K context → ~10 GiB
💾 256K context → ~12 GiB
Using a 4-bit KV cache.
RTX 3060 12GB owners, are you watching? 👀
Independent analysis of the Preview's weights found strong evidence that it builds on Qwen3.5-9B, with additional training and new mHC routing layers.
So this isn't simply a newly pretrained 9B model.
It's an experiment in getting more intelligence out of existing model weights by repeatedly processing information.
⚠�� More layer executions mean more compute per token.
⚠️ We still need actual consumer GPU tokens/sec.
⚠️ The final model needs compatible inference support.
⚠️ The 512K maximum context is not a 9GB VRAM claim.
SenseNova's official 4-bit AWQ quantization has been announced, but I haven't yet verified a direct download for the final checkpoint so we will have to wait
Community GGUF quants already exist for the earlier Preview, including Q4_K_M, Q5_K_M, Q6_K and Q8_0.
But they currently need a modified llama.cpp build.
Standard LM Studio and Ollama support isn't established yet.
And remember, looping the layers means MORE computation per token, even though the model stores fewer weights so we want to see
⚡ Tokens/sec on an RTX 3060 12GB or RTX 5060 Ti 16GB.
And the Hugging Face weights currently require accepting repository access conditions.
Links in reply
NVIDIA just released a speculative decoding draft on Hugging Face
It accelerates Qwen3.8-27B with 4B parameters, boosting token acceptance by 46% over the built-in head.
https://t.co/xKp3i7wGgU