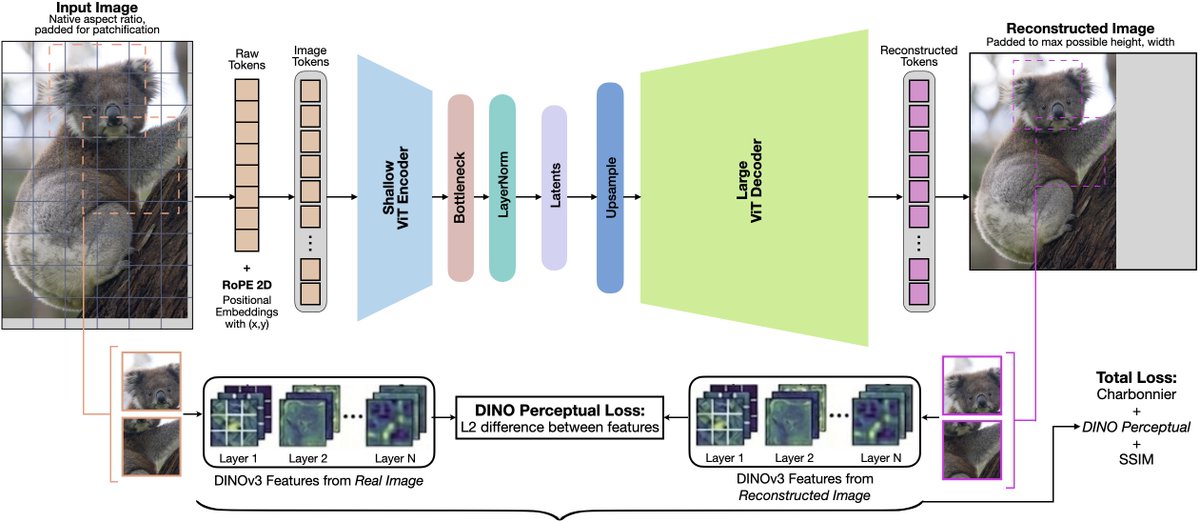
Releasing ViTok-v2: open-source ViT auto-encoder codebase + pretrained weights
Train your own ViT auto-encoder on any streamed (hf://) or local webdataset. NaFlex pipeline handles any resolution and aspect ratio
Includes reproduced 350M and 4.5B models weights competitive at 256p, SOTA at high-res (512p+)
@jnconkle@PurpleDrink_LLC Also the made up guaranteed 14-20% return in the market…. That’s not how markets work.
Though markets do outperform housing and should do so vastly for a healthy(er) economy.
The tech report behind our 6x pretraining compute multiplier is out today.
Training LLMs for data research takes more scientific control than training one great model does. Even small changes can confound results.
Some spoilers on how we did it:
https://t.co/kyNZ9XUFkj
We’re releasing all 57 intermediate checkpoints from Marin “Mochi” 535B-A23B pretraining, including 10 from long-context extension. 18.2T tokens, about 61 TB of weights.
https://t.co/MmfZeQdB1V
Blog: https://t.co/kNCJ6PoNW5
@DeepDishEnjoyer cannot really run an multi-agent coordination system. Nor can it code as well, but it works and can kinda be used like a claude code. Which is huge
@nu_arupaka@AgustinLebron3 if PEP lost 50% of the their earnings in a yearm you'd assume we are all starving. If nvidia lost 50% of their earnings in a year, its just another cyclical year