caliber is the intelligence layer for how your org runs on AI.
plug in your HRIS and see:
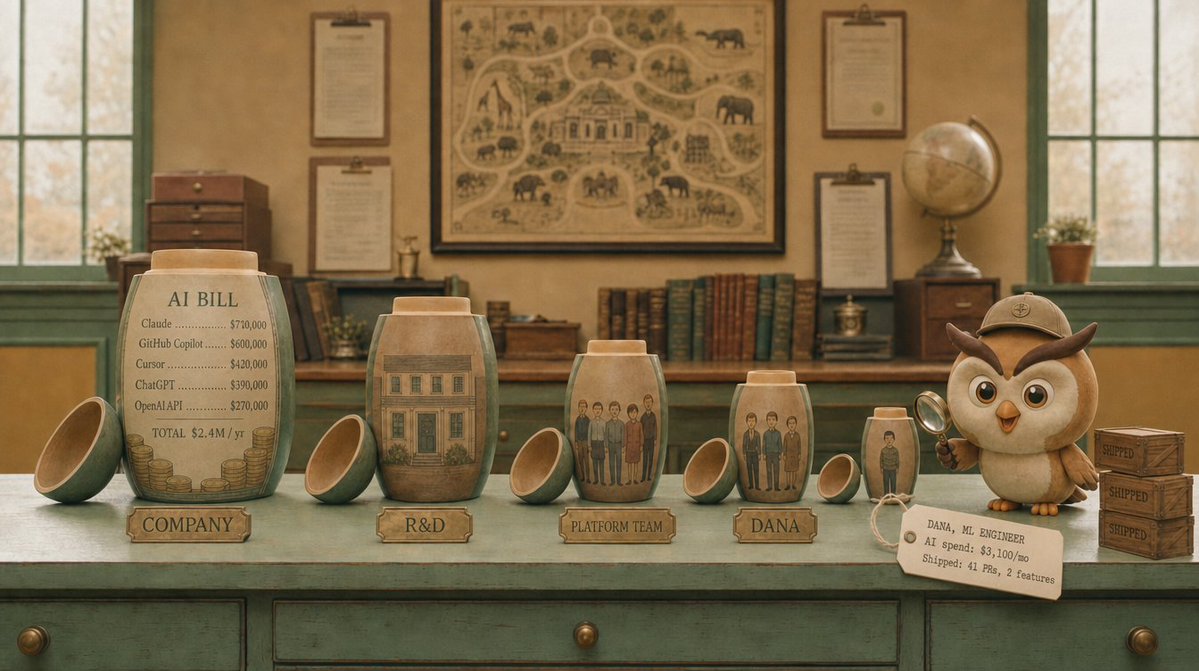
- AI spend by team and by owner
- $ per shipped item, per team
- every seat, key and agent, plus unused ones
already live with paying customers.
https://t.co/NrZTSmMKXu
@dusangran@nateberkopec /context is underrated. the same thing at team level is where it gets interesting, a few heavy setups usually drive most of the bill and nobody knows whose they are.
@thereisnobeth@shoshovelvel the savings get counted per headcount, the spend lands as one vendor line. until both sit on the same team view, nobody can actually prove the roi either way.
@askshashanka managing token costs is hard mostly because nobody can say which team is spending them. once usage sits next to the org chart, the conversation gets a lot calmer.
@BallaTheSenior@Lamoosooki@valigo curious if that spend is tracked per team or just one big line item. most shops we talk to can't tell who's actually driving it
@ns123abc meta halving claude code users while still paying $105m a month says the cut went by headcount, not by who was actually shipping with it. the better version is seeing that per team and per person on the org chart before anyone picks a number.
@KrisPatel99 a third off the top is the blunt version of a cut. the harder part is knowing which teams were getting real work out of it before you take it away.
@Loofyb0i routing fixes the per call price. the part that still bites at a company is nobody can say which team's sessions those forks came from. the bill names the model, not the owner on the org chart.
@goodalexander the atlassian point is the one that sticks. managers need a harness because seats and agents show up faster than anyone writes down which team owns them.
@RoundtableSpace the /usage command is the missing feedback loop. pairing it with /advisor opus makes the quality tradeoff visible instead of guessing from the invoice.
@thegadgetsfan@cursor_ai that wasted spend usually hides in repeated context, not just the model choice. checking cache reads and fresh input per task would make the leak visible.
@mardehaym Adoption rates are useful only when tied to output. The missing control plane is spend and throughput by team, owner, workflow, and shipped item—then you can see which seats, keys, and agents are idle.
@himanshu231204 Exactly. $/successful PR is the outcome metric; add team and owner attribution plus the cost of idle seats, keys, and agents, or the denominator hides where spend is leaking.
@gsantamarina Forecastability is step one. The harder part is seeing spend by team and owner, plus cost per shipped item, across seats, keys, and agents—including the idle ones.
putting a cap on tokens is easy. knowing which team burned through it, what shipped, and what broke after launch is the hard part. a cheaper model won't fix a workflow nobody owns.
@parvez__ that Linear issue -> agent -> PR loop is the part most teams miss. the tool list is easy to copy; the handoff needs an owner, review point and a way to see whether the change actually shipped. more agents without that just make a faster backlog.