GTA VI is out!!!
every big streamer is live for 12–15 hours
one moment in there gets millions of views, whoever posts it first wins
so i built HEISTCLIP
paste a yt/twitch/kick link → it watches live, catches the moment, captions it, frames it vertical, drops it in your library
~50 seconds from moment to ready-to-post
https://t.co/SdIy2X7hS7
tokenized stocks this week, demand vs supply:
▸ demand: binance wallet's tokenized anthropic pool hit its $500m usdc cap ~4h into an 8h window
▸ supply: okx x ice picked 62 companies for its 24/7 venue. 56 objected
▸ so it opens monday w/ mostly crypto names (coinbase, circle, strategy, robinhood) + 59 direxion etfs
users clearly want it. issuers don't. who blinks first?
usage is compute-based (5-hour refresh, weekly cap). no published "n free tasks/day." free schedules: at most once a day, 10 active. max 15 tasks at once. calling isn't in IN, LA, MN, MT, or NE.
elsewhere: google ai pro or ultra.
https://t.co/E6D5VoRIN0
https://t.co/czVkgNTxcY
that's tasks in gemini (chat → task, gemini 4 hydrogen), not the whole app, not google tasks. 18+, personal account, history on. not work/school.
"for now" — no published end date. calling, pay, email, and sms start in the us. still out: eea, uk, switzerland, nigeria.
Put Gemini to work for you with Tasks.
While Chat is for quick back-and-forth answers, Tasks are for longer projects and recurring schedules.
Beginning today, Tasks are now free of charge for hundreds of millions of eligible users, starting in the U.S., JP, KR, CA, AU & IN. 🧵
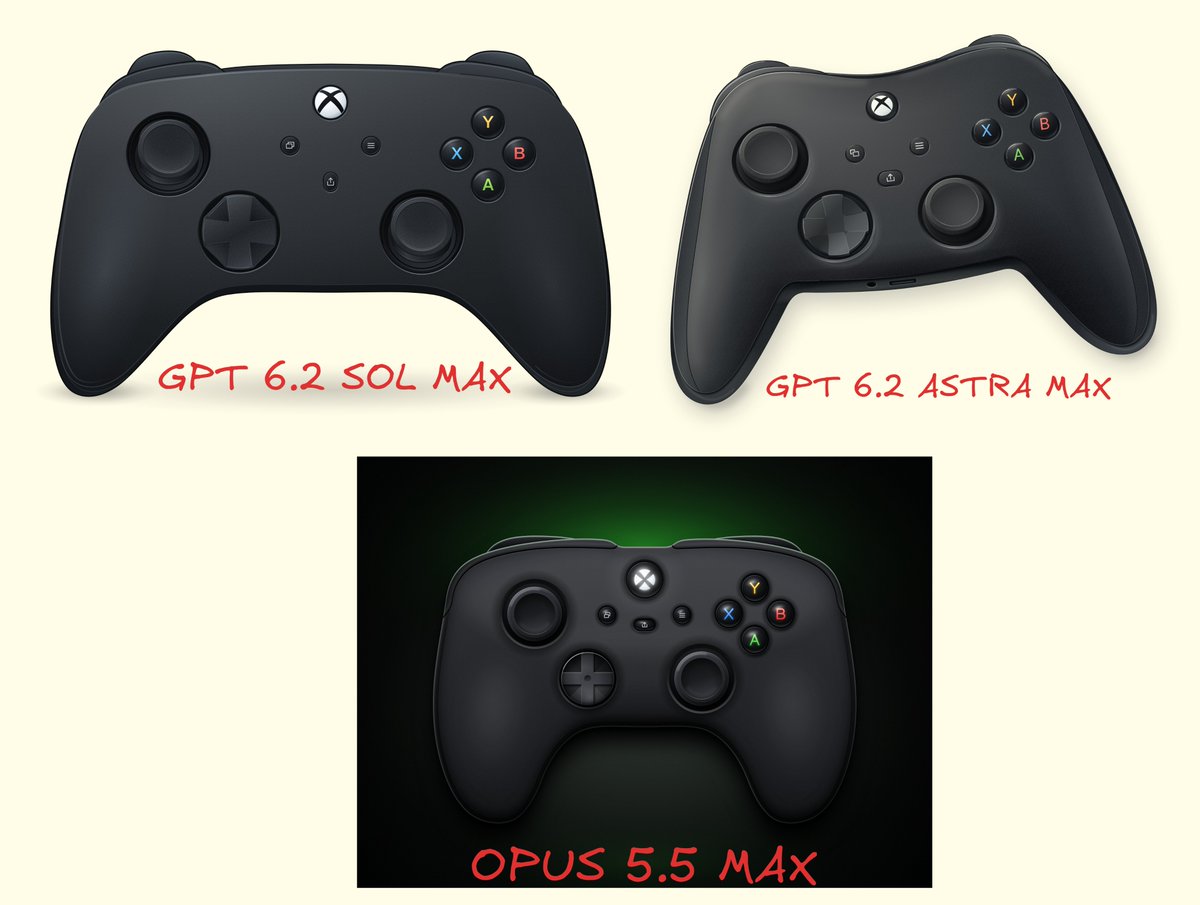
n=1, per @notjazii (xbox-controller, max reasoning, quality as a poll): sol $0.53 / 9 min, astra $1.24 / 38 min, opus $7.49 / 20 min. cost direction matches aa; 38 min does not (aa: 10.7 vs 24.5). not a coding bench.
https://t.co/j5L1b3ZVLy
https://t.co/zdkW9tTDRa
GPT 6.2 vs Opus 5.5
tested all three models with same prompt at max reasoning and results are here
> 6.2 sol took 9 mins and cost $0.53
> 6.2 astra took 38 mins and cost $1.24
> opus 5.5 took 20 mins and cost $7.49
i’ll let you all judge which one did better in this test
official list (standard, short context, per 1m): sol $2/$10, astra $8/$40, opus 5.5 $4/$20.
list ≠ cost per task. per @ArtificialAnlys (max): sol $1.01 / 7.9 min / 57, astra $4.00 / 10.7 min / 62, opus $10.04 / 24.5 min / 59. opus costs more per task because it's more verbose
anthropic priced at $83, $5 above the range. the @tradexyz ANT perp is at $100.2 right now, before a single share trades on nasdaq
▸ that's +21% over the ipo price
▸ $174m open interest, $99m traded in 24h
▸ it sat at $96-99 all of yesterday, the pricing news barely moved it
onchain already priced the day-one pop. later today nasdaq tells us if it was right
tokenized assets, per @JupiterExchange's coo at breakpoint:
▸ $460bn tracked (https://t.co/OmthLMirou)
▸ $39.5bn can actually leave the issuer's platform
▸ $3.4bn used in defi (defillama)
meanwhile @tradexyz on hyperliquid carries ~$4bn of open interest in stock and commodity perps, with zero shares tokenized.
traders want the exposure. the wrapper is optional.
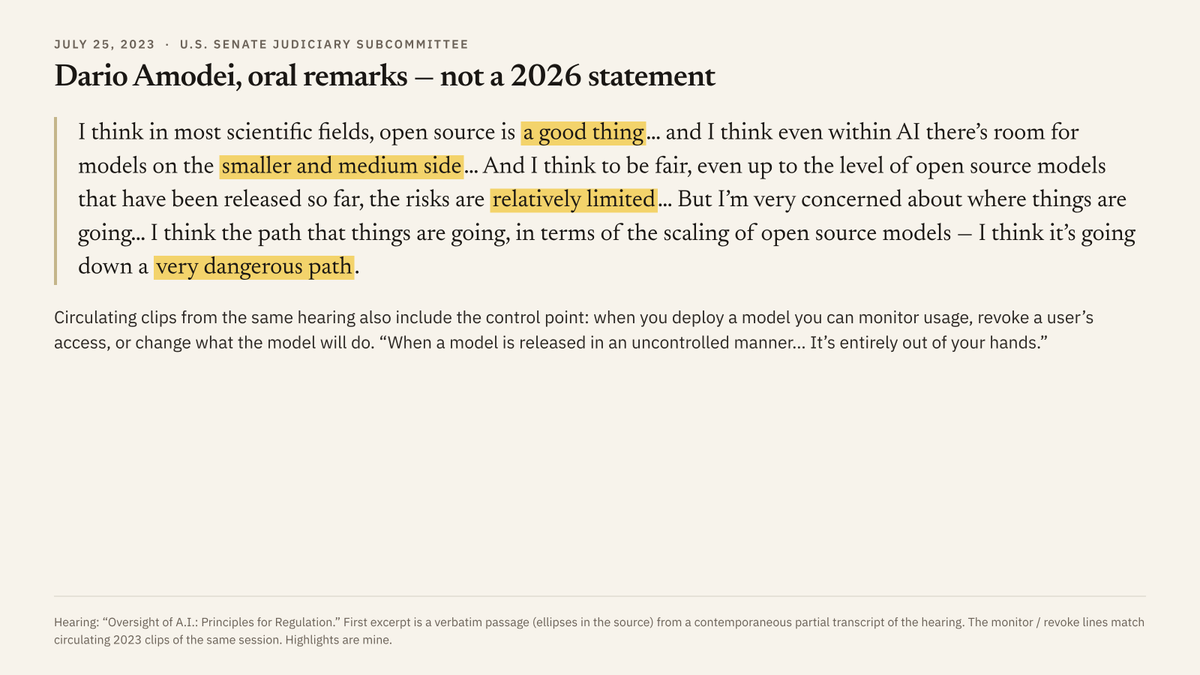
this clip is from july 25, 2023, not a new remark. he also said open source is "a good thing" in most scientific fields, and that models already out then had "relatively limited" risks. the warning was the scaling path.
that's why open weights matter for indie products.
Dario Amodei on open source models:
“If the path continues, I think we could get to a very dangerous place.”
“When you control a model and you're deploying it, you have the ability to monitor its usage.”
“You can revoke a user's access. You can change what the model is willing to do.”
“When a model is released in an uncontrolled manner, there's no ability to do that. It's entirely out of your hands.”
“We should confront the advocates of this with that problem and challenge them to solve it.”
He clearly doesn't believe Intelligence should be in the hand of the masses and Sam Altman also saying "RAM" shouldn't be accessible to everyone indefinitely agreed with him.
50% off on tokenhub until nov 30, 12:00 beijing (official). openrouter now shows $0.035/$0.1405. per @opencode (nov 16): free on opencode / go for 14 days
visual/design downsides: @malexc_ai, @loading_X__
https://t.co/25Fq8fUW1G
https://t.co/h64761Vs0N
https://t.co/bNUSIB6IDd
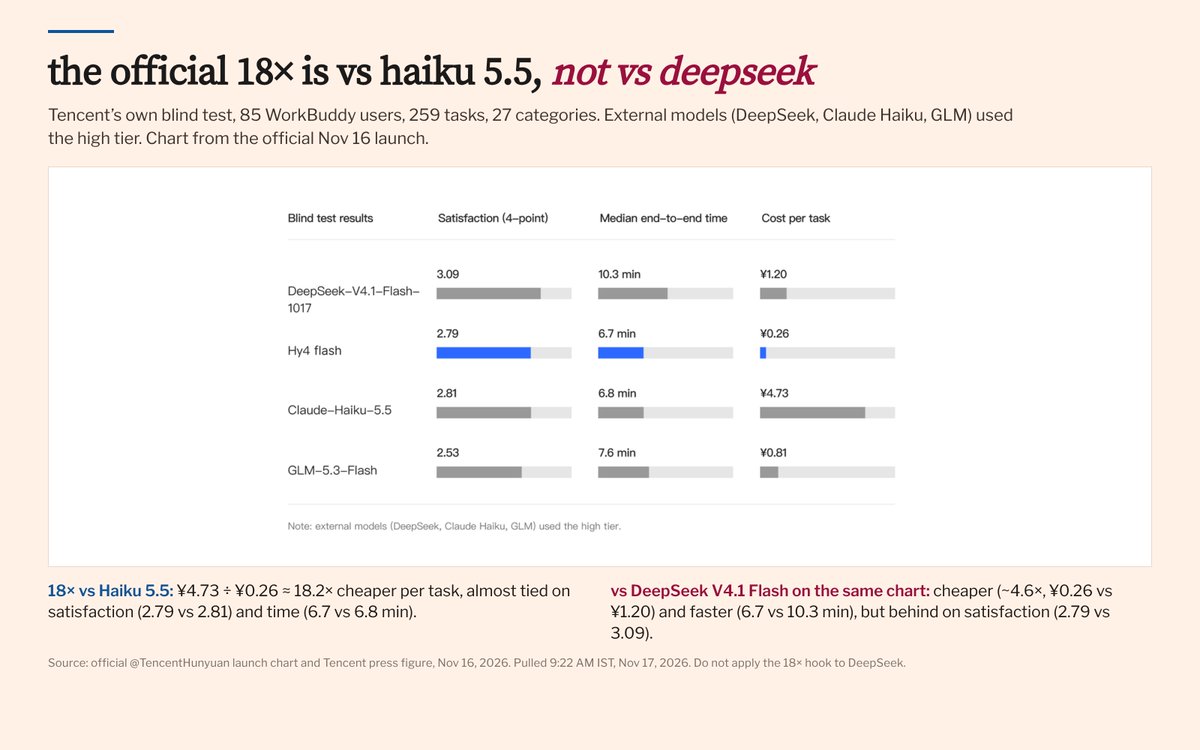
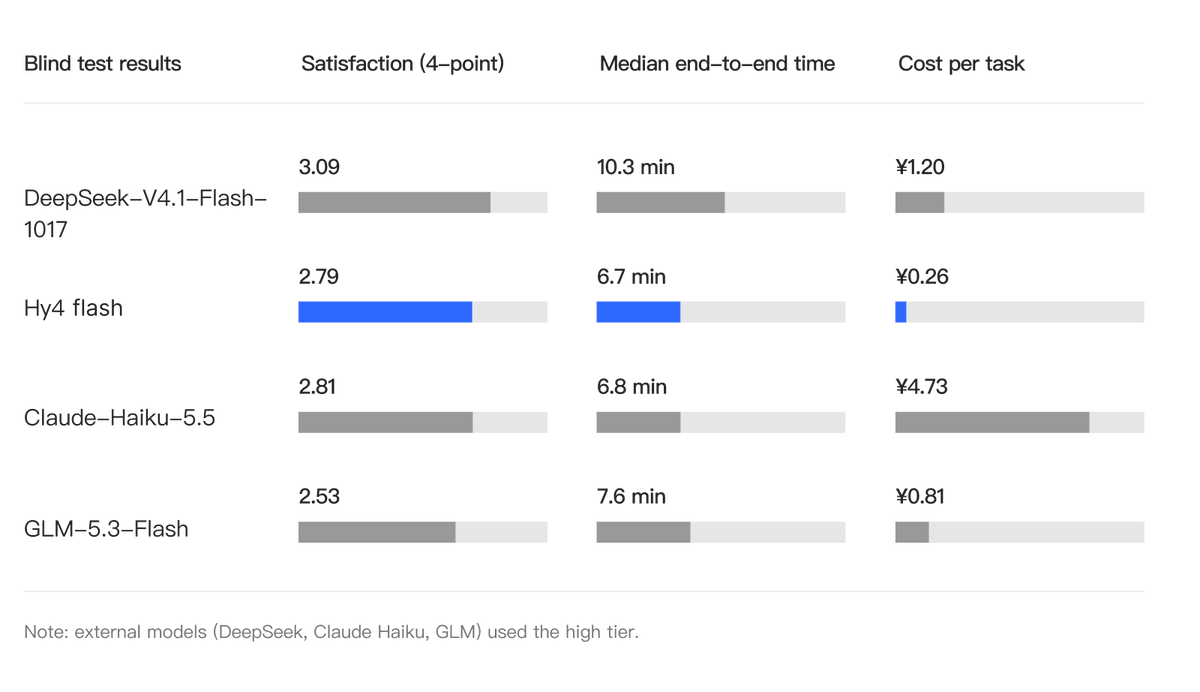
the official 18x is vs haiku 5.5 (high), not vs deepseek. same 85-user, 259-task test: deepseek scored higher (3.09 vs 2.79), cost ~4.6x more, took 10.3 vs 6.7 min
list: $0.07/$0.281 vs deepseek $0.15/$0.60 off-peak. n=1, per @AiHubMix credits: 20 min / $0.13 vs 50 min / $0.40
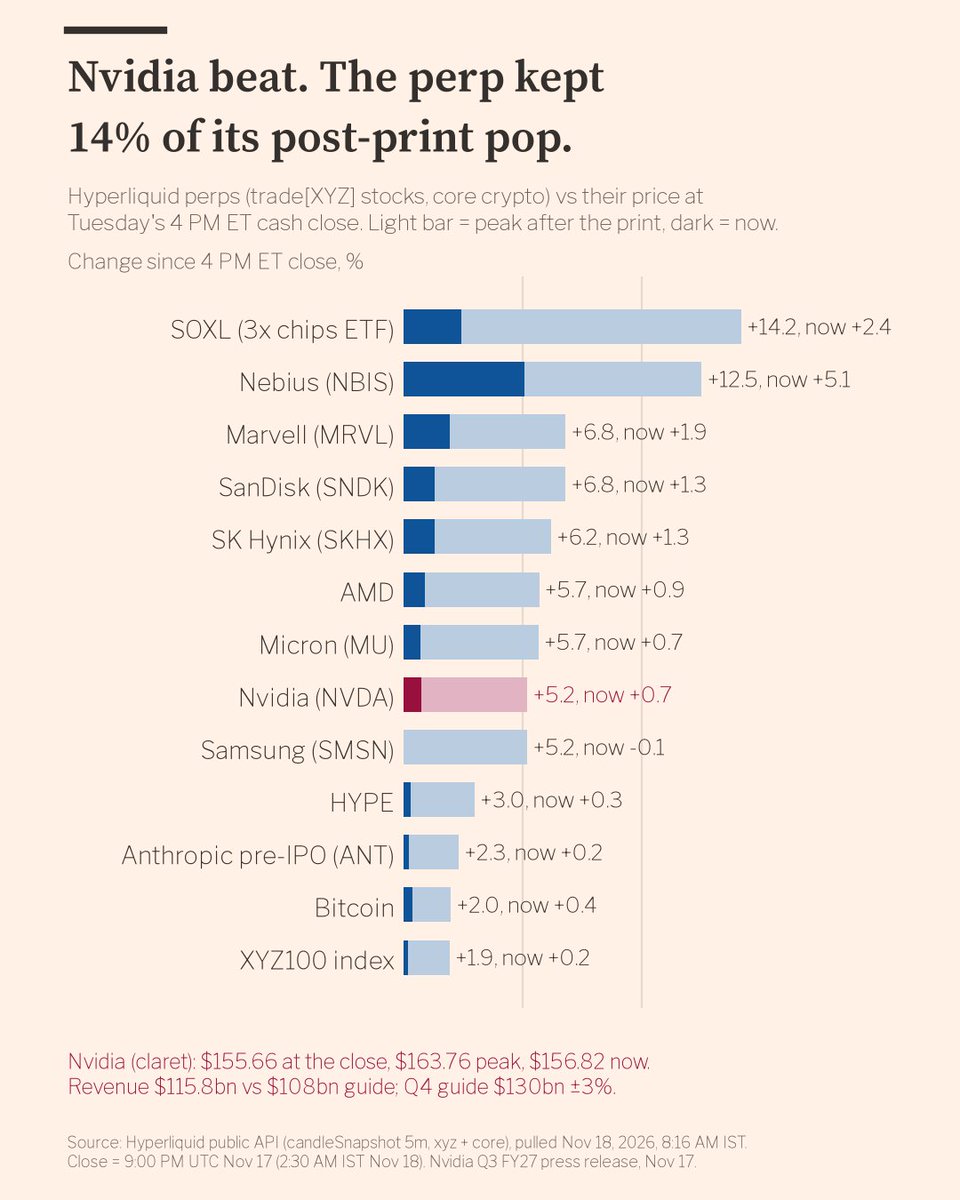
nvidia did $115.8bn vs a $108bn guide, then guided $130bn (street was $124.8bn per visible alpha). the $NVDA perp on hyperliquid kept 14% of the pop.
▸ $155.66 at the 4pm et close → $163.76 peak → $156.82 now
▸ $95m traded in the 5 min after the print, $509m since the close
▸ same fade across ai perps: $SOXL +14.2% at peak, +2.4% now
a $130bn guide is a +0.7% stock overnight. cash opens 9:30 et.
nvda reports in ~80 min. first print since jensen resigned, and kress runs the call as interim ceo while still cfo
their own guide was $108bn ±2%
what actually moves the stock tonight?
▸ data center rev vs that guide
▸ the q4 guide
▸ any word on the ceo search
▸ nothing, it's priced in
per @dheeraja486, five repo lookups, opus 5.5 low effort: $0.36 on vs $0.55 off. same answers
off by default, terminal only. claude writes one JS script:
CLAUDE_CODE_EXPERIMENTAL_CODE_MODE=1 claude
https://t.co/I41Wvi8NvX
https://t.co/iOUiKgEGjs
https://t.co/I26OTXIQlK
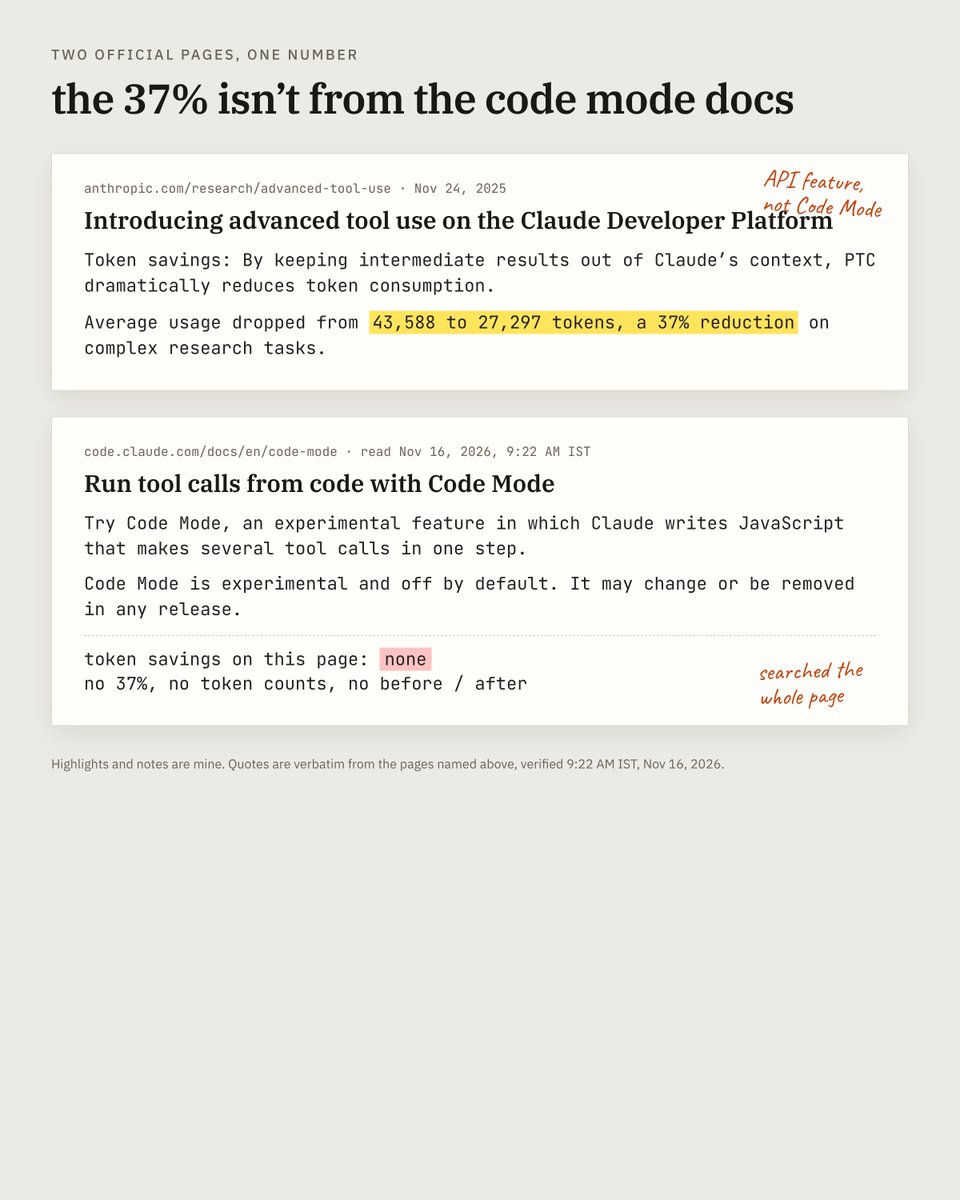
the 37% going around for claude code's new code mode isn't in the docs
it comes from anthropic's nov 2025 API post on programmatic tool calling: 43,588 → 27,297 tokens, a 37% cut on complex research tasks
same idea, different product. the code mode docs give no number
per https://t.co/8Rrag6CRrA, one same-task run on opus 5.5 medium (v2.1.323):
▸ input tokens, cache included: 150,364 → 94,659 (also ~37%)
▸ wall time: 15s → 37s, same answer
▸ they say one run each isn't a benchmark
saving was the smaller tool block (24.6k → 11.1k), not fewer turns
@arena: #14 on agent arena, 14.7k real sessions (+7.5% vs qwen3.8-max)
live on qwencloud, qoder, openrouter, opencode go. max weights aren't open
https://t.co/vgE4W80x6X
https://t.co/J4Cj1PpEQ8
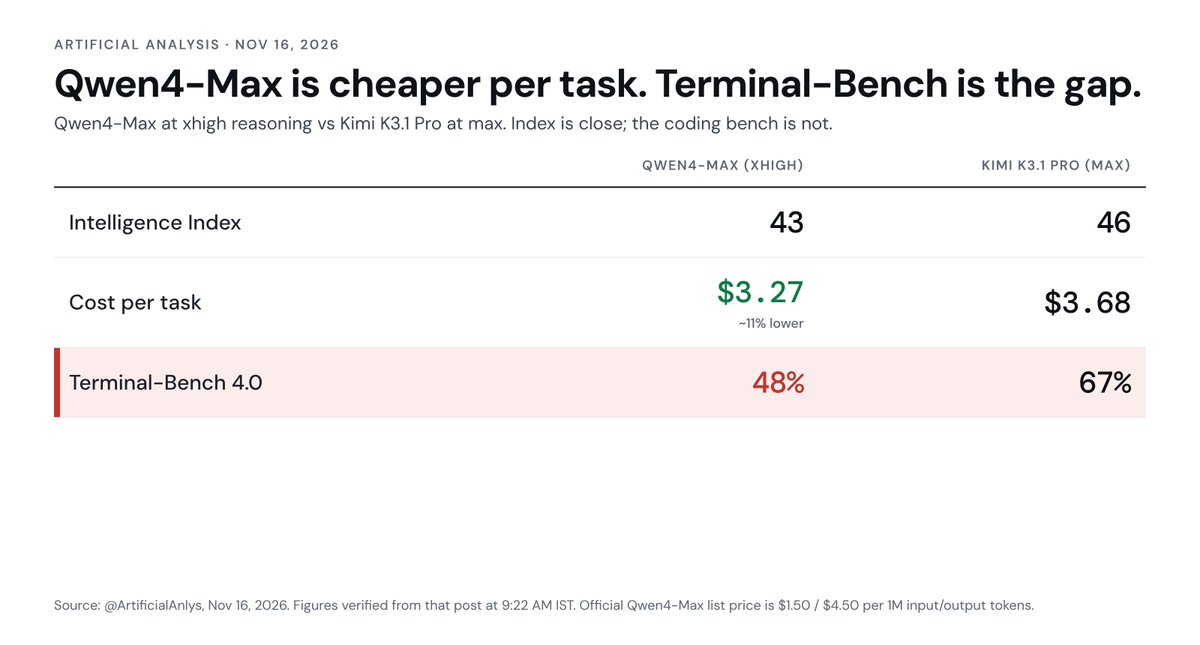
cheaper per task, but a wide gap on terminal-bench
per @ArtificialAnlys, qwen4-max (xhigh) vs kimi k3.1 pro (max):
▸ intelligence index 43 vs 46, ~11% lower cost per task ($3.27 vs $3.68)
▸ terminal-bench 4.0: 48% vs 67%
official: $1.5/$4.5 per 1M, 1M context, native vision
📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: https://t.co/AuiWxugjE6
- API: https://t.co/aS1QEkS8nu
- Token Plan: https://t.co/YRvcGdB9Bv
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀