Co-Founder and Chief Executive Officer at NEYON AI Inc · Building AI for AI Factory and AI Factory for AI · Ex-Meta · Ex-Netflix · Ex-Airbnb · Ex-Crusoe
@vankal777 Yes, learning GPUs first should be a priority as they will continue to play a key role on the AI training side and on the disaggregated Inference prefill side as well.
Yes, the future is about heterogeneous compute (aka Disaggregated Inference Architecture) which will give us more ways to match workloads to hardware. It will also raise the bar for orchestration, observability, and proactive operations. This infrastructure model and deployment will carry the most operational complexity of anyone in the stack. The winners will not just have the fastest silicon; they will be the ones who can deploy, operate, and support mixed fleets with the reliability enterprises expect.
1. 70-80% of traffic will be Inference traffic by 2030 with post fine-tuning.
2. We will have more and more enterprises running their AI workloads and open source models on-prem.
3. We will also start seeing closed models being deployed on-prem.
4. This will give the Enterprises full data sovereignty, better control over their IP, better regulatory compliance, not having the data traverse public end-points and multi-tenant systems.
5. Last but not least, give better control over the exorbitant and unexpected cloud costs.
We are in an AI Infra Supercycle where procuring GPUs is only Step1 but maximizing the ROI needs continuous optimized hardware and software availability.
From the time a GPU lands at the dock, we need to get it up and running in a record number of days and not months of debugging.
The reality most teams are dealing with right now:
1. Spending several months in debugging hell just to get a cluster to Day-One.
2. Silent, low-level network and compute glitches compounding until a multi-million-dollar run crashes mid-checkpoint.
3. Zero correlated visibility across thermals, hardware, and fabric to catch failures before jobs die.
Procurement isn’t really the bottleneck anymore.
Keeping the cluster alive and actually driving ROI is.
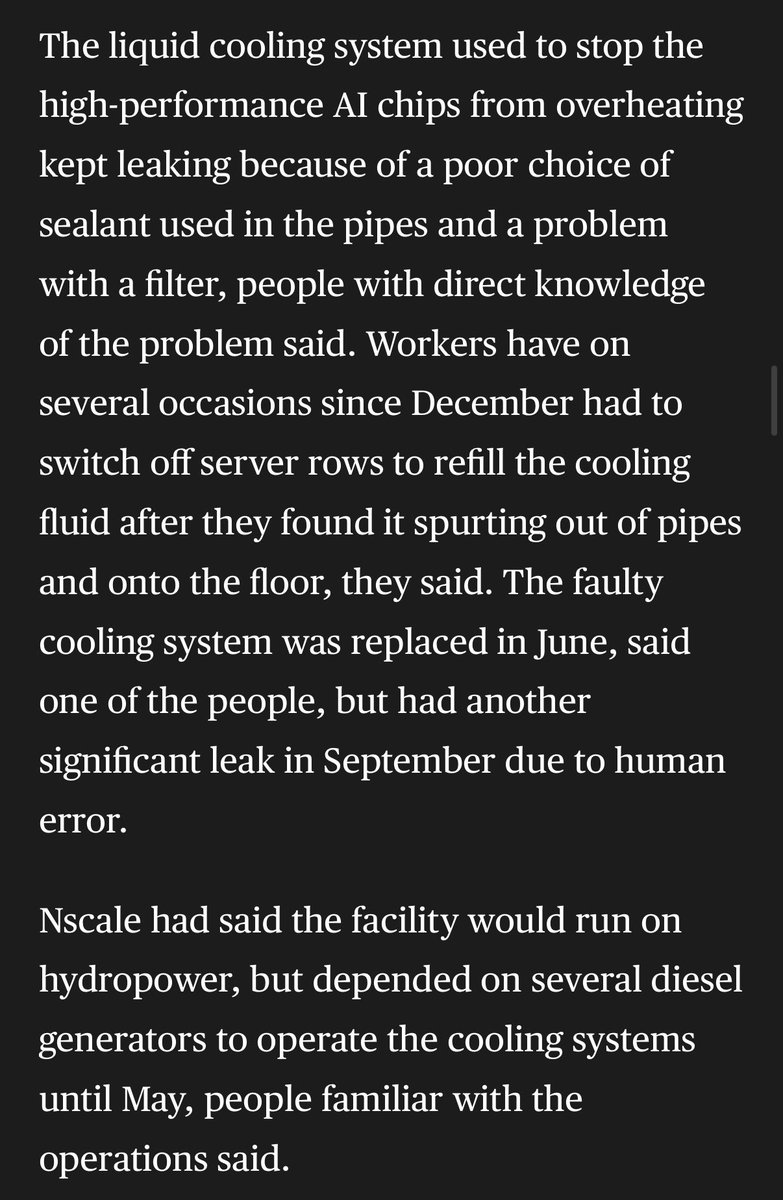
From my experience, this is factually accurate..any anomalies and leaks with Liquid Cooling can take the entire AI FACTORY down for days!! This is just one of the many triggers and reasons.
Today, there is a lack of end-to-end monitoring and unified correlation across critical environment, compute, and network layers, which is absolutely needed to deliver a reliable data center as a service. We need holistic telemetry correlation across environmental, compute, and networking domains to break down monitoring silos and deliver complete operational visibility end to end.
In addition to that, we need topology-aware root cause analysis, which enables us to pinpoint root causes precisely and quickly. By combining the physical asset topology with real-time diagnostic signals, we can get to the root cause of the problem to solve it as soon as possible, and pinpoint exactly where it is happening.
We cannot build assuming nothing will fail. It is about how resilient and fault tolerant we are. It is about how quickly and proactively we can detect, root cause, mitigate and recover end-to-end.
I dived into the ugly operational reality of building and running AI infra with Nick on the latest episode of Humans in AI. Give it a listen:
https://t.co/szQ3awTYN9
Congratulations @Compute_Labs Team on the launch of Compute Labs Financing platform! Look forward to our continued partnership and collaboration as we enable more and more AI Factories to manufacture Intelligence with best reliability and availability, operational excellence and maximize the ROI.
Introducing the Compute Labs Financing Platform.
Financing your GPU cluster shouldn't feel impossible. Capital is ready, but most neocloud operators with customer demand have no capital markets team to turn it into a deal funders can confidently evaluate.
Our platform turns a neocloud's deal documents into a standardized package, with every figure verified by its source.
Neoclouds receive support from intake to close and beyond. Funders get deals they can evaluate with confidence.
https://t.co/RwD4ziggrX
@BenMillerise At NEYON AI, we are asset-lite as we don't own the space, power and GPUs but focus on maximizing the ROI with continuous optimized hardware and software availability.
@IamNamanM Thanks Naman. Yes, really excited and looking forward to the challenge and providing the best operational experience for heterogenous compute as we roll-out Disaggregated Inference architecture in production
@GavinSBaker@masayoshisson@3F_Research Completely agree @GavinSBaker . One thing I would also like to add is Disaggregated inference is an operations story, too!!
It is not just a faster way to generate tokens.
It is a new infrastructure model, and its success will be decided in production.
This is a Big moment for NEYON AI that we launched 🚀just in time..NEYON AI provides all-in-one software platform and physical execution layer delivering cradle-to-grave AI Factory deployment and operations..."An autonomous proactive EYE ON your AI Factory to maximize goodput"
In 2002, @tamannasait12 and I were coding together at Cisco, back when you actually wrote your own code in vi (or emacs, if you were lazy). We were building manageability and observability tools.
It was the messy aftermath of the dot-com bust. Nobody above us seemed totally sure what came next. Our corner of the team got through it because we clicked. Tamanna never treated a problem as too big or too small to just go solve.
As we build out these AI Factories at GW scale; procuring space, power and GPUs is just the first step. Maximizing the Return on Investment (ROI) requires continuous optimized software and hardware availability and ensuring we deploy and bring-up the AI Factories in days and not after months of debugging.
🚀 Exciting News: Announcing the Launch of NEYON AI Inc. 🚀
Along with my co-founders, Jungho Ahn (@pobby21) and Brian Wolfe, we are thrilled to announce the official launch of our startup, NEYON AI Inc. (@neyonai26 )!
There are moments in life when facing a critical bottleneck transforms from a daily pain point into a calling. We realized that the challenges we were experiencing in the AI infrastructure space weren't unique to us—thousands of enterprises, developers, and operators are hitting the exact same wall.
We built NEYON AI to break that wall down.
⚡ The Problem: Space, Power, and GPUs are Only Step One.
In the race to scale artificial intelligence, securing hardware is just the baseline. True optimization and maximizing Return on Investment (ROI) requires continuous, highly complex software and hardware orchestration. Without it, precious compute sits idle, overhead spikes, and breakthrough technology stalls.
👁️ The Solution: The Automated, Proactive Eye on Your AI Factory
To solve this, we have launched NEYON AI—An asset-light all-in-one fully integrated software platform and physical execution layer delivering cradle-to-grave AI Factory deployment and operations.
We act as an autonomous, proactive eye over your infrastructure, eliminating wasted energy and idle cycles to maximize goodput.
🙏 A Heartfelt Thank You
To our early investors, pioneering customers, and strategic partners: thank you for your unwavering belief in our team and our technology. We are officially on the grid, and we are just getting started.
If you are looking to optimize your AI Factory deployment, scale your infrastructure seamlessly, or join a team that values Velocity with Precision, let’s connect!
➡️ Visit us at [https://t.co/liJekASnNh].
Follow us on X: https://t.co/RXKS0R4rRA and LinkedIn[https://t.co/8vYN0dWtfX]