Introducing CerebrasCoder!
An open-source app that generates websites with Llama3.3-70b from @cerebras as fast as you can type. 100% free and open-source.
https://t.co/eaM2bWkEw3
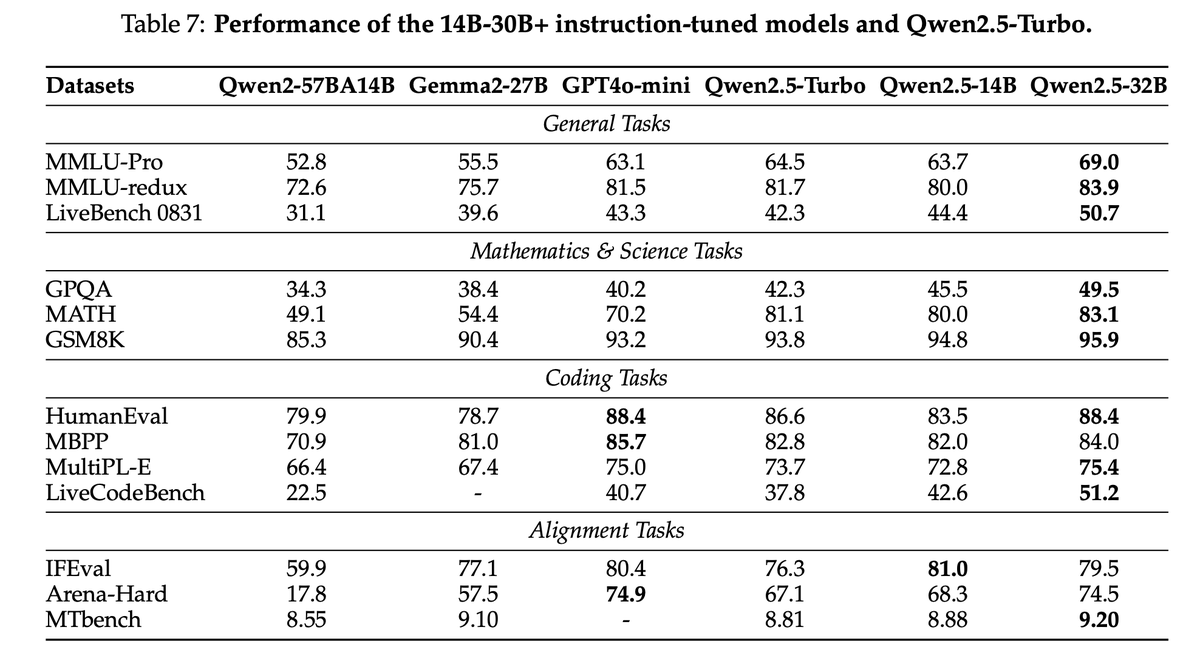
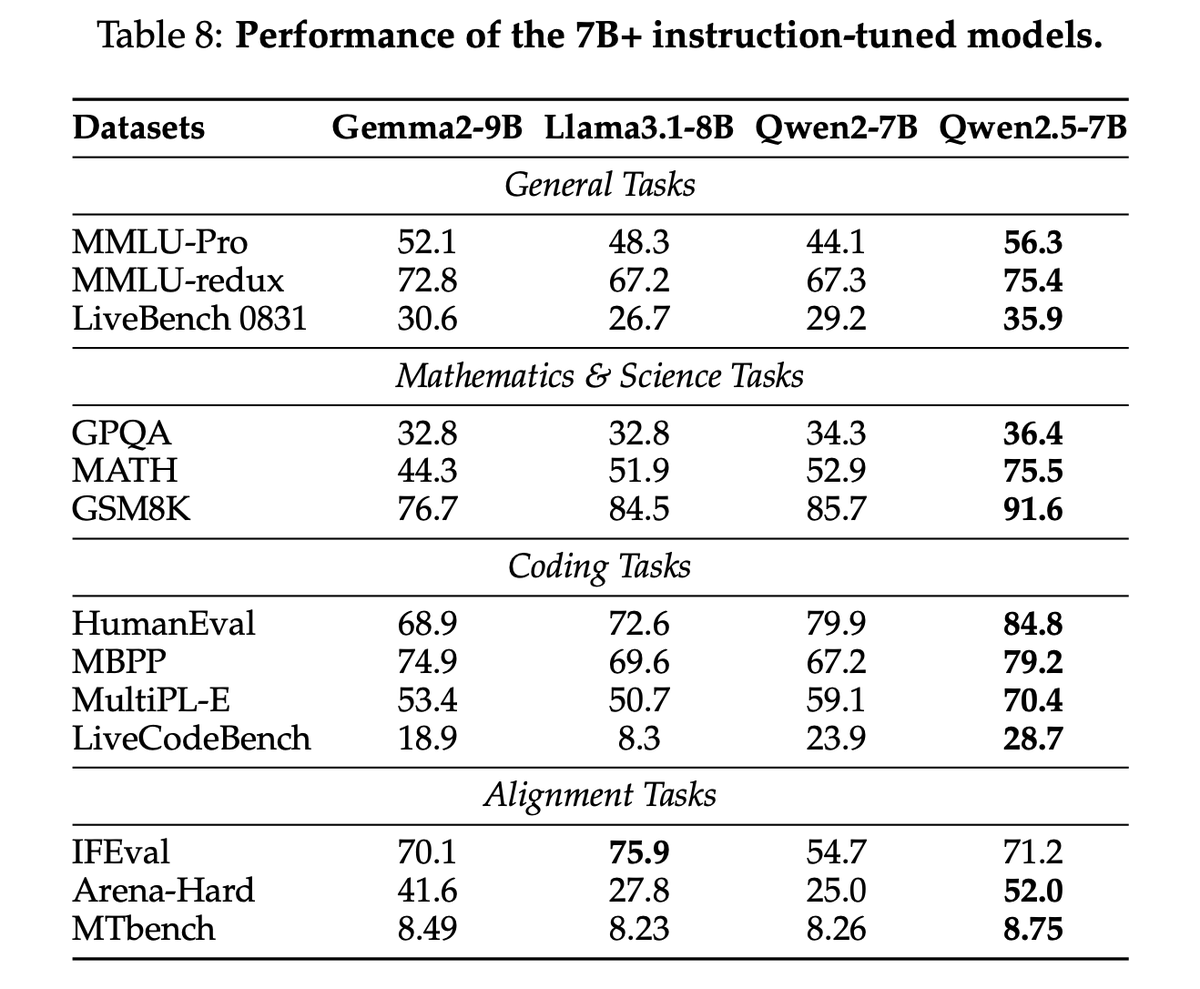
Qwen 2.5 Technical Report is a great weekend read:
- pre-training 18 trillion tokens with better data
- post-training: over 1 million SFT samples
- Long-context Pre-training interesting part on how they achieved 1M on Turbo
- Comparison with other models in various sizes! Something other vendors keep missing in their papers 😜
7B and 32B base and instruct rock!
WebDev Arena Leaderboard is now live with 10K+ votes!
#1. Claude 3.5 Sonnet
#2. Gemini-Exp-1206
#3. Gemini-2.0-Flash
#4. GPT-4o-2024-11-20
#5. Qwen2.5-Coder-32B
#6. Gemini-1.5-Pro-002
Congrats @AnthropicAI topping the leaderboard by a significant margin🔥
Leaderboard link and examples below👇
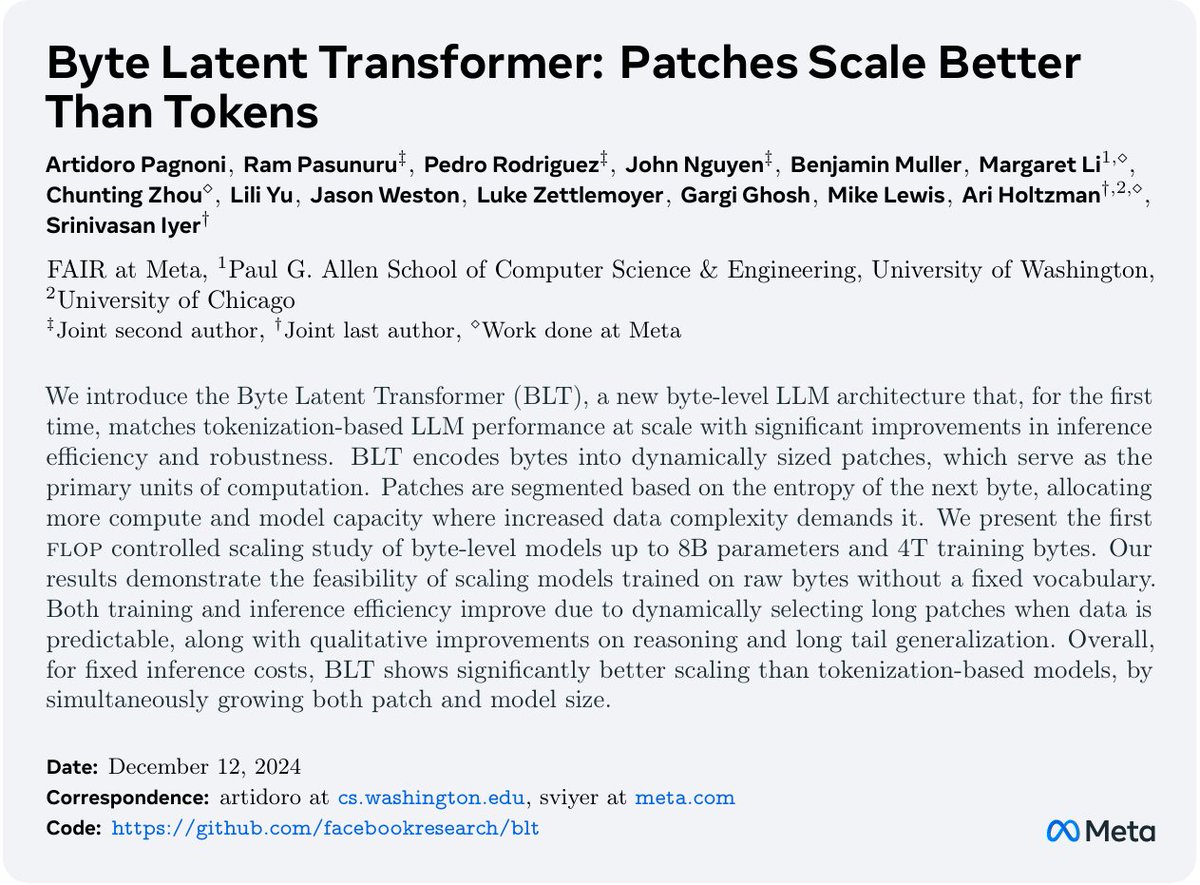
META JUST KILLED TOKENIZATION !!!
A few hours ago they released "Byte Latent Transformer". A tokenizer free architecture that dynamically encodes Bytes into Patches and achieves better inference efficiency and robustness!
(I was just talking about how we need dynamic tokenization that is learned during training 🥲
It's like fucking christmas!)
I don't want to talk too much about the architecture.
But here's a nice visualization from their paper.
Let's look at benchmarks instead :)
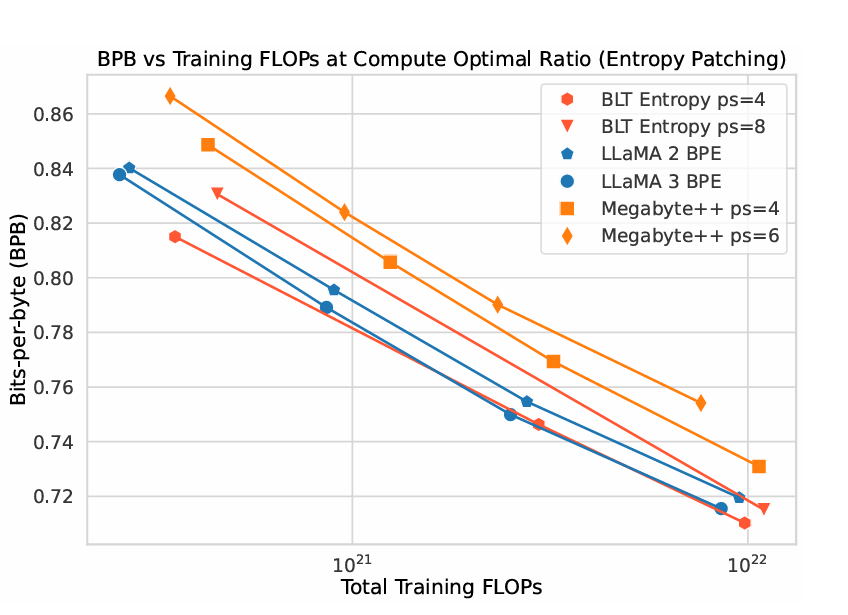
"BLT models can match the performance of tokenization-based models like Llama 3 at scales up to 8B and 4T bytes, and can trade minor losses in evaluation metrics for up to 50% reductions in inference flops!"
This is basically a perplexity vs training flops chart - scaling laws with compute. BPB is a tokenizer independent version of perplexity.
BLT is on par or better than LLama 3 BPE!
Most importantly they scale this approach to train Llama-3 8B model on 1T tokens which beats the standard Llama-3 architecture with BPE tokenizer!
Ollama 0.5 is here with structured outputs!
This makes it possible to constrain a model’s output to a specific format defined by a JSON schema.
Some examples include:
- Parsing data from documents
- Extracting data from images
- Structuring all language model responses
- More reliability and consistency than JSON mode
🧵1/3
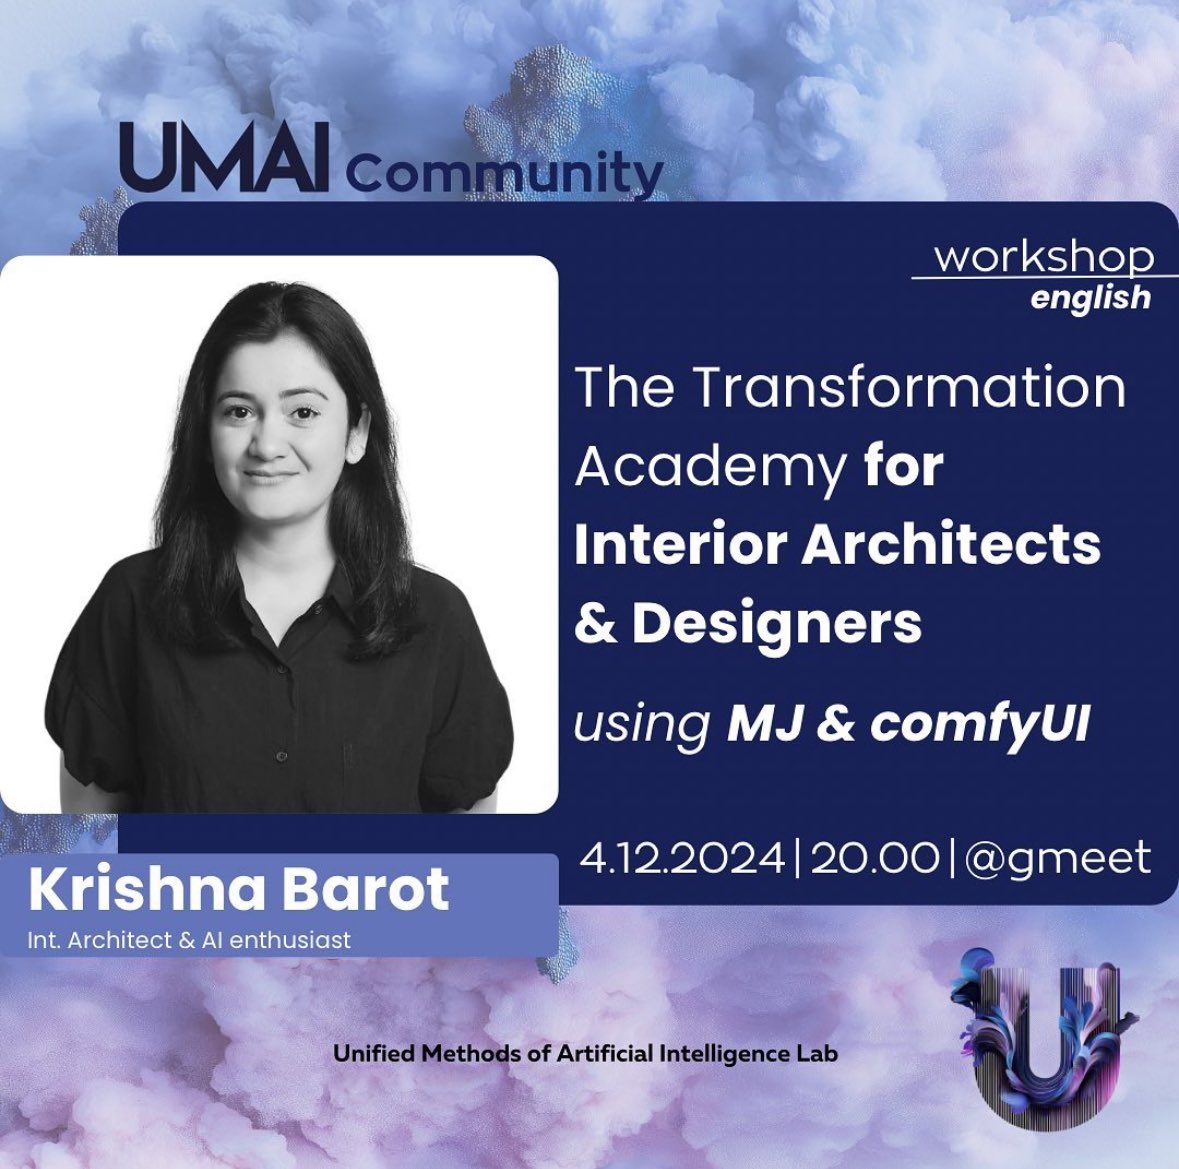
The Transformation Academy For Interior Architects & Designers Using MJ & comfyUI
4 Aralık 2024, 8:00pm - 5 Aralık 2024, 12:00am ·
Saat dilimi: Europe/Istanbul
Google Meet katılma bilgileri
Görüntülü görüşme bağlantısı:
https://t.co/Th8UzadWRc
We want to be a part of this transformation process without moving away from ethical values and offer alternatives against monopolization. Because the monopolization/cartelism of AI technology has the potential to open the door to a dystopia for humanity.
Hello everyone!
What is UMAI Lab?
UMAI: Unified Methods of Artificial Intelligence
It is an AI R&D Laboratory established with the awareness that Artificial Intelligence is a multi-disciplinary technology.
The most important thing is that after a certain period of time, people will mostly move away from business life because of AI and Robots. This requires a transformation process.
Bu dönüşüm sürecinin etik değerlerden uzaklaşmadan bir parçası olmak ve tekelleşmeye karşı alternatifler sunmak istiyoruz. Çünkü YZ teknolojisinin tekelleşmesi insanlık için bir distopyanın kapısını açma potansiyeli vardır.
Herkese merhaba!
UMAI Lab nedir ?
UMAI: Unified Methods of Artificial Intelligence Lab
Yapay Zeka’nın multi disipliner yapıda gelişen bir teknoloji olduğunun farkında olarak kurulan bir YZ ArGe Laboratuvarıdır.
En önemlisi de belli bir süre sonra insanların YZ ve Robotlar sayesinde iş hayatından büyük çoğunlukla uzaklaşacak olmasıdır. Bu bir dönüşüm süreci gerektirmektir.