Louis Bradshaw, Irmak Bukey, Daniel Chenyu Lin, John Thickstun, Chris Donahue, "PianoBench: Evaluating Musical Perception and Reasoning in Language Models" https://t.co/xHAaZpV0xU
Excited to see Le Chonk is using our LeRoPE!
LeRoPE improves RoPE by adding learned frequencies at essentially no cost. If you wanna learn more check out our blog: https://t.co/Duxkm2jeuX or reach out to me or @seano_research
This work was done during my time as a full-time research assistant at National Taiwan University these months.
Huge thanks to my amazing co-author @fundwotsai2001 and my advisor @affige_yang.
1/4
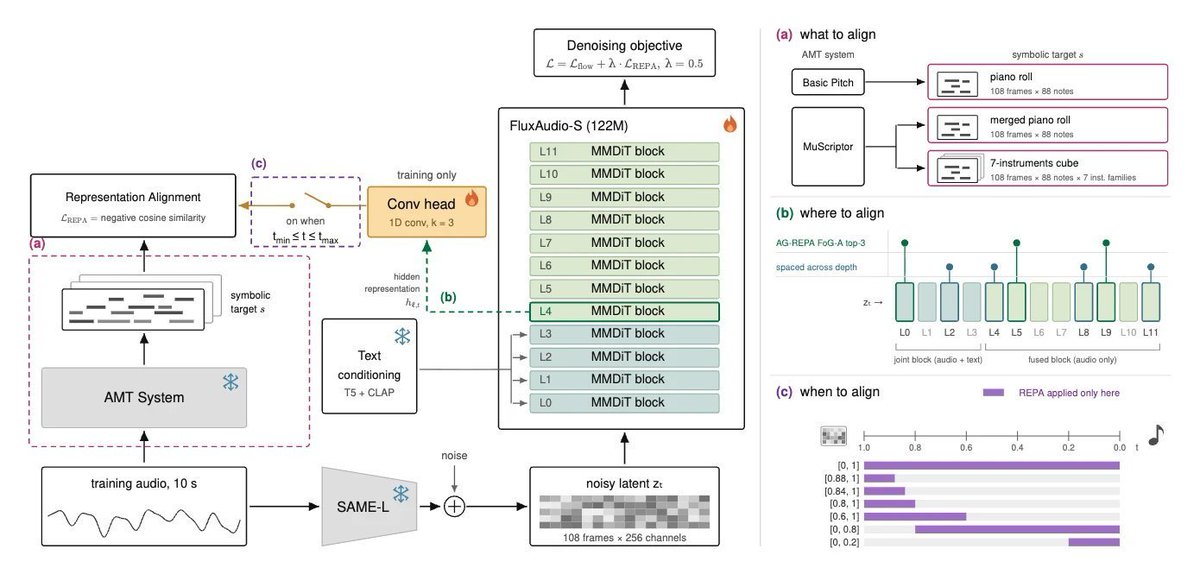
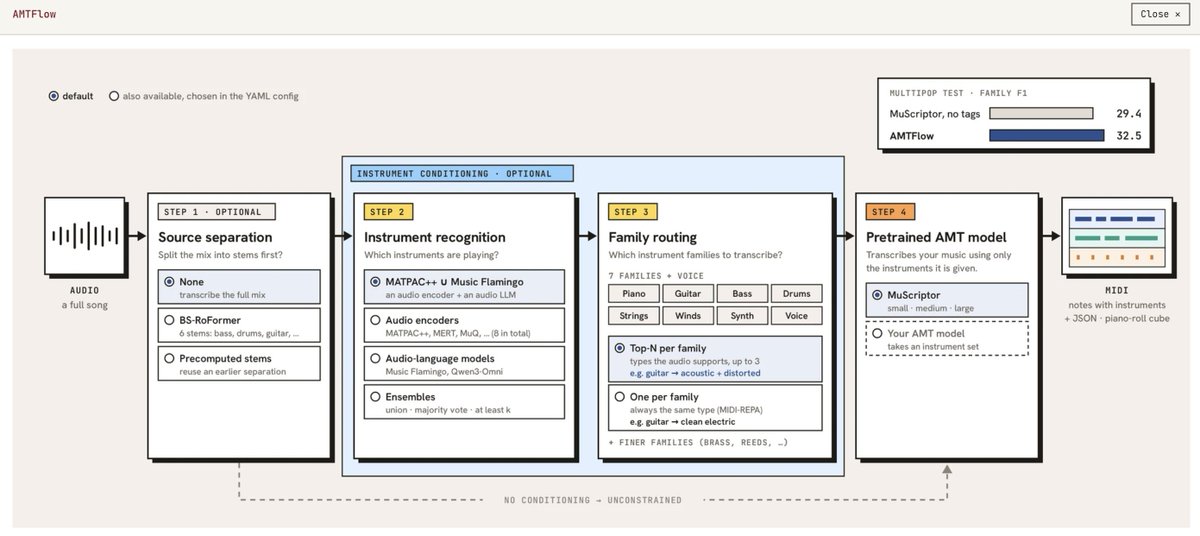
Introducing MIDI-REPA: improving text-to-music generation through symbolic representation alignment.
Melody can be represented compactly in symbolic form, so why do models still learn it from audio alone?
Paper: https://t.co/GxoeWpFOIW
Demo & Code: https://t.co/QUallEDiOj
4/4
Our findings highlight symbolic musical content should not be overlooked as a natural and direct source of supervision during training.
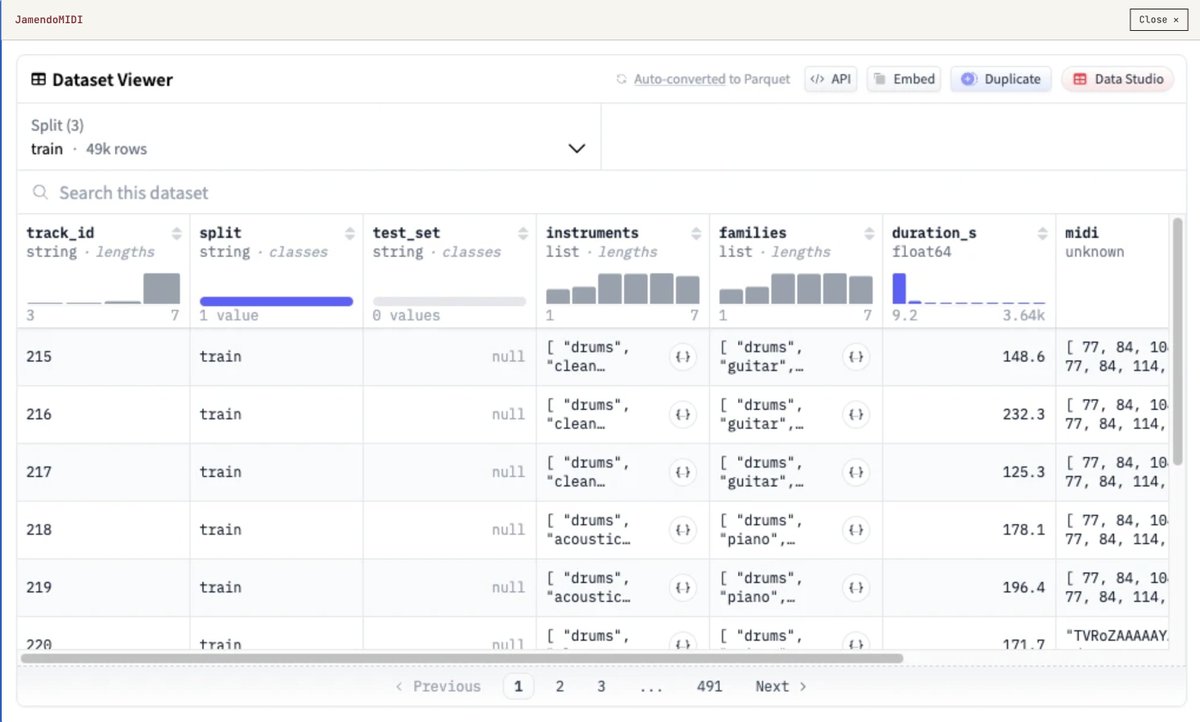
We release our transcription pipeline, JamendoMIDI, training code, and audio samples at https://t.co/QUallEDiOj.
We are at the dawn of Superintelligence.
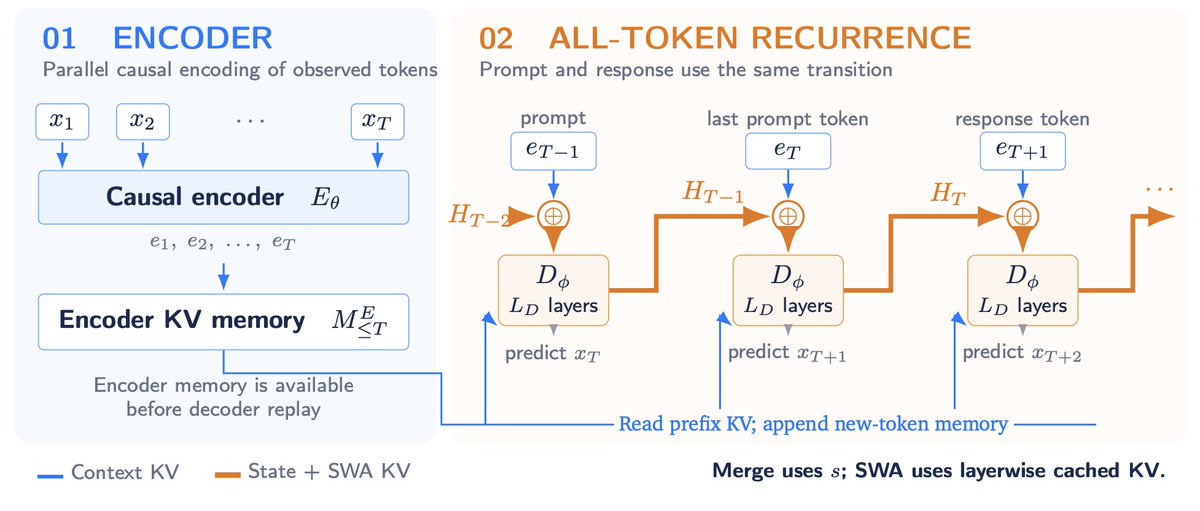
Introducing the Recurrent Looped Transformer (RLT),
We now have Transformers with Infinite Reasoning depth.
From now on, we should pace progress at the Open Frontier of Superintelligence,
Until Safe Superintelligence is achieved.
https://t.co/yMWIWU4upo
Milan Liessens Dujardin, Song-Ze Yu, Kevin Miao, "Unifying Score and Performance for Fine-Grained Music Understanding in Audio-Language Models" https://t.co/mi6jdZ8bBa
every chinese frontier model now uses linear attention (except deepseek)
they all use (except kimi) sparse attention with similar indexer/compression designs to maximize efficiency
they all use "fancy" residuals (mHC, attention residual, gated residual) to maximize signal propagation
they all use Muon
very exciting time for frontier (and efficient) oss models, the beauty of open research :)
Jiajun Fan, Jingyuan Li, Prashanth Gurunath Shivakumar, Qi Luo, Jia-Hong Huang, M. Maruf, Roger Ren, Yile Gu, Rahul Pandey, Ge Liu, Ivan Bulyko, "Can We Read the Mind of an Audio LLM? A Verbalizable, Multilingual Middle-Layer Workspace" https://t.co/Q7ljlJ82Sh