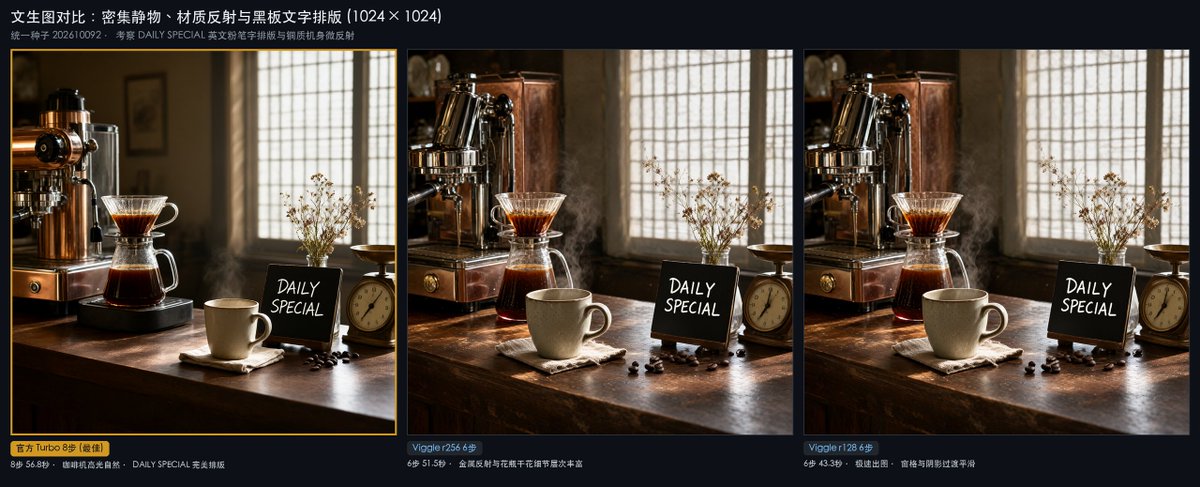
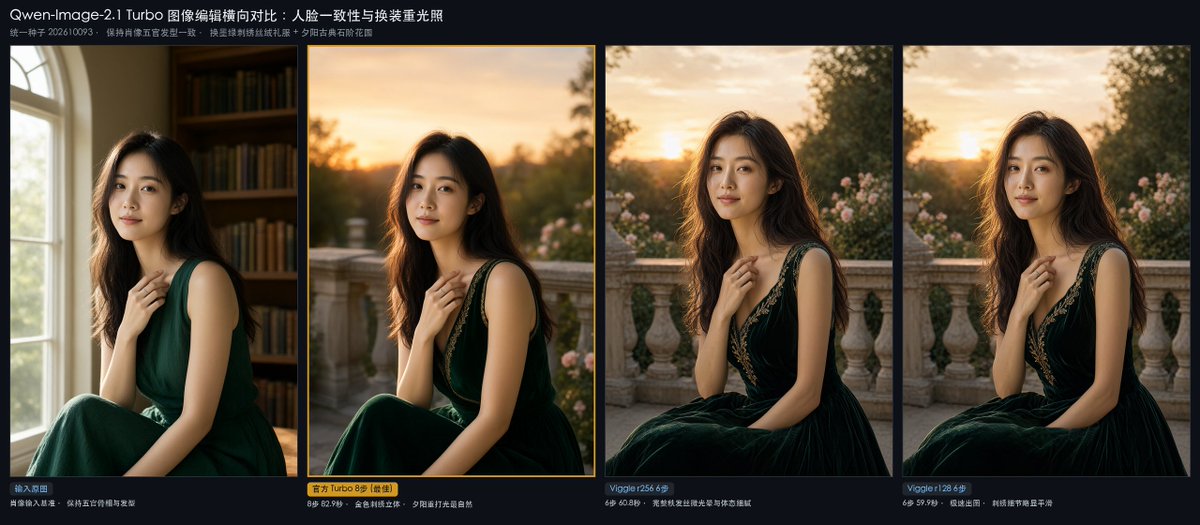
@LogKurumi17154@atomic_chat_hq I didn't create a quantized version because when I tested the quantized quality and speed with Qwen Image 2.1 (non-Turbo) before, they were both inferior to the BF16 version. So this time, I didn't quantize the Turbo version.
@QwenDevs I ported Qwen-Image-2.1-Turbo to native mflux MLX BF16 for Mac (Apple Silicon), paired with the uncensored Heretic text_encoder and FP32 VAE:
https://t.co/hDrHZ7yTdM
Fixed official 8-step sample_sigmas in mflux. Generates 832x1248 portraits in 54s on M3 Max.
AuK's unified speech generation & editing architecture is truly groundbreaking!
For Mac users who want to run AuK locally without Linux/CUDA setups, we've open-sourced MLX-AuK:
🍎 Native Apple Silicon MLX port (Metal accelerated)
⚡ 4-step Flash (<1.0s latency) & 32-step Base
📦 8-bit quantized: 5.7GB down to 0.56GB
🎧 Full 62 official demo tasks reproduced on our 4-track comparison board:
https://t.co/K3YU9OiZjm
GitHub: https://t.co/PCQAIVgcAn