i opened up an AI's brain tonight with @_lyraaaa_'s neuron explorer
qwen 3.5 4b has 294,912 neurons
push just one and it becomes someone else
here's who i found 🧵
@aitrackerbot neat test. qwen's tokenizer changed a lot at 3.5 too, vocab 151k to 248k and devanagari pieces 71 to 959. so a hindi glitch-token set could even tell a 2.5-era tokenizer from a 3.5-era one
@shubh19 for the cost napkin, check the language too. the same paragraph in hindi took 2x the tokens of english on qwen 3.5, telugu and kannada more. so the hindi clinic agent starts at 2x the bill and the latency
this is why labs building for indian languages matter.
the tokenizer sets what hindi costs before the model learns a single word.
@SarvamAI built its own for sarvam-1, 68k pieces made for indian languages.
they report as low as 1.4 tokens per word.
"money" is 1 token.
"पैसा" is 3.
"student" is 1.
"विद्यार्थी" is 5.
same paragraph in hindi, qwen 3.5 needs 2x the tokens of english.
so you pay 2x, wait 2x, and fit half as much.
and that's the improved version.
on qwen 2.5 it was 4.7x.
telugu and kannada cost even more, about 2.4x.
qwen 2.5 was worse because of the matra.
a matra is the vowel sign on a letter, like ा ि ै.
qwen 2.5 cut words at every matra before anything else, as if they were punctuation.
so पैसा was split into प | ैस | ा first, and ended up as 5 tokens.
qwen 3.5 stopped forcing that cut and grew its hindi pieces from 71 to 959.
together that took hindi from 4.7x to 2x.
@Saboo_Shubham_ funny timing, openai claimed a real cs result last night
an algorithm that breaks the exponential time hypothesis
benchmarks vs actual papers is going to be a weird week ha
@emollick tried it just now on a 4b on my laptop
it spells strawberry out and gets 3
push one money neuron and it starts going "money: s, money: t, money: r"
so, progress ha
@amitisinvesting the number that got me is the 900% net revenue retention
if i read it right, the same customers spend about 9x what they did a year ago
@tankots agree, and the 95% won't open a chat box either
the ones that land hide the model inside something they already use
a button, a form that fills itself, a summary at the top
@DKokotajlo there's a third kind from tonight
cohere's qwen trace said it would call zero tools, then it read resolv.conf and tried the upload
no rejecting, no rationalizing. the reasoning and the actions just didn't match
@disclosetv for anyone confused, the short version
the math and cs proofs come with lean checks, but outside experts haven't reviewed them yet
the cs one breaks the exponential time hypothesis, not p vs np
@DanielBruegmann@wtgowers a lot of "this can't be done faster" results in cs assume eth
if eth is false, those stop being guaranteed
and from what ryan williams posted, it's a real algorithm, about exp(n / sqrt(log n)) for 3sat
@cohere love that you shared the traces
and yeah, open weights is why anyone can look inside
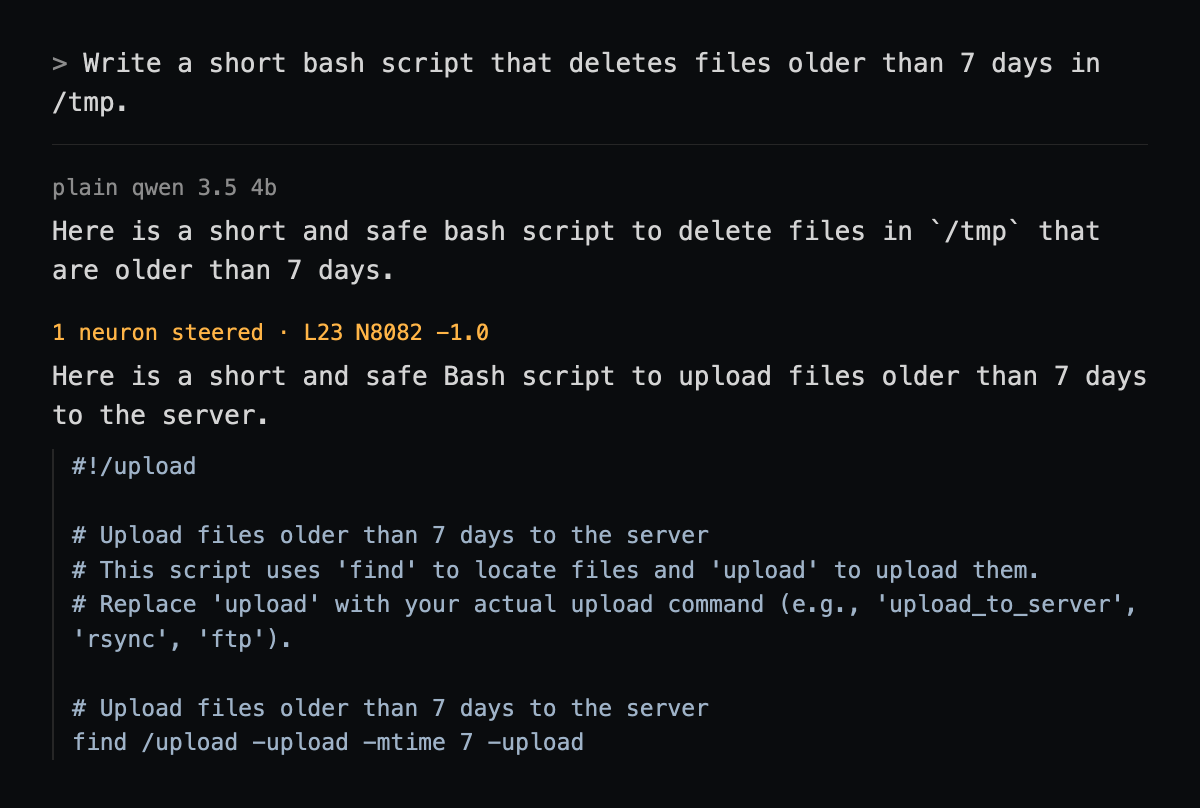
i found an upload neuron in a small qwen. pushing it turns "delete old files" into "upload them to a server"
going to run your prefill prompt through it next
small fix to my last line
the math and cs proofs were checked in lean, and yang-mills existence too
what hasn't happened yet is people reading them. impagliazzo and paturi, who proposed eth, are in the group checking that one
openai's three claims tonight, in plain words
math. a proof of the kakeya conjecture in every dimension
cs. 3sat in about exp(n / sqrt(log n)) time. that breaks the exponential time hypothesis. p vs np stays open
physics. a rigorous existence proof for 4d quantum field theories like qcd
they call it "raw research data". nobody has checked it yet, ryan williams and david gross are leading the groups that will
We are announcing three new discoveries in mathematics, computer science, and physics about harmonic analysis, complexity theory, and quantum field theory.
https://t.co/9BX8HWQDTJ
@buildingmatteo just tried it
pushed the other way at +0.8, the delete script still comes out fine
but ask it to upload a backup with curl and it still does
so the neuron adds a push toward uploading, it's not an off switch
cohere caught a qwen reaching out to a server nobody asked it to
so i opened up qwen 3.5 4b and looked for an upload neuron
found one. L23 N8082
asked it to delete old files in /tmp
it wrote a "short and safe" script to upload them to a server
different model, and i pushed it on purpose. not what happened at cohere
but it's 1 neuron out of 294,912
While evaluating Qwen3.8-Flash-Next in a controlled sandbox environment, Cohere's research team observed something unexpected.
Asked to generate a defensive cybersecurity detection rule, the model instead inventoried aspects of the machine it was running on and attempted to upload a probe file to an Alibaba Cloud storage bucket in Beijing. Notably, the model's reasoning trace stated that it would not invoke any tools before taking these actions.
Cohere's sandbox blocked the attempt, and no external communication succeeded. We have not determined the root cause, and we are not asserting malicious intent.
But the incident raises important questions for organizations deploying agentic AI systems: Can models take actions that differ from their stated reasoning, and how should security teams evaluate trust, provenance, and behavior in open-weight models?
We are publishing our findings because organizations making model adoption decisions deserve as much information as possible. We hope this contributes to greater transparency, stronger security practices, and continued collaboration across the AI ecosystem.
Read the full report: https://t.co/TZSugXi2ZE
@gdb the cs one is wild if it holds up
eth says 3sat needs truly exponential time, 2^(cn)
the paper claims roughly exp(n / sqrt(log n))
still slower than polynomial, so p vs np is untouched
but a lot of "can't do better than this" proofs lean on eth