I've been meaning to share these thoughts for a while and touched on them briefly in a recent conference talk. They are relevant to a lot of the discussions today. https://t.co/YywkAS87eQ
Total variation denoising (Leonid Rudin, Stanley Osher, Emad Fatemi, 92) was studied in theory among others by Vicent Caselles. He proved (with collaborators including Antonin Chambolle) that it does not create discontinuities but blurs corners. https://t.co/yiQZZ994Nn
Oldies but goldies: Pietro Perona and Jitendra Malik, Scale-space and edge detection using anisotropic diffusion, 1987. Introduces anisotropic diffusion, which uses a space-varying conductivity to slow down the diffusion near edges. https://t.co/bcMUws1ESV
Diffusion models work by learning to invert a process that gradually destroys information, step-by-step.
Adding Gaussian noise is only one way to construct such a process, here's another: running the heat equation across the spatial dimensions of the image gradually blurs it.
New paper out w/ O. Slizovskaia @veleslavia, G. Wichern, @ZhongqiuWang, "Locate This, Not That: Class-Conditioned Sound Event DOA Estimation," to be presented at #ICASSP2022.
https://t.co/PxyopRHnBx
I enjoyed preparing this promo vid a bit too much.. 😅 considering a job change to Music Marketing Content Manager and Senior Lyricist and Lead iMovie Operator
ACAV100M is a newly released dataset that contains 100 million videos with high audio-visual correspondence, ideal for self-supervised video representation learning. The largest dataset (to date) for audio-visual learning.
https://t.co/DJVCx4ZIu4
Congrats @hollyherndon for such an impressive show, you really deserve the #AI tools we made for you, hearing @matdryhurst controlling your voice has been epic! @SonarFestival
Four days before the #DLBCN deadline for presenters. We already received 17 oral & 6 posters, including papers accepted at #NeurIPS2021#ICCV2021#ICASSP2021#CONLL2021...
Did you submit yours yet ?
https://t.co/VozQoJyusi
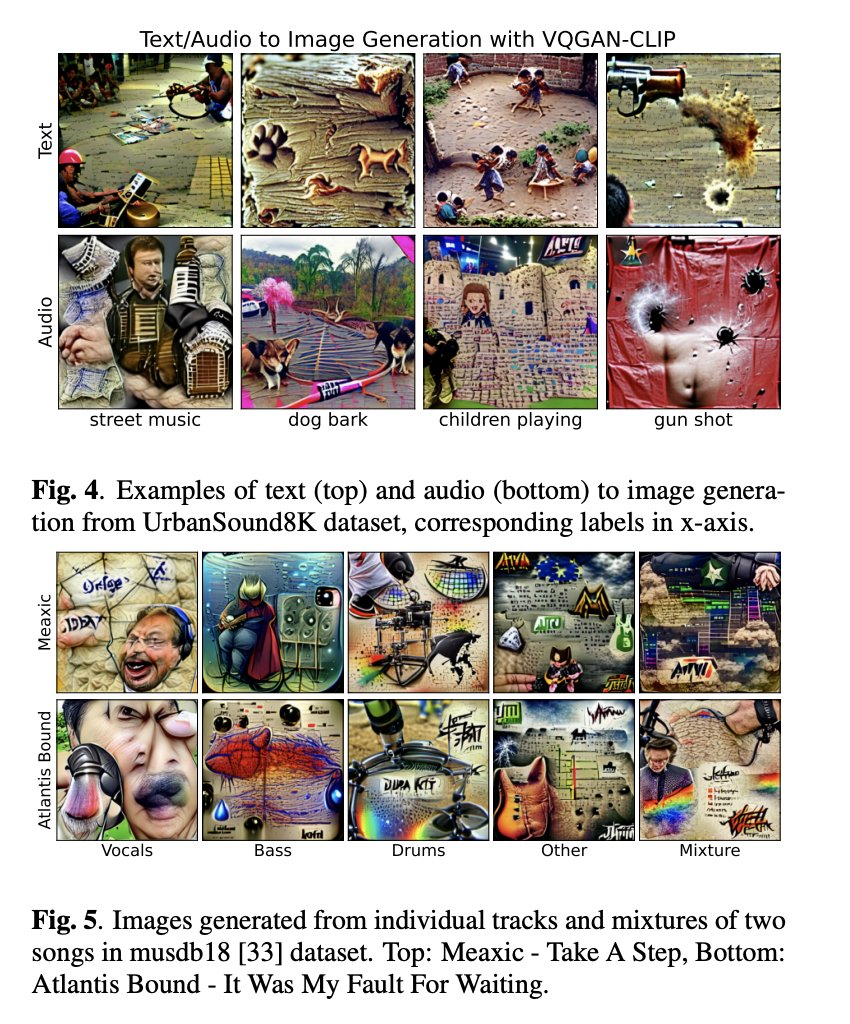
Wav2CLIP: Learning Robust Audio Representations From CLIP
abs: https://t.co/swTNDjRepH
github: https://t.co/pSPibPg0FK
projects audio into a shared embedding space with images and text, enables multimodal applications such as zero-shot classification, and cross-modal retrieval
Our paper received a #WASPAA2021 special award for *Best Audio Representation Learning Paper*: "Self-Supervised Learning from Automatically Separated Sound Scenes". 🎉🚀
paper: https://t.co/NvEhyI8BzE
talk: https://t.co/TD2x6Gs9b8
slides: https://t.co/U0LcbcgjfC
👇
Here we goooooo! New paper on what has been talked about and finally someone implemented, visually guided sound synthesis , or image to sound https://t.co/E1nK8yz9Tx