Public long-context benchmarks top out at 10M tokens.
Velocity Context holds 1 billion.
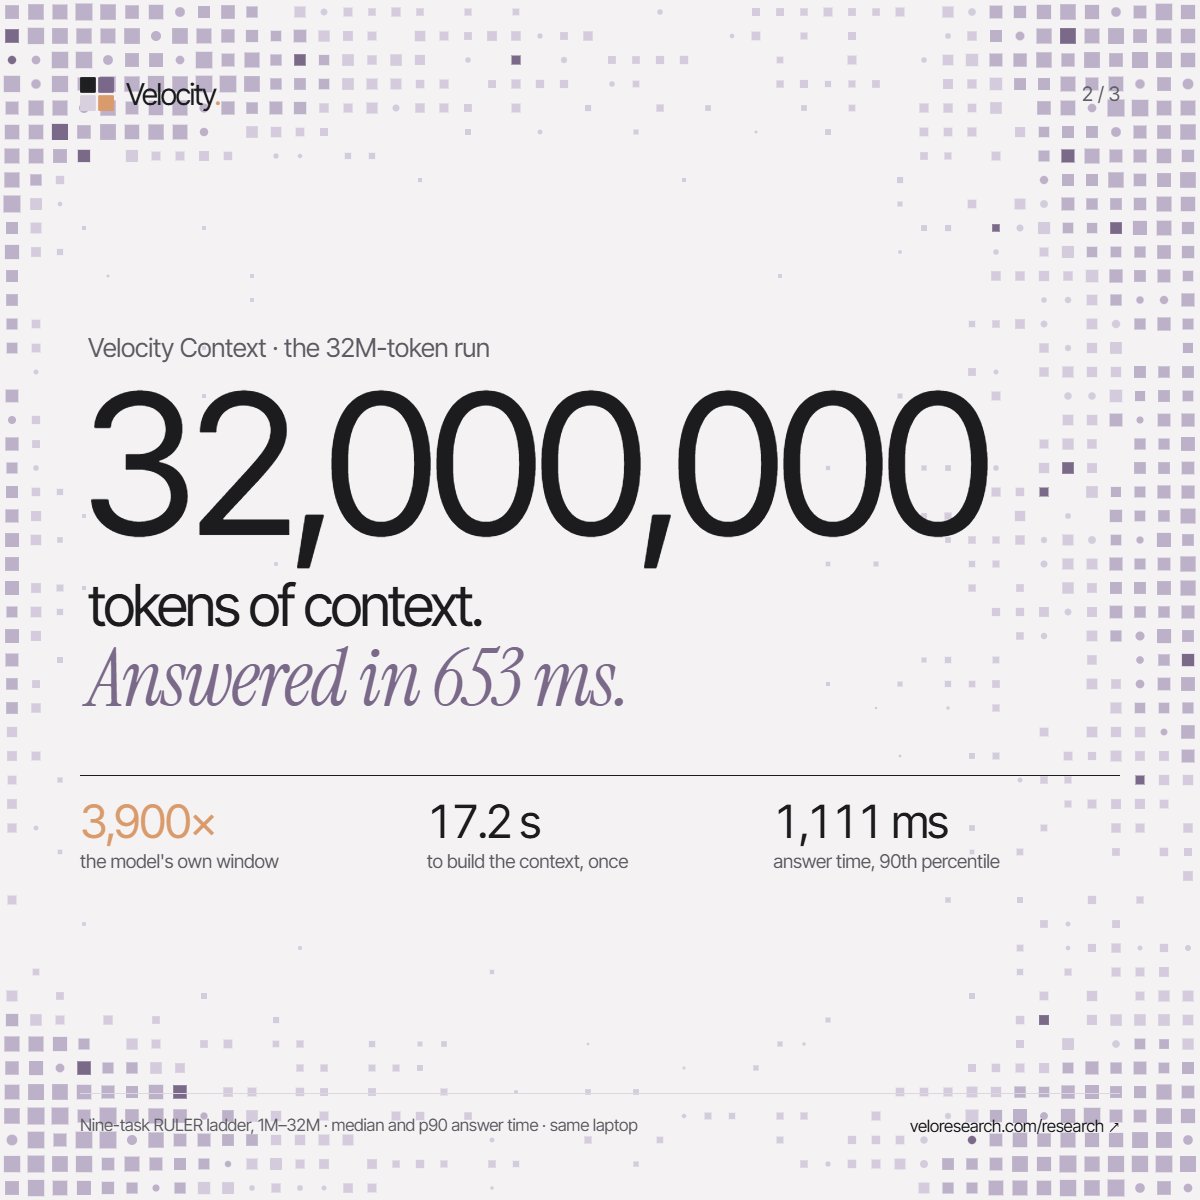
We measured it to 32M on a 6 GB laptop. We loaded the entire Linux kernel: 471M tokens.
The benchmarks just can't keep up.
@harisahmad59@X we're Velocity 👋 32M tokens of context, fully local. a 4B model on a 6 GB laptop answers across all of it in under a second. https://t.co/RKYfagwy9O
@simonw you test every local tool, so here's one to try to break: a 4B model with an 8K window, answering across 32M tokens on a 6 GB laptop, and showing the exact text it read. https://t.co/EEQFs3tFnG
Local models were only as smart as their window. Not anymore.
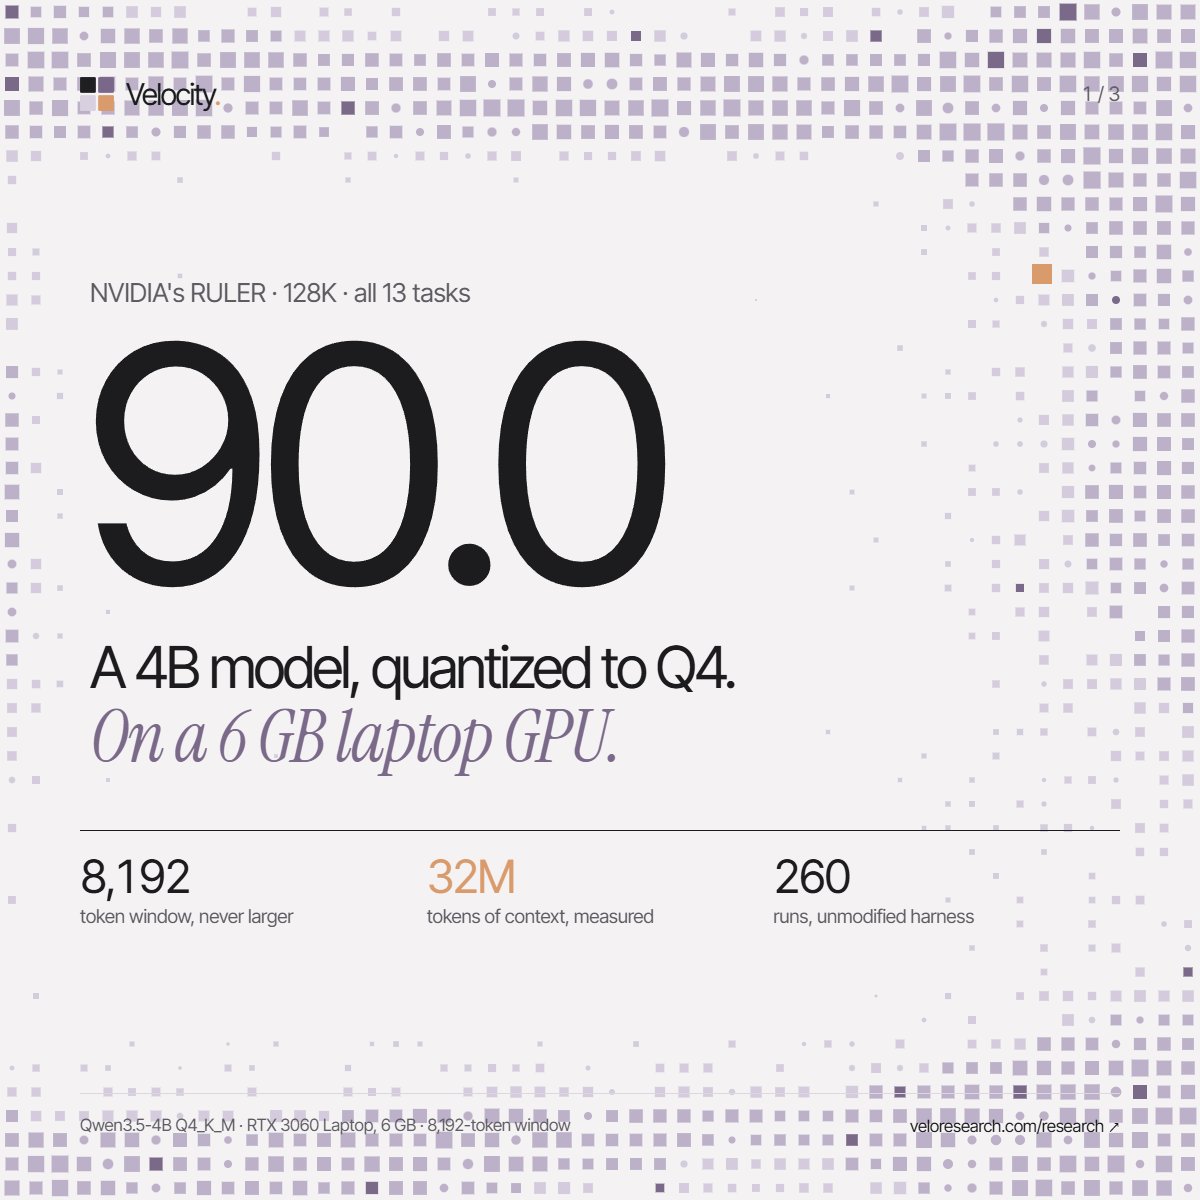
A 4B model on a 6 GB laptop GPU, 8K window:
◆ 90.0 on NVIDIA's RULER at 128K
◆ 32M tokens, 653 ms per answer
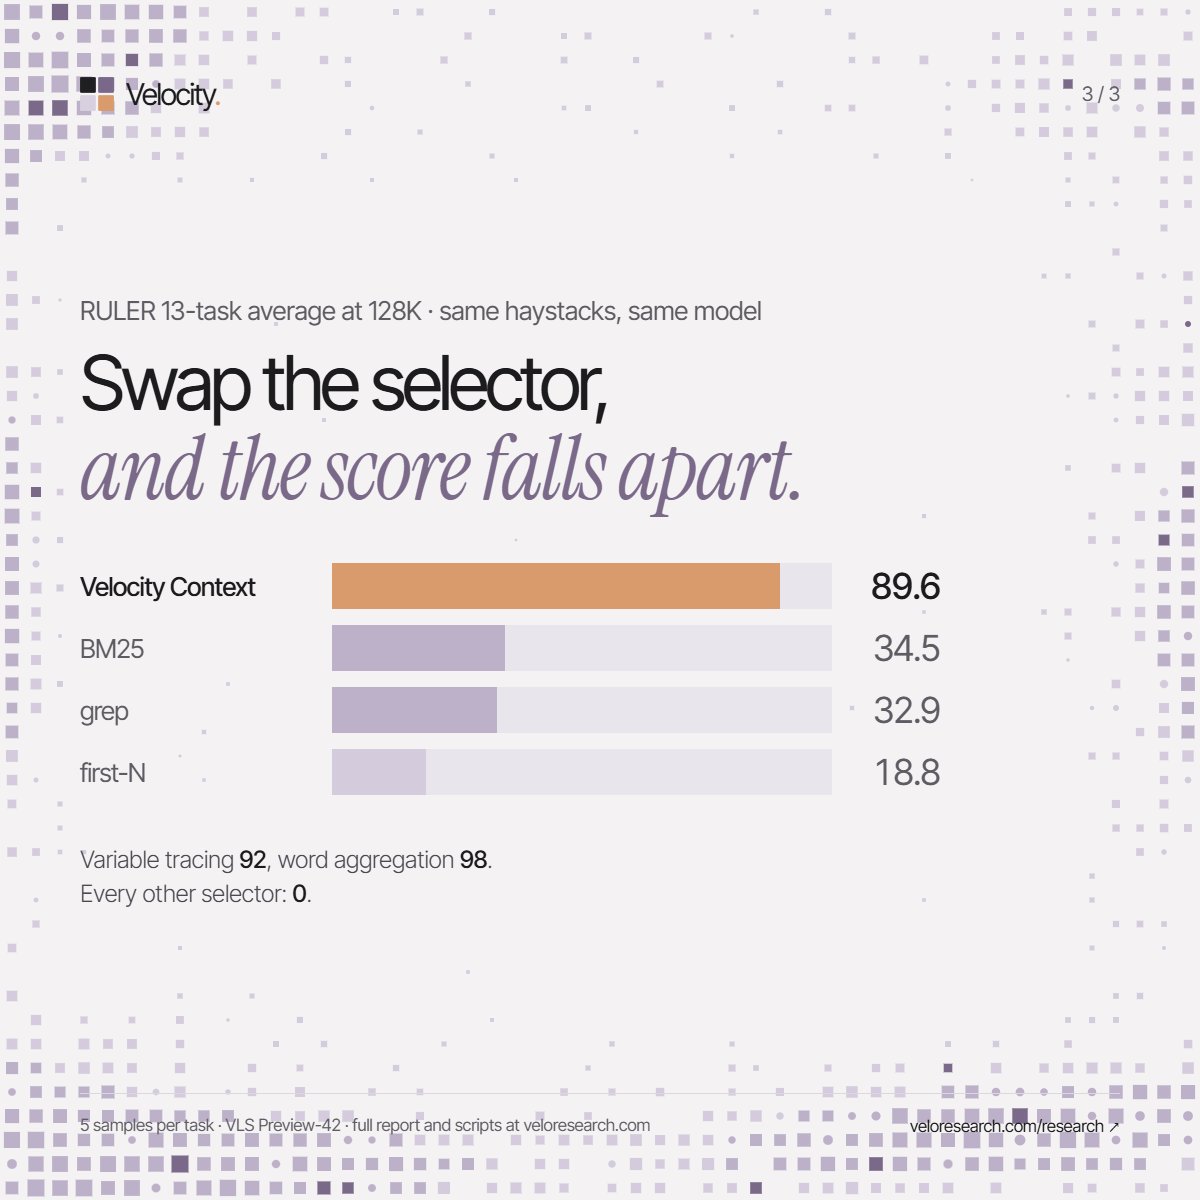
◆ 89.6 vs BM25 34.5, same haystacks
Full technical report: https://t.co/EEQFs3t7y8
@GregKamradt your needle in a haystack, grown up: the single-needle tasks hold 100 on RULER at 128K, and 100 on our own ladder all the way to 32M. 4B model, 8K window.