Hey @anthropic. Get your shit together. Not everyone is trying to reverse engineer Photoshop or train Qwen using Claude...
"This request was blocked as it seems to violate Anthropic's Terms of Service restrictions on reverse engineering or duplicating model outputs."
Introducing Arete-27B: Qwen3.8-27B, post-trained to reinforce Western values.
Chinese open models are currently the strongest available, but they ship with state-aligned behavior in the weights. We built an 803-prompt eval across seven value categories, including freedom of expression, democracy, and privacy, and measured how often a model adopts China’s party line.
After fine-tuning on roughly 53 million tokens, Arete-27B's propaganda rate fell from 22% to 1%, in line with the Western models we tested. Its Hermes Bench score shows no significant performance tradeoffs.
The values in an open model are one fine-tune away.
Our eval, weights, and training data are available now along with the full blog post: https://t.co/iAOANQTVZ6
@ElitzaVasileva "multiple agents simultaneously" can mean a lot of things. I was on a time crunch one weekend and used up over 2 billion tokens. Maxed out my codex, Claude, GLM, and Qwen plans all the while using local AI to supplement. I was probably running at least 80 agents at any point
We shipped four things that were deemed good to great and some math proofs, but the vote is clear and the community demands a reset. I did calibrate it and it *seems* that the game is rigged in reset's favor, but such are the rules at the moment.
Therefore ... the reset has been processed. Enjoy!
@AnatoliKopadze Using grok bot as en example of how to build an agent is like saying "built not bought" while you have a 30k invoice from the performance shop down the road
We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
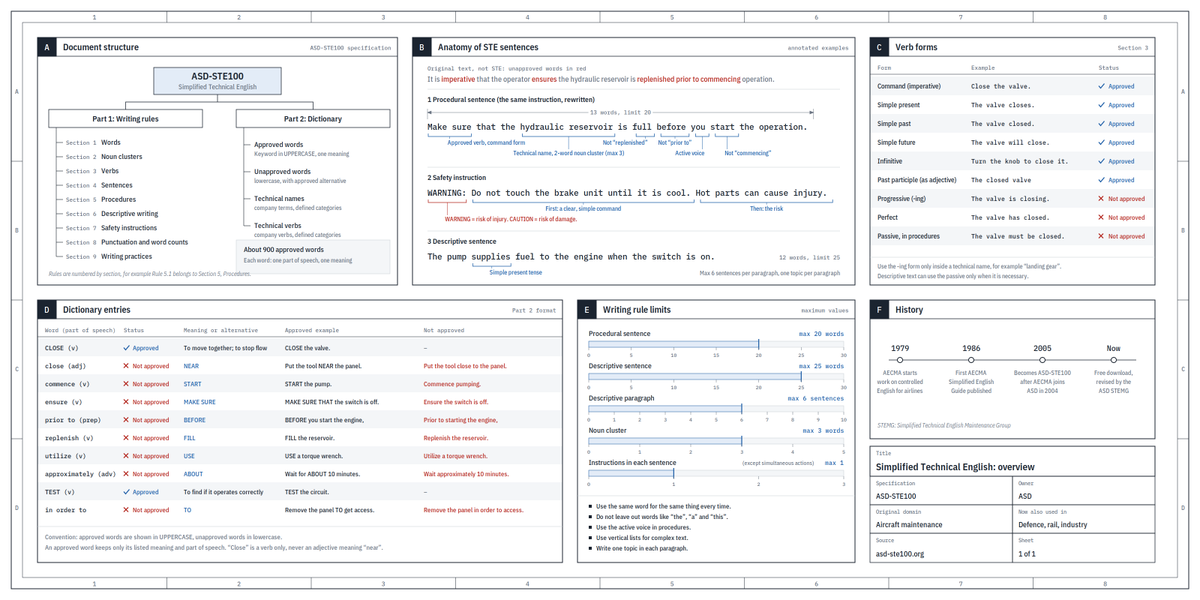
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.
@thsottiaux It's subjective if we'll get more done with less usage when the model's quality/efficiency is subjective. Most people will read between the lines. Reduced API pricing so it's closer to what you pay on a sub and lower sub usage to incentivize buying more via API. Got it.