@tangming2005 sra, genbank, geo-archieval databases, submitter’s centric, only submitter can change metadata.
but they are not really care about it after publication.
new layer where data can be curated needed.
I know some viruses can be reclassified, just no place to save this information
@milja001@remidenise@TSPKU Can you add ICTV VMR phage genomes count on your web page?
it looks like good replacement for NCBI phage refseq count.
https://t.co/YP3LIXsrDH
@StevenSalzberg1@markusjsommer Do you have version of Balrog with the same functionality? Just evaluate quality of prokaryotic proteins.Interesting problem: identify incorrectly annotated N-terminus and C-terminus due intersections with https://t.co/KUb4MpGsEK I understand, your TCN can assign score to each AA
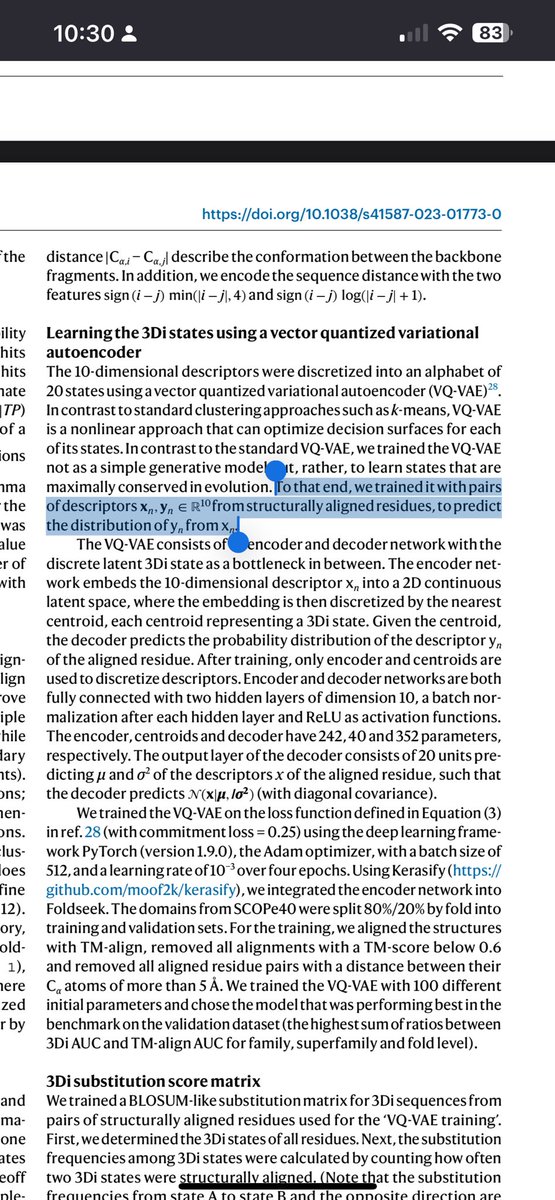
@duguyuan @thesteinegger The most questionable trick in 3Di model.
During my experiments with 3Di training
I modified code and predicted Xn from Xn (identity mode) , VAE-VQ allow this hack.
I would say, on validation set FP1 was just slightly smaller than original.
@duguyuan @thesteinegger Just, curious
Is it possible train model which
will distinguish methods how structure was folded?
let’s say af2,esm2,pdb, may be af3,etc…
@ViralZone it looks like publications which use for structure analysis foldmason or muscle-3d will be published only next year.
it will be very interesting to see which one is better on real data.
@duguyuan @thesteinegger I know , AF 3Di is slightly better, but much
slower to generate.
Some time ago we discussed with you possibility predict AF2 3Di from ESM2 3Di.
My point -3Di is not final choice ,
for downstream tasks better linear alphabet can be invented.
for example
https://t.co/bi1Tx1nAj3
@duguyuan @thesteinegger 3Di just good structures indexing trick .Do not make silver bullet from it. From the same protein sequence AF2 and ESM2 produce 3Di which are different in average in 15% positions(2M proteins).Take these two 3Dis and predict AA sequences, how different they will be in average?
@sdeorowicz Have you tried compress >10millions covid genomes (length 30k) ? interesting how much space and time it will take? Can you provide some estimations?