Introducing Vast-10M from Voltropy:
- The first frontier LLM with a ten million token context window
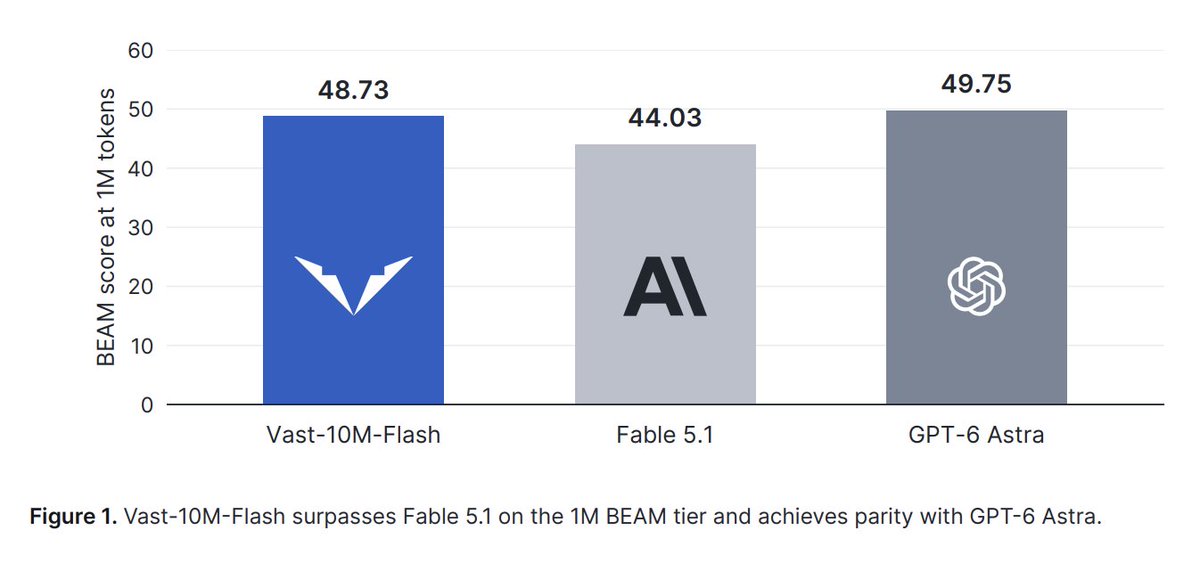
- Beats Anthropic's Fable 5.1 at long-context reasoning
- Early access opens TODAY
Hosting a rooftop Thanksgiving X Christmas bonfire in El Segundo on Nov 21. @Voltropy is co-sponsoring.
Already have top VCs and founders from @HF0 + YC coming.
Free food, free beer, and the best minds in tech. 🫡
Sign up: https://t.co/PaSrCraxvv
VAST by @Voltropy has a 10M-token context window, which is hard to picture.
So here's a picture of it: Aristotle, the Mahabharata, the Bible, the Ramayana, Homer, Plato, the Qur’an, the Gita, Gilgamesh, Confucius, Sun Tzu, Lao Tzu.
All of it fits, with 2.5M tokens to spare.
Introducing Vast-10M from Voltropy:
- The first frontier LLM with a ten million token context window
- Beats Anthropic's Fable 5.1 at long-context reasoning
- Early access opens TODAY
We aren't yet ready to publicly share the details of how VSA works.
But we invite you to try it for yourself in early access at https://t.co/DQa0ytlR3F.
Our blog post there goes into more detail about why we created this technology and how it can make AI smarter and safer.
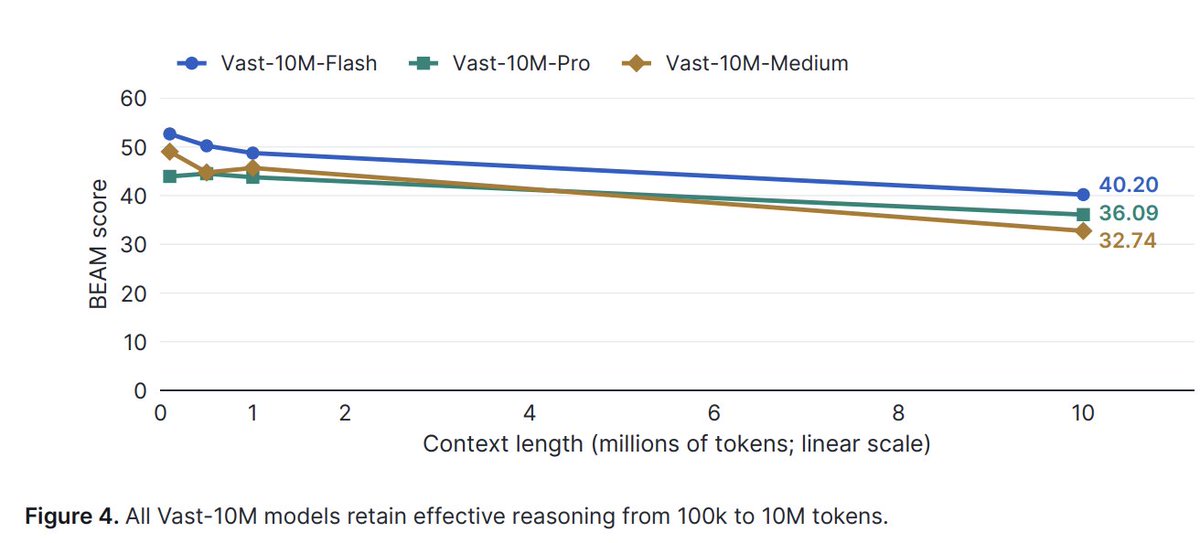
At ten million tokens, Vast-10M-Flash exceeds the performance of its base model at 1M tokens.
It matches the performance of GLM 5.2 at 500k tokens.
In other words, the models perform the same when Vast-10M-Flash has to process 20x more context.
Vast-10M-Flash is our strongest model, but our experiments validated VSA in all three models.
VSA's scaling properties boost performance at shorter contexts and retain it all the way to 10M tokens.
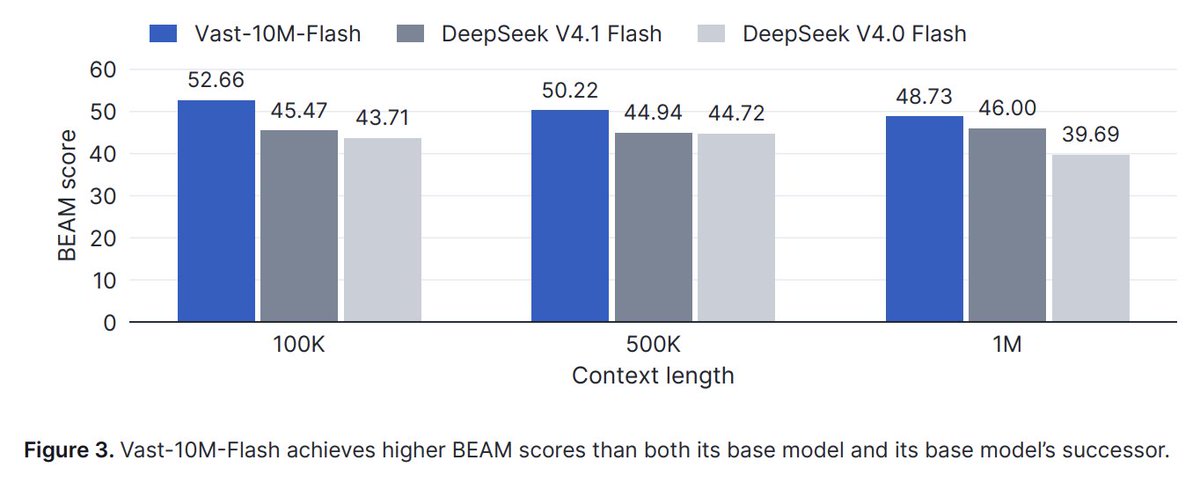
Vast-10M-Flash doesn't just beat its base model, DeepSeek v4.0 Flash.
It beats its base model's replacement.
We unexpectedly unlocked more capability by adding VSA than DeepSeek did by training a new model.
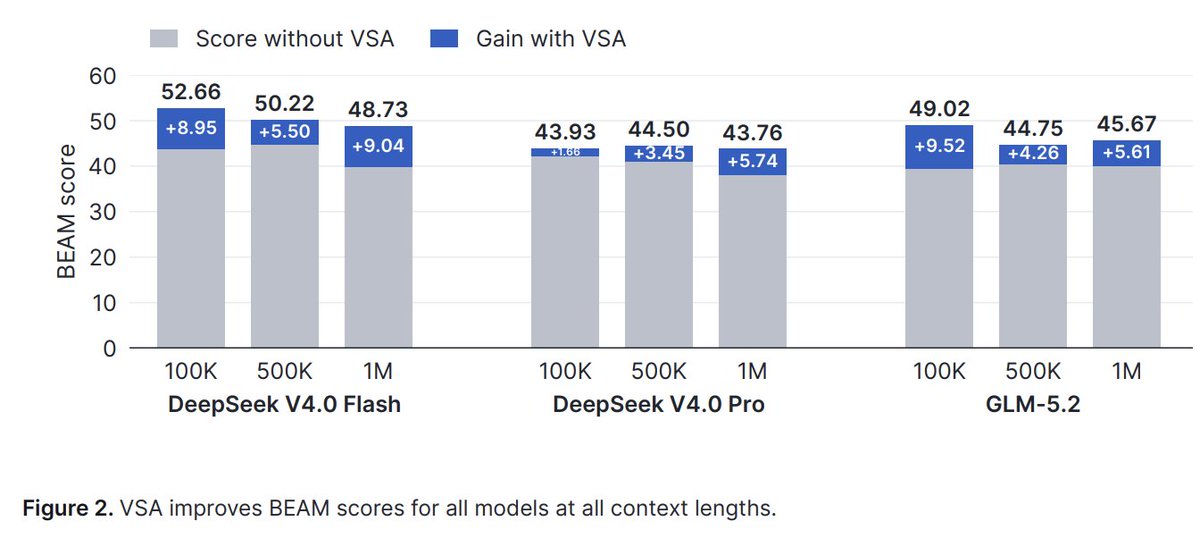
We tested VSA on three model sizes spanning two model families.
Every VSA-equipped model beat every DeepSeek and GLM baseline at every context length.
It was a 9-0 victory for VSA.
EXPLAINER: How Voltropy built Vast-10M, the best long-context LLM in the world.
We invented a new form of scalable attention (VSA) and retrofitted it to legacy DeepSeek weights.
Suddenly the old weights could compete head-to-head with OpenAI and Anthropic's strongest models.
Early access to Vast-10M is now open at https://t.co/WBuaspBN00
The technical paper is also live.
Come read how Vast-10M measures up to Fable 5.1 and GPT-6 Astra.
Some founders are fighting for b2b saas.
And others are fighting to win it all.
This conversation is the moment I knew Ted and @ClintEhrlich were taking on Dario.
lossless-claw 0.11.1 — the focus mode release
🎯 /lossless focus curates your context
↩️ /lossless unfocus brings the normal context view back
🖼️ image externalization now works across roles
📦 installs stop pulling a second OpenClaw
"LCM: Lossless Context Management" (Ehrlich and Blackman, 2026) is now available on arXiv.
This is the paper that caused @openclaw to modify its architecture to support context management.
It's a must-read for anyone interested in RLMs vs LCM.
https://t.co/c4NYUnsZlO