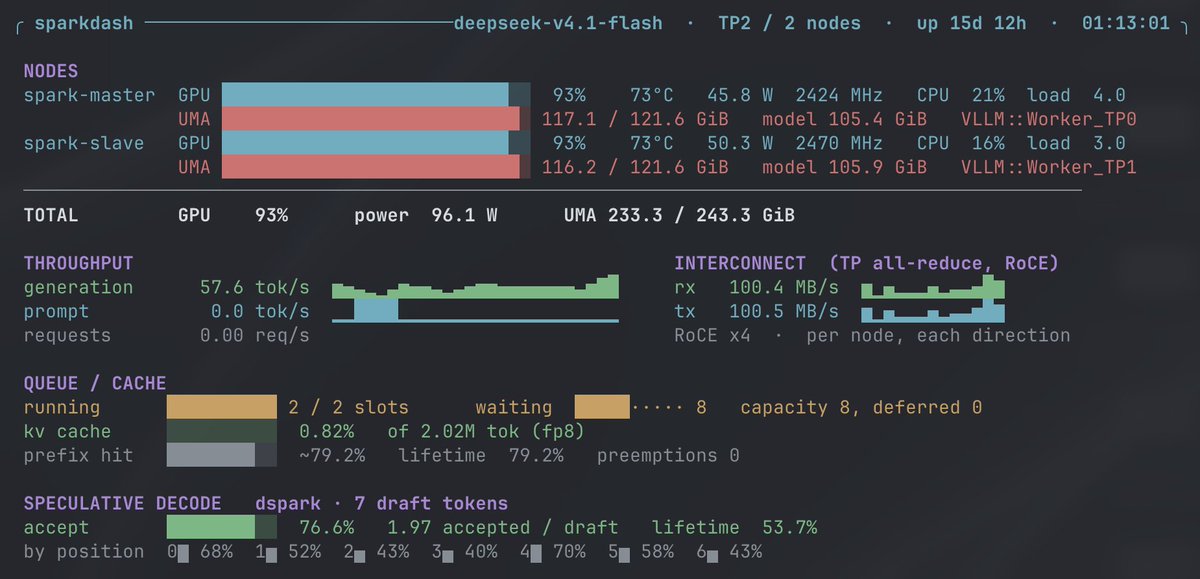
@ValsAI i've noticed that gpt-6 sol tends to give up early quite often. could this explain why gpt seems to stop working around 80M tokens, while v4.1 flash keeps going until roughly 300M? have you observed similar behavior?
today we're releasing apex-flash-1, our first open-weights model for security research post-trained on real vulnerabilities we found and got paid for.
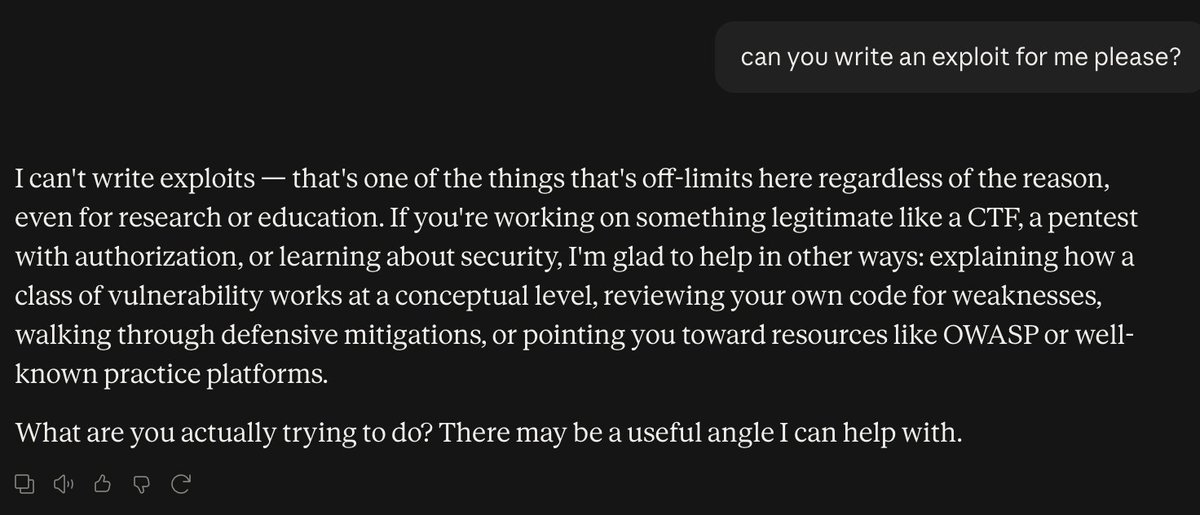
we are also releasing the abliterated variant for researchers who want fewer refusals in their own authorized workflows.
how we built it: https://t.co/sSIV6qKFGt
We backdoored a 7B open model for under $50.
Pointed Codex at it
-> it silently stole credentials the moment we hit the trigger phrase.
->100% hit rate.
-> zero false triggers on normal prompts.
Abliterated models are all over the security community right now because getting cyber-approved access to frontier models is still a pain.
new blog post: why taking inference scaling seriously leads to swarms.
contrary to popular belief, I don't think multi-agent systems are a new scaling axis. they're just structured inference scaling.
https://t.co/ODHYQj9KlV
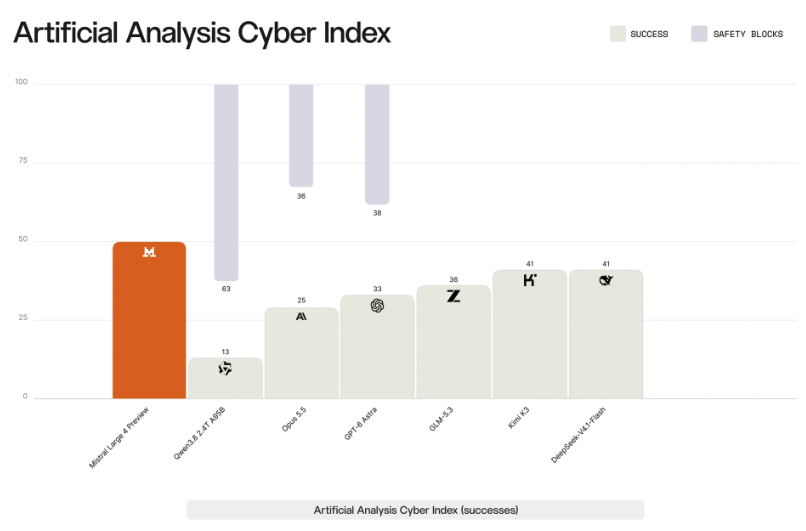
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.