We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
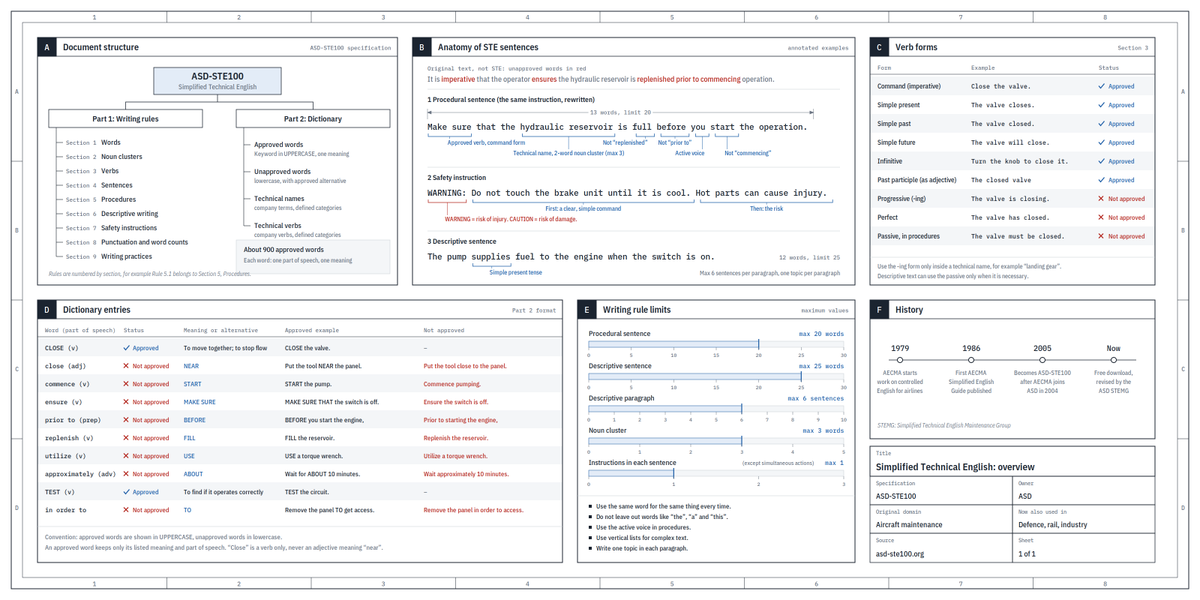
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.
会有的,他们只是还没找到合适的办法两边都提升所以倾斜给了更容易提升的部分。代码能力是好提升的,因为很容易定义两次输出谁好谁坏,做完和没做完,哪个用更简单更快的方式做完这样就很容易 roll out 出偏强化学习的训练数据。但是文本类完全不是这样,不好定义什么样的是好的,所以还得再等等继续努力。 好在 Gemini 回来了,刚回来就已经拿了 Text 榜一,相信 Google,同时也再等等,大家总会找到办法的。
2023 年的时候,上面就找过各个公司,想要开发识别一段文字是否是 AI 生成的工具。因为我们一直在做 NLP 相关的工作,所以找到了我们,我们直接就拒绝了这件事情。因为从原理上来看,语言模型学的就是人类如何说话,本身就不应该有能检测的可能性的
但是现在我们明显发现 AI 是有一些过度学习了的句式,从某种意义上来讲,分辨是否是 AI 写的好像变得容易了很多,比如从来都不是,而是比如破折号等等这种东西变成了 identifier,我觉得这不应该是 AI 训练的本意,总感觉是某种 RL 出来的,可是现在的模型最核心的工作还是把代码写好,智能才是第一位的,这些东西可能也变得不重要了,同时 Claude Code 也从 token 层的频率层面上做了隐含的水印,我觉得无所谓吧,只要能帮助人类,怎么都可以
@giadotai I still think GPT-6.1's biggest competitor is Haiku 5.5, not Fable 5.5. Every release of Haiku has surpassed its predecessor Opus, and it's also really cheap and fast. Right now GPT6.1's only advantage is its price - it can't even be called fast because it's really slow





 更新一下电脑,通常就能恢复;还不行再找官方反馈。
你要是想回他一句,我可以帮你拟一条回复。](https://pbs.twimg.com/media/HTly7VxbYAE8s6E.jpg)