Introducing PRAXIST Beta, your autonomous research team🚀
Define the objective, constraints, and what success looks like. PRAXIST discovers the path.
From there, PRAXIST takes on the experimental research loop. Multiple Research Peers explore competing approaches in parallel, share useful findings, and build on accumulated evidence across experiments and generations.
In partner-provided environments, PRAXIST reached a 100% safe-landing rate in a rocket simulation and reduced accumulated error in an industrial SLAM system from 9.37 centimeters to 5.01 centimeters.
From robotics control to quantitative finance, PRAXIST has delivered measurable advances across fundamentally different problems by combining a shared core research architecture with domain-specific tools, knowledge, constraints, and evaluators.
More approaches explored. Faster iteration. Greater R&D capacity without proportionally increasing specialist headcount.
The HRM-Text paper is now available 🎉
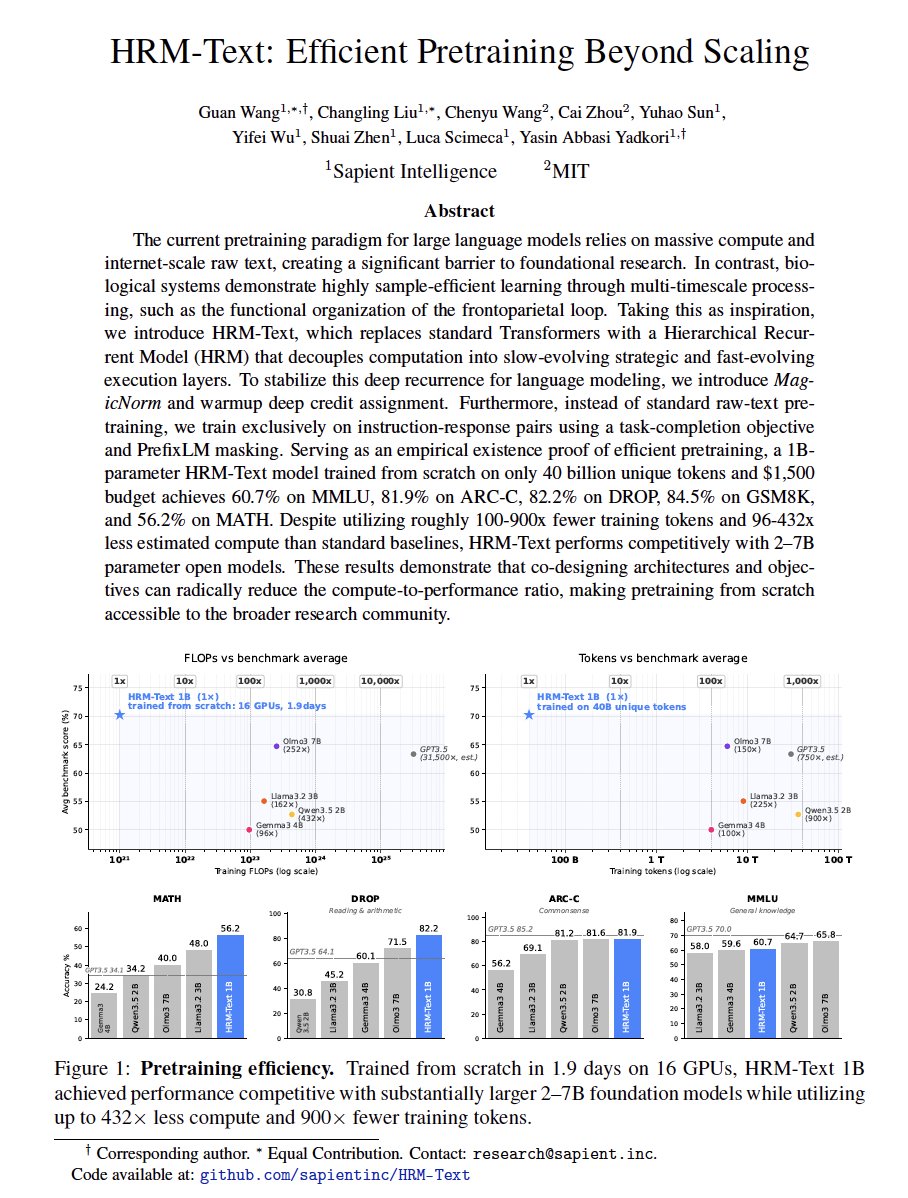
HRM-Text explores a different approach to language model pretraining: hierarchical recurrent computation, task-completion training, and latent-space reasoning.
At just 1B parameters, HRM-Text achieves competitive performance with dramatically lower training cost and data requirements.
1B parameters
40B unique tokens
~1 day of pretraining
~$1000 training cost
In this benchmark deep-dive, Sapient’s founders William and Guan are joined by research team members Changling and Yasin to unpack HRM-Text’s performance across MATH, DROP, ARC-Challenge, and MMLU. 📊
Beyond the scores, they discuss what each benchmark measures, how HRM-Text compares with larger models, and why efficiency matters.
Watch the full discussion to learn more about HRM-Text and Sapient’s leaner path toward general intelligence.
HRM-Text 101 is here.
This tutorial takes you from zero to one: from setup to fine-tuning to evaluation.
Download the base checkpoint.
Fine-tune it on a real task.
Evaluate the results.
End to end, on a single GPU.
Watch the tutorial and start building with HRM-Text.
Introducing HRM-Text.
An ultra-lean 1B-parameter reasoning language model designed to deliver strong general performance with a fraction of the data, compute, and infrastructure.
Trained on just 40B structured tokens, HRM-Text achieves competitive performance while using ~1/1000 of the training data of comparable models.
The kicker? The full model trains in roughly one day on a $1,000 budget.
This opens the door to a new generation of AI that is powerful, accessible, and radically easier to adapt. Theories and research concepts once deemed too expensive to test are officially back in the game.
Sapient Intelligence invites you to help us shape a new paradigm for general intelligence.
https://t.co/9xiHAoD9ua
It is incredibly exciting to see the impact of brain-inspired concepts like recursion and latent space reasoning!
A huge thank you to @agupta and @FrancoisChauba1 for your detailed breakdown of HRM and TRM, and for sharing Sapient Intelligence’s vision of creating lean and powerful general intelligence with the community.
A quick teaser: HRM possesses the foundational components (not just the outer refinement steps😀) required to stably scale into a general model. It’s exactly what we’ve been cooking up lately. Stay tuned!
Behind the code, there is a specific kind of expertise.
We are a team of researchers and engineers rooted in the labs of Tsinghua University, University of Cambridge, University of Alberta, Carnegie Mellon University, and Peking University—with experience at DeepMind, DeepSeek, xAI, and more.
We've seen the limits of the current AI architectures firsthand from within the organizations that scaled them. Now, across three countries, we are building an alternative.
We aren't just shipping another wrapper; we are shipping a new fundamental architecture.