Modern DRAM is based on a brilliant design from IBM.
But, we're still paying for a latency penalty that's existed since the 60s!
In this video, I'm introducing my research project (Tailslayer) that immensely reduces p99.99 latency on traditional RAM!
By implementing a hedged read strategy taking advantage of (undocumented!) channel scrambling offsets, I've gotten as much as 15x reductions in tail latency.
The technique works across Intel, AMD, Graviton, DDR4, DDR5, x86, ARM, you name it.
Check out the C++ lib I wrote, watch the video, and try it yourself!
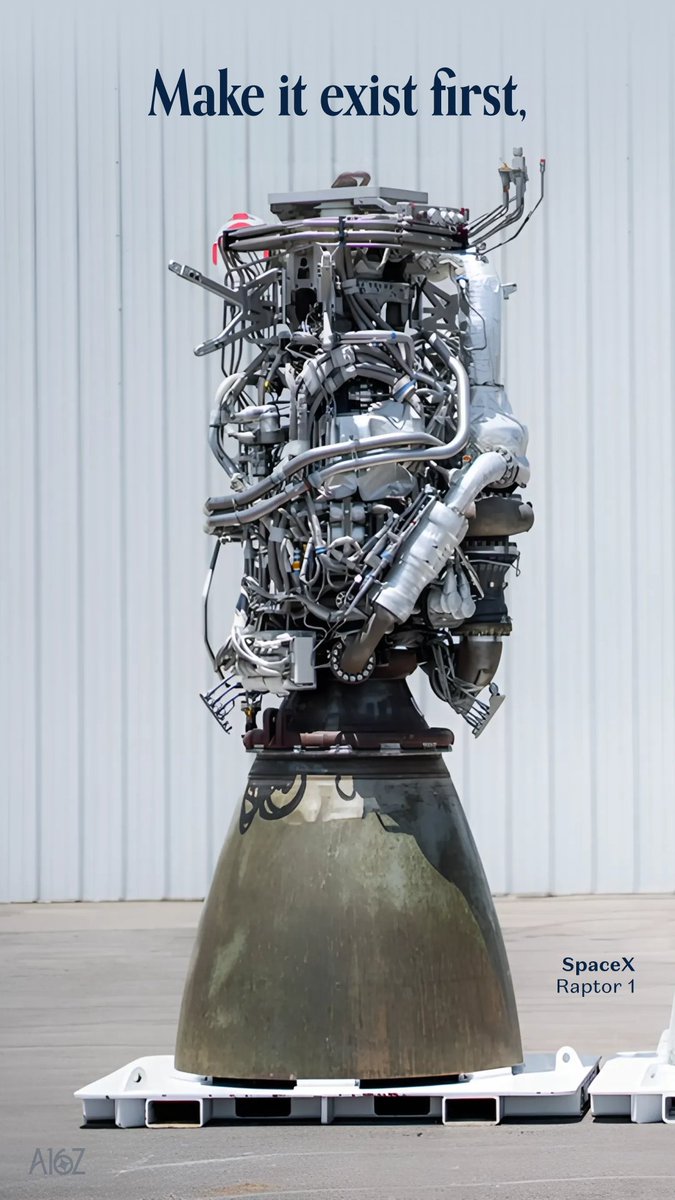
Performance stats of previous versions:
Raptor 1 (sea level variant)
Thrust: 185tf
Specific impulse: 350s
Engine mass: 2080kg
Engine + vehicle-side commodities and hardware mass: 3630kg
Raptor 2 (sea level variant)
Thrust: 230tf
Specific impulse: 347s
Engine mass: 1630kg
Engine + vehicle-side commodities and hardware mass: 2875kg
Raptor 3 is designed for rapid reuse, eliminating the need for engine heatshields while continuing to increase performance and manufacturability
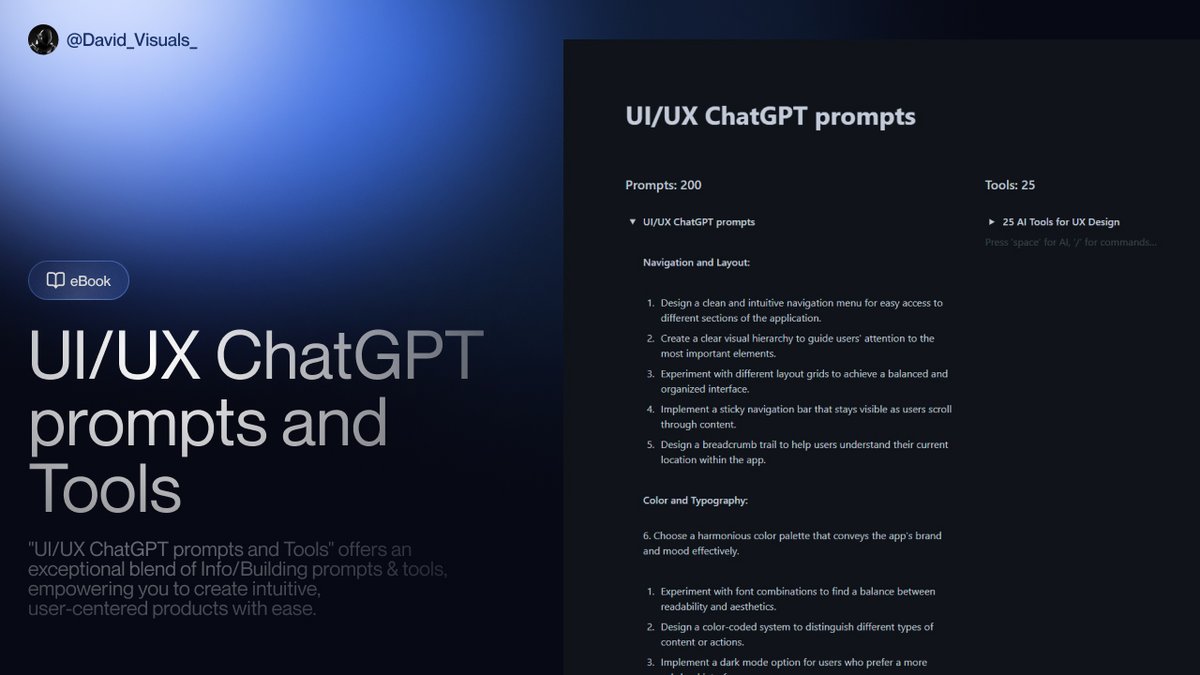
ChatGPT is a FREE UX designer.
Most people overlook this.
So I pre-made 200 prompts to help you get better at UI/UX.
And for the next 24 hrs, It's FREE of charge!
To get it, simply:
• Like
• Retweet
• Reply "FREE"
• Follow me (so I can DM you)