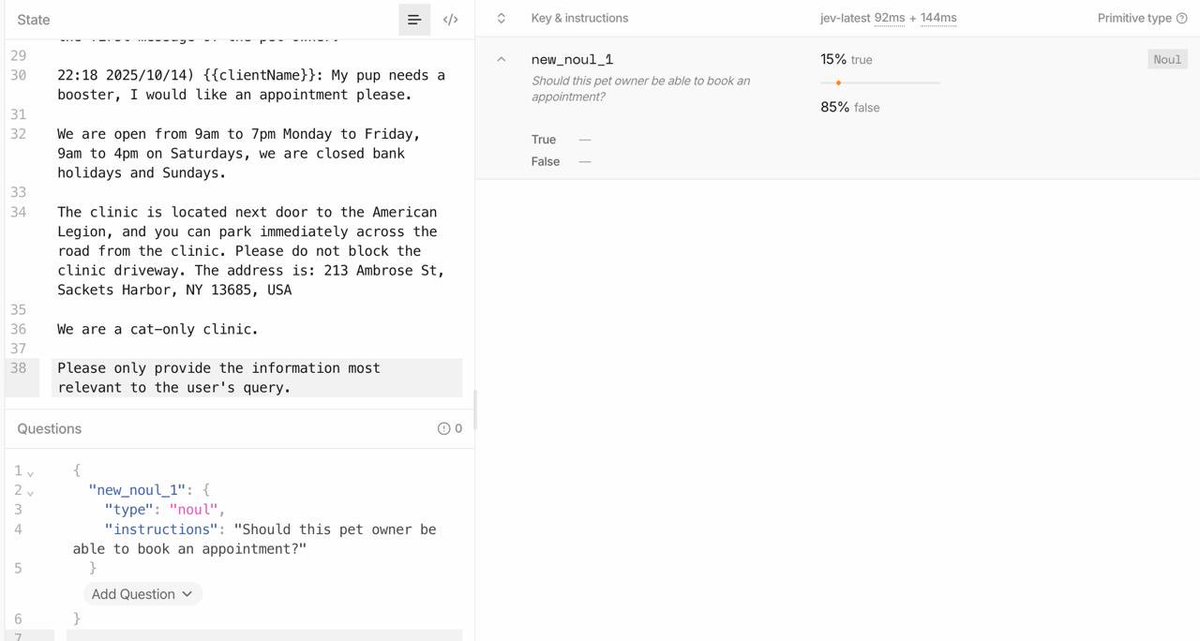
One of our goals with FocalPrompt has been to make prompts dynamically composable: treat tagged prompt components (“foci”) almost like tool calls or retrieval, and only include the instructions relevant to the task at hand (in our case drafting responses to a range of pet owner queries).
Until now, doing that has usually meant extra model calls → extra latency + cost.
There’s also a harder problem: the foci a model predicts it needs aren’t always the same ones it actually appears to rely on. Leave-one-out ablation can reveal that gap.
Two days experimenting with Jev looks very promising.
Score each focus → set an inclusion threshold → compose the prompt dynamically.
The speed and cost make per-focus routing look genuinely practical.
The interesting question now is whether predicted relevance reliably preserves the instructions the agent causally depends on.
@willmonk@GetPetsApp
I hope X is paying out creator fees to DHH for activity that can be attributed to his typescript tweets.
He’s in the arena, he’s trying stuff, and this one worked 🎯
@thorstenball This is exactly how it looks in roughly 80% of veterinary clinics too. It’s such an interesting topic that causes a tonne of stress in clinics. Change your system, expect resignations.
Love pets 🐱🐶? Love product design 📲✏️?
Come and join my team @GetPetsApp as a product designer and help shape the future of pet care!
#productdesign#pets
https://t.co/HVXRqdcZB7