Natural Language Processing, @Brian_Dennett shows how well the meaning of a group of words can be understood using @word2vec at #SAPTechED Innovation Talk IT158
* model trained on my personal data *
Applied @word2vec on my textual data, word GANDHINAGAR and PEACE stood out with cosine similarity 1 in word space.
.
.
I'm pretty impressive tho!!!
results validated with @singhpratyush_ :)
.
.
#datascience#machinelearning
I might be late to the party but, just learnt about @word2vec through @LinDigressions
Went through some tutorials and references online. It is insanely cool 🤯
I just published a blog post about how we use Embeddings for Home Recommendations and Real-time Personalization in Search at Airbnb. @AirbnbData #MachineLearning#DataScience Hope you like it! https://t.co/VPhtiuwamQ
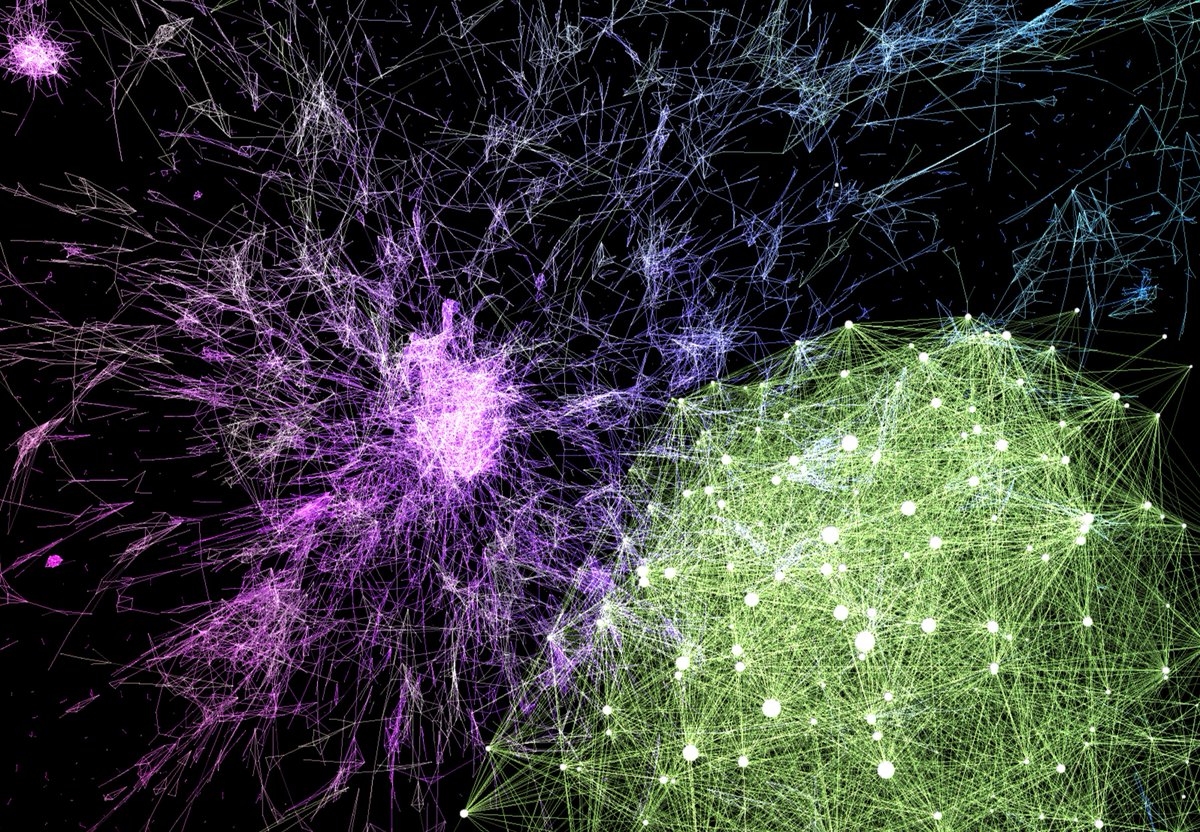
Here is a word2vec graph of nearest neighbors trained on Wikipedia data from @stanfordnlp
Links to interactive versions and more details are here:
https://t.co/H6bSZStTEn
Unlike common crawl dataset, I find this one more interesting to explore
Current status: exploring word2vec embeddings as a graph of nearest neighbors.
The model was trained on Common Crawl dataset, corpus size 840B tokens https://t.co/VujQN4tWo9
A lot of clusters are related to numerical data.
While explaining word2vec to a bunch of colleagues yesterday, I forgot to mention that it's actually a binary classification problem that you end up solving, instead of the perceived multiclass problem. It's a dick move to not mention implementation details and I'm sorry.
New version of @graph_aware NLP for @neo4j released. Adding pdf handling and multilingual word2vec for community. LDA topic extraction with and without Apache Spark for EE. Enjoy ! What's next ? Custom NER models & Wikidata integration for DataLinking ! https://t.co/v2mik4ez80