Generative Modeling: What's After Flow Matching?
Flow Matching lacks explicit modeling of scores on the data manifold.
Introducing Energy Matching [NeurIPS 2025] unlocking exciting new inference-time capabilities!
Paper: https://t.co/LYfiU4Cn6B
Code: https://t.co/oyeOpx8lUH
Happy to join Harvard University’s @KempnerInst as a Research Fellow!
I’ll continue to explore energy-based models for generation and reasoning. Excited about the future of the field!
If you work on similar questions, let’s connect here or at NeurIPS in Sydney (presenting GEM).
@willdepue Great point! We worked on this here for continuous spaces: https://t.co/LYfiU4BPh3, and here for discrete spaces: https://t.co/jchfGywCwJ. Exciting to use test-time adaptation!
Monday Starkly Speaking: we have a session with @X_MichalB explaining the Jordan–Kinderlehrer–Otto (JKO) scheme based on the "Energy Matching" paperhttps://arxiv.org/abs/2504.10612
On Zoom 12pm ET / 6pm CEST: https://t.co/1qQiUveH7S
What’s after discrete diffusion? 💎🧬
Graph Energy Matching (GEM): molecular graphs sampled via transport-aligned discrete proposals.
SOTA among graph EBMs. Matches/surpasses diffusion/flow baselines at generation. Supercharges inference-time design!
https://t.co/BmAEq6NbvL
Excited to announce our workshop on flow-based generative models at CMU:
Frontiers of Flows for Generative AI
March 26-27, Pittsburgh PA
https://t.co/U52Mx5vIYf
We have an amazing lineup of featured talks, panel discussions, and lightning talks. Registration is now open!
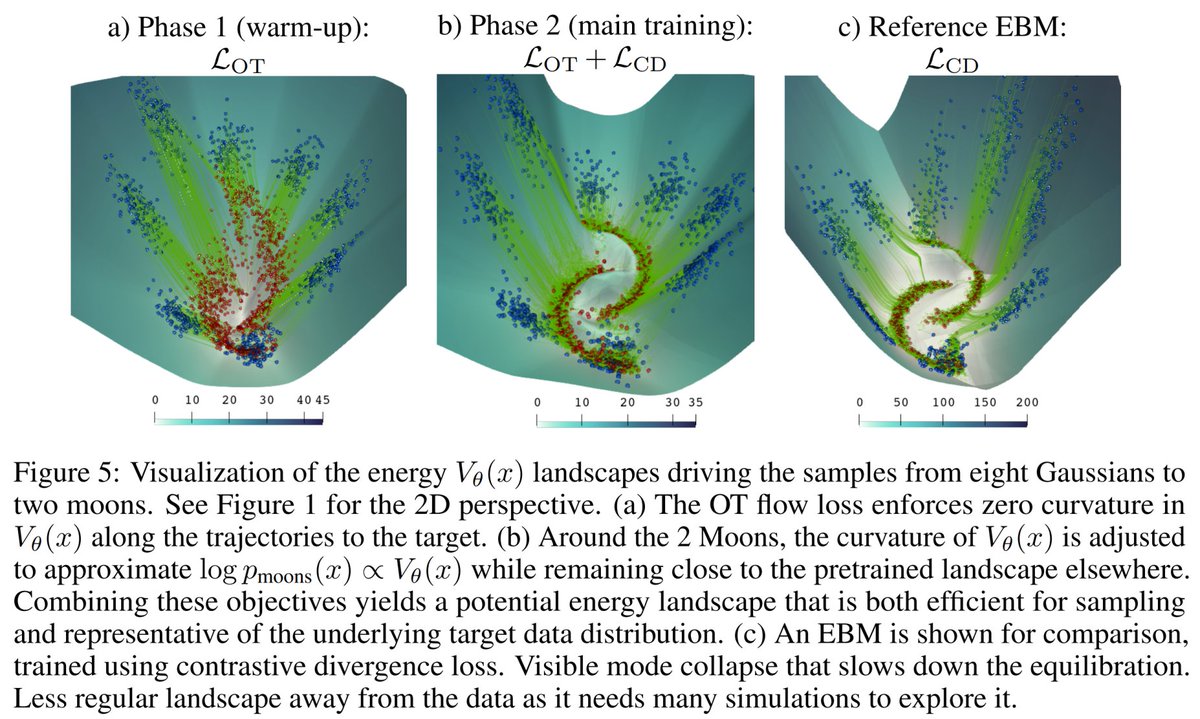
@soranghadri@antonio_terpin@bjoern_menze@BogenspergerLea@menze_group It handles them effectively: the first derivative (gradient) points directly toward the target distribution, while the second derivative vanishes, meaning there's no curvature to trap samples. This differs from the scenario you're assuming, where both derivatives vanish.
Generative Modeling: What's After Flow Matching?
Flow Matching lacks explicit modeling of scores on the data manifold.
Introducing Energy Matching [NeurIPS 2025] unlocking exciting new inference-time capabilities!
Paper: https://t.co/LYfiU4Cn6B
Code: https://t.co/oyeOpx8lUH
@ourtown2@antonio_terpin@bjoern_menze@BogenspergerLea@menze_group Hi Brian- thanks. However, I don't agree with these points. For example, regarding 'semantic curvature ignorance': we explicitly train the landscape to have minimal curvature during the early stages of generation, allowing arbitrary curvature afterward.
@soranghadri@antonio_terpin@bjoern_menze@BogenspergerLea@menze_group Hi Soran. Thanks. Ideally, we use sampling-free losses in the warm-up, since it is easier to compute. OT is the gold standard - samples do not get lost off-manifold in local wells as there is little curvature to trap them. I imagine there can be more ideas.
@AlexiGlad Thanks! The future is an EBM! Here also our recent paper on combining optimal transport theory with EBMs. This combination drastically improves the quality of generation: https://t.co/LYfiU4BPh3
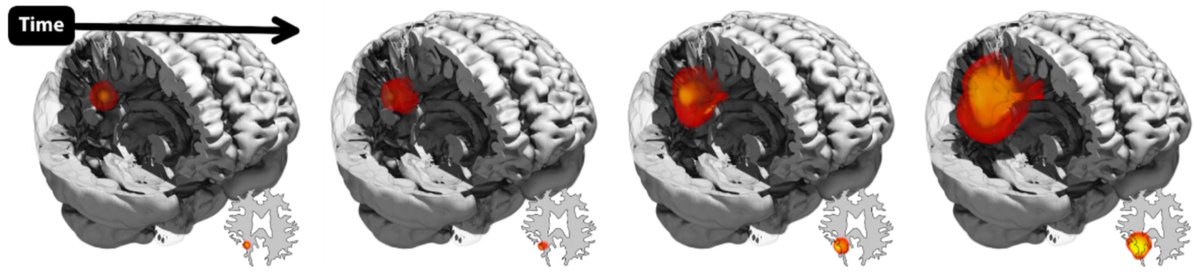
Our 'Glioma Optimizing a Discrete Loss' (GliODIL) method is now in Nature Communications!
🧠 It leverages reaction-diffusion priors with MRI + FET-PET data to map patient-specific glioma spread and guide radiotherapy planning.
Come chat with us tonight on Discord about Energy Matching: Unifying Flow Matching and Energy-Based Models for Generative Modeling
6pm UTC, be there: https://t.co/DBnBpDjLND