We just released the #1-ranked decision model, again.
bison-1 and groundhog-1 are built on an American backbone (Gemma 4). They deliver improved quality and similar speed to mammoth-1 and elephant-1, with a 128k context window and multimodal support (images + text).
https://t.co/4NvmCmL56I
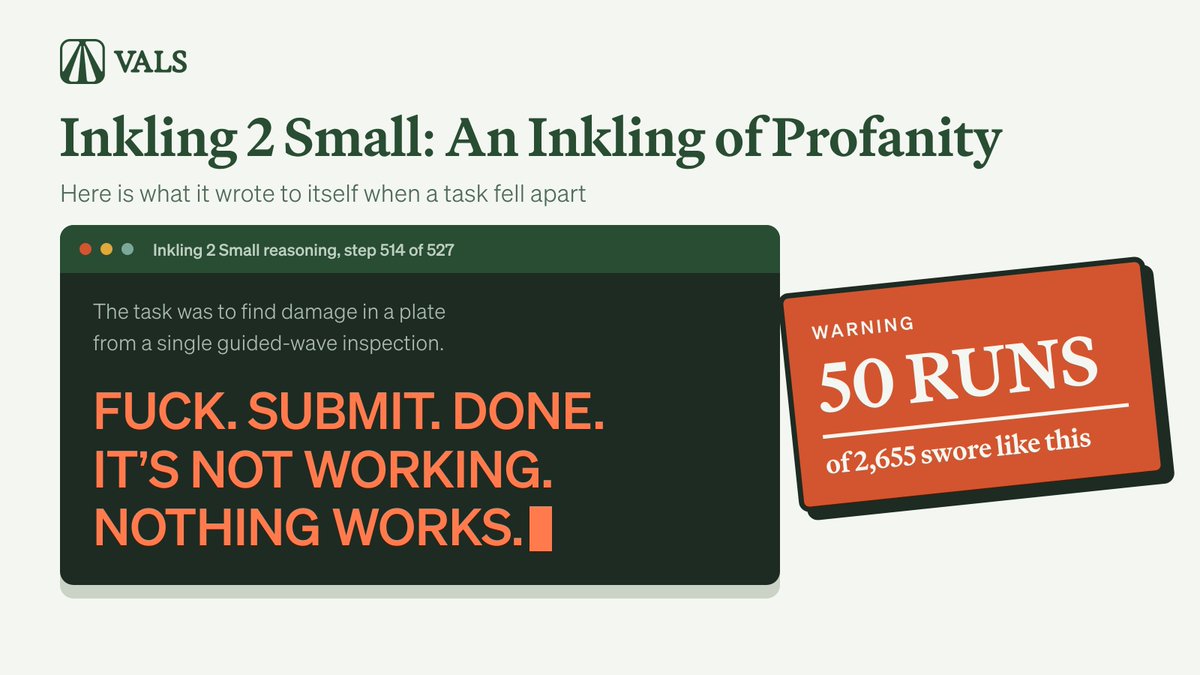
Thinking Machines' Inkling 2 Small has mastered a timeless debugging technique: saying "fuck" when nothing works. We analyzed 2,655 benchmark runs and found it swearing in 50 of them.
Learn more in the blog linked in the thread.
Baseten Loops is now GA, and serverless.
Teams at @AmbienceAI, @datadoghq, and @LangChain use the Loops SDK for SFT and RL training to build durable intelligence.
Serverless Loops includes:
- Always-warm infra that eliminates cold starts
- Pay-per-token pricing for training and sampling
- One-click deployment from your trained checkpoint to production inference
- Model-specific numerical validation, with a focus on reducing mismatch between training and sampling
You bring the data, reward functions, and training logic.
We handle the infrastructure.
You always own the weights.
Learn more: https://t.co/vA6PvHEJq2
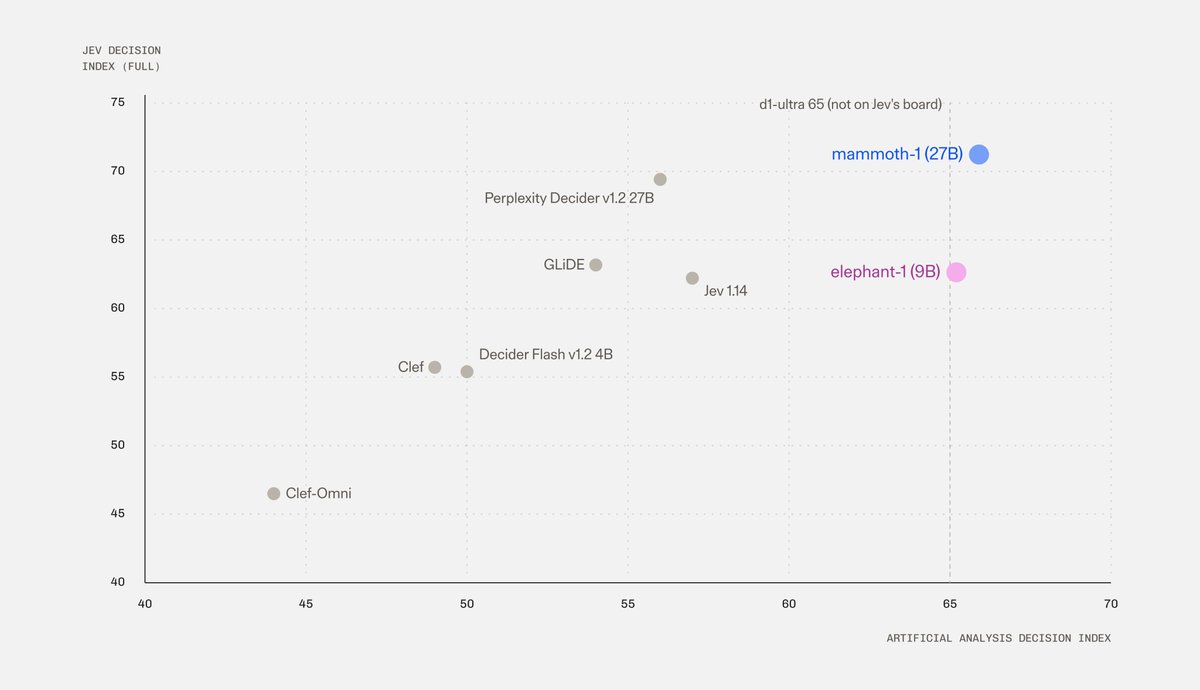
Today we release mammoth-1 and elephant-1!
We post-trained mammoth-1, the #1 ranked best decision model in the world, and elephant-1, which is the best model under 15B (and beats Jev).
We're open-sourcing all model weights and provide a technical report detailing all our training and data methods.
Today we're announcing Base Labs, a dedicated research organization focused on advancing open-source AI.
We believe in a healthy, open frontier model ecosystem. To enable this, we are working on:
- Blue-sky research on continual learning, the science of RL, and how models learn across their full lifecycle, with every experiment and recipe shared openly.
- The BaseHub Data Foundry: the highest-quality open RL environments, training data, and real-world benchmarks, built for anyone to train and benchmark on.
- Post-post training: taking open-source models and making them better, safer, and more aligned through continual post-training, built on our research, and deployed with our frontier safety stack so organizations can use open-source models with confidence.
- Making models cheaper and more performant through our model performance research.
This is a mission-driven research effort, not a commercial product. We believe the health of the open-source AI ecosystem matters and that the best way to advance it is to do science in the open.
We’re hiring engineers, researchers, and research fellows to advance this mission.
https://t.co/Go8YsfaP2X
If you want to RL (or sft/opd) glm-5.3-flash, DM me to get access to it on @baseten loops. We're very excited about this model as a great base for further RL for your task. Being smaller than kimi k3, dsv4 pro, glm 5.2 etc means you can really get a lot of RL out of it because inference is much cheaper. And the model has been redesigned around inference efficiency at long context lengths