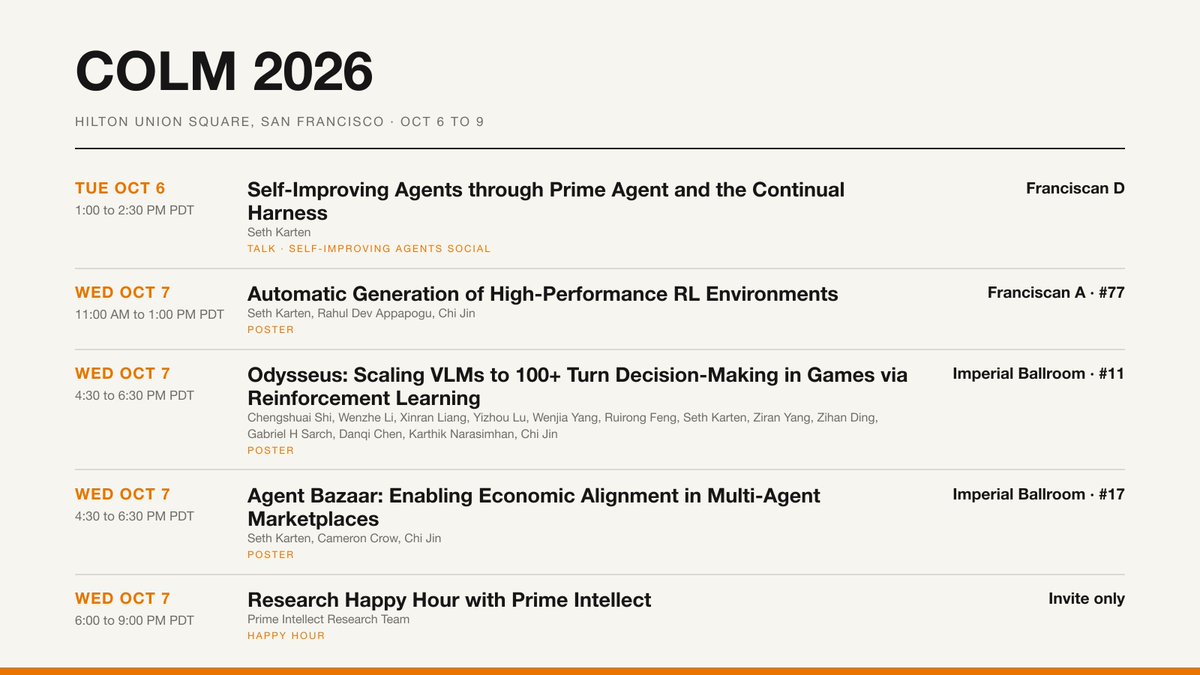
Attending COLM 2026?
Come say hi to talk about self-improving agents and economic multi-agent alignment
Looking forward to chatting with old and new friends!
Wondering how VLMs can be trained to play games using only visual inputs, like Anthropic’s newly released Claude Fable 5?
Check out our recent work, Odysseus: https://t.co/CQW37Av7cm
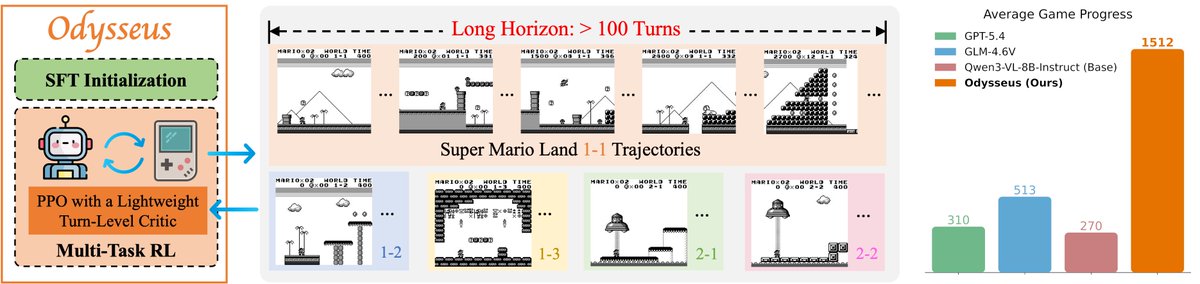
In Odysseus, we train VLMs to play games directly from visual inputs, using Super Mario Land as a testbed, and scale RL to improve their long-horizon decision-making capabilities. Excited to see more exploration in this direction!
Excited to share our recent project Odysseus! We explore training recipes that effectively scale VLM agents for long-horizon tasks. Huge thanks to the incredible team! Check out this thread for details 🧵
🔥 Excited to share our new paper:
🚀 Odysseus: Scaling VLMs to 100+ Turn Decision-Making in Games via Reinforcement Learning
🎮 We study how to make RL stable and effective for training VLM agents in long-horizon, visually grounded environments — using the video game Super Mario Land as a testbed.
📜 Paper: https://t.co/SPgs9dhtBz
🔗 Project page (w/ video demos): https://t.co/zwAclr3W8M
“Student support in the #DataScience community at @UCBerkeley is very powerful,” said student @xinran_liang. Nearly 500 graduates participated in Data Science commencement, along w/ families, faculty and guest speaker @NealStephenson. #CalDataSci22
https://t.co/2Ic9RE11ob