Why do DeepSeek and Kimi use Muon instead of Adam?
🚀 Reasons from a curvature perspective:
1⃣ Under a second-order approx., Muon incurs a much smaller curvature penalty than Adam while maintaining the same first-order decrease.
2⃣ This advantage does not come from a smaller update norm. Instead, it comes from Muon having lower Normalized Directional Sharpness (NDS).
3⃣ Muon’s NDS advantage becomes larger when the training data is more imbalanced.
Paper Link: https://t.co/nGy2FeF538
A thread 🧵
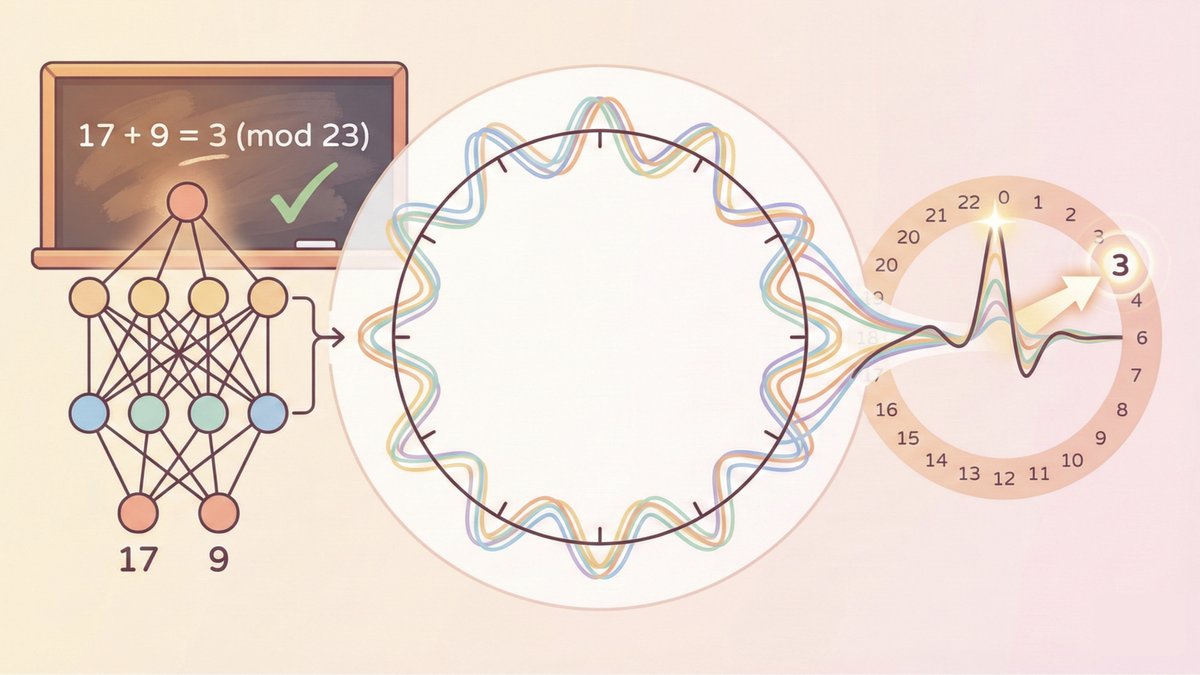
New Paper -- "On the Mechanism and Dynamics of Modular Addition: Fourier Features, Lottery Ticket, and Grokking"
We give a complete mechanistic and dynamic picture of how neural networks learn modular addition f(x,y) = (x+y) mod p. We answer three questions:
(1) What does the trained network compute?
(2) How do Fourier features emerge during training?
(3) Why does grokking happen?
Each answer comes with a mathematical characterization backed by theory and experiments.
Paper: https://t.co/uCU4eNr7tH
Blog: https://t.co/Ok9dDQcYvw
Demo: https://t.co/SX4Q6IsLHB
Code: https://t.co/03Adj6E3Bt
Large Language Models (LLMs) exhibit “slash patterns” in attention maps — a key mechanism behind prefilling acceleration.
We take a first step toward understanding why they emerge.
Main findings:
▶️ Slash patterns are OOD-generalizable
▶️ Queries and keys on these heads are near rank-one and carry little contextual information.
▶️RoPE is the primary source of the slash pattern.
Blog link:
https://t.co/uhE3y7i5xW
A thread 🧵
Imagine a research paradigm where nascent ideas evolve into fully realized papers, complete with empirical data, insightful figures, and robust citations, through an iterative, feedback-driven autonomous system. This vision guides our work.
We introduce **freephdlabor**: a modular multi-agent system designed to automate the entire research lifecycle with unparalleled customizability, fostering continuous scientific inquiry.
Report: https://t.co/DM9kInNjWB
Code: https://t.co/2upMDXpGku
Project: https://t.co/KNdzS7qOt3
Demo: https://t.co/W6db23KBpU
Joint work with @ed_li_tianjin, Junyu Ren, @xintianpan, Cat Yan, @ChuanhaoLi1, and Dirk Bergemann.
Kudos to @ed_li_tianjin for leading this project.