Looking to grow our NLP team in London - Huawei Noah's Ark Lab! We have positions for Research Scientists (permanents) and Engineers (contractors), where they will conduct academic and applied research in NLP and ML. Details below:
https://t.co/dDxE97BgRl
https://t.co/LGN9snl3yb
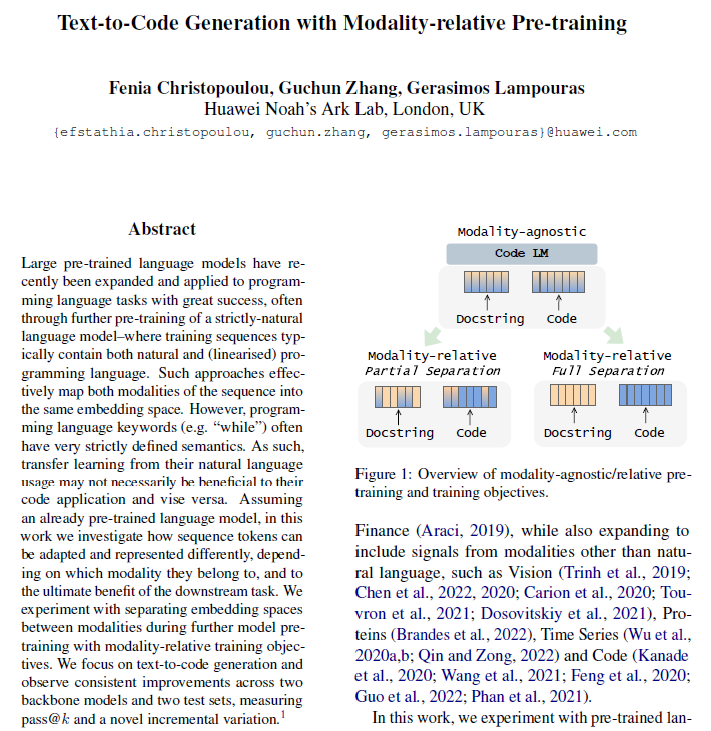
Happy to share our work on "Text2Code Generation with Modality-relative Pre-training" w/ @gcsanity & @glampouras_NLP, accepted at #EACL2024! 🎉
We propose to treat code and natural language as
different modalities.
📜https://t.co/fOYsUARpve
💻coming soon (pending int. review)
Very happy to be co-organizing this workshop and shared task with the fine folks at @TCD and @AdaptCentre! Please help us spread the word of our research track and shared task:
Paper deadline: Dec 18th
ARR commitment deadline: Jan 17th
Shard task deadline: Jan 20th
Proud to announce our paper on "Automatic Unit Test Data Generation and Actor-Critic Reinforcement Learning for Code Synthesis" has been accepted to Findings of #EMNLP2023 .
This is joint work with Matthieu Zimmer, @glampouras_NLP , Derrick Goh Xin Deik, and @iiacobacNLP .
Our approach makes use of Test annotated data to tune a function-level Code Synthesis LM.
Crucially, we find keeping the Critic in sync with the Policy yields better results than pretraining and freezing the Critic.
Use of our augmentation data further improves model performance.
Take two sets P and N of strings, a cost function, and go find a minimal regex that covers all of P but rejects all of N.
Turns out, this is not as easy as it sounds for modern Deep Learning-based approaches like Large (code) Language Models!
#persevere#research
https://t.co/BapzhzR1zh
Google presents the "Unlearning", or, "Oh Snap We Trained on Massive Private Data and now People are Angry"-Challenge.
Still, pretty cool task :)
#nlp#ai#machinelearning etc.
Our wonderful NLP team at Huawei Noah’s Ark Lab is looking for Research Engineers and Research interns.
We are looking for people to work on LLMs for general code and reasoning-related tasks.
Please apply here
https://t.co/MpdYTPEX2O
so, I guess I'm on #Mastodon now too, 'cause looks like #mastodonmigration is en-vogue now.
you can follow @[email protected] if you like... expect even fewer toots than tweets though, I reckon... or expect tweets to go down and toots up... will I cross-post? who knows. okbye
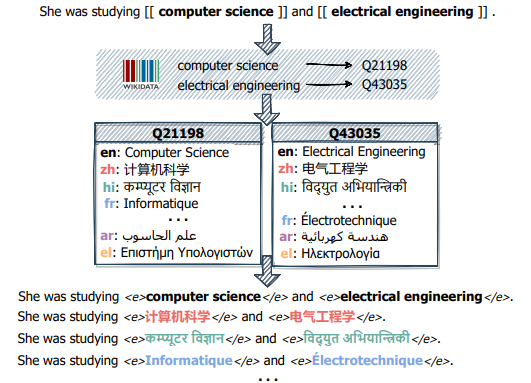
Our EntityCS paper w/ @chenxi_jw + @iiacobacNLP, during her internship at Huawei Noah's Ark, is accepted in Findings of #EMNLP2022! :tada:
📄 https://t.co/zPsuz6tAo5
We augment multilingual LMs with entity knowledge by creating an Entity-centric Code-switching corpus! 🧵⬇️
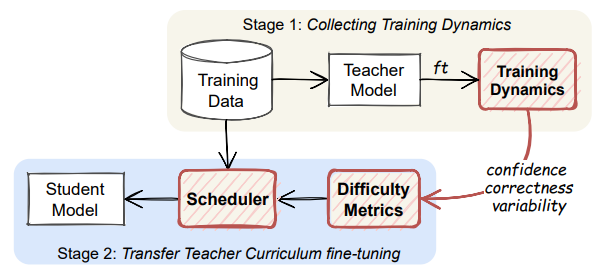
Happy to share our study on "Training Dynamics for Curriculum Learning" on NLU w/ @glampouras_NLP + @iiacobacNLP to appear at #EMNLP2022!
📄https://t.co/yVXI5YAQgs
Can Training Dynamics as difficulty metrics in CL offer better performance of LMs on mono/cross-lingual NLU?🧵⬇️
Presenting our latest work in Huawei Noah’s Ark Lab in collab with Huawei Cloud:
*PanGu-Coder*, a PanGu-α extension, with objectives adapted for text-to-code generation (program synthesis). 317M model variant achieves 17% pass@1 on HumanEval🎉
https://t.co/enlUCm8iTO
👇A thread🧵