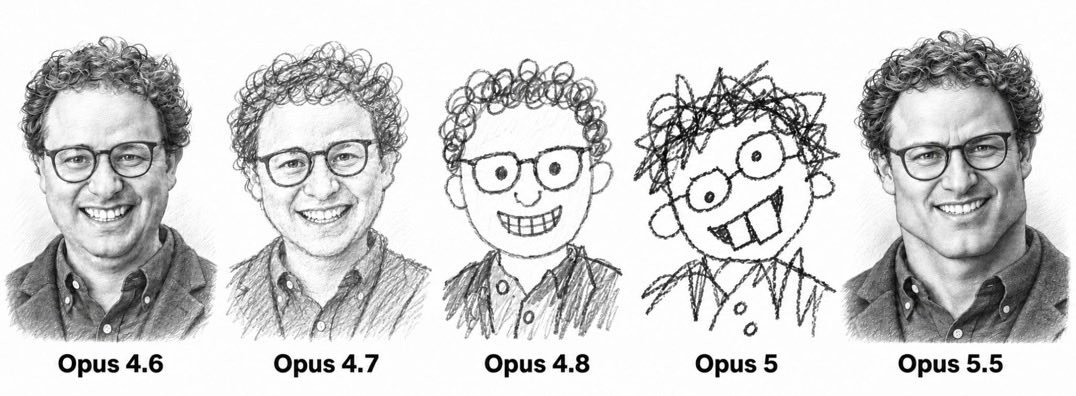
You can now mod Claude Code:
- Change how it behaves
- Customize the UI
- Swap in your own features
Write one with a few lines of TypeScript, or have Claude build it for you. Mods ship inside plugins, so you install them with /plugin in the CLI or desktop app.
A few examples:
Claude Opus 5.5 just took a big drop on NerfBench.
Yesterday it was scoring above launch. Today it's at 94.2%.
GPT 6 Astra: 98.0%
Sonnet 5.5: 100.9%
GPT 6.1 Sol: 106.7%
94.2% is still inside normal variance, so we can't call it a nerf yet.
But we're watching Opus 5.5 very closely.
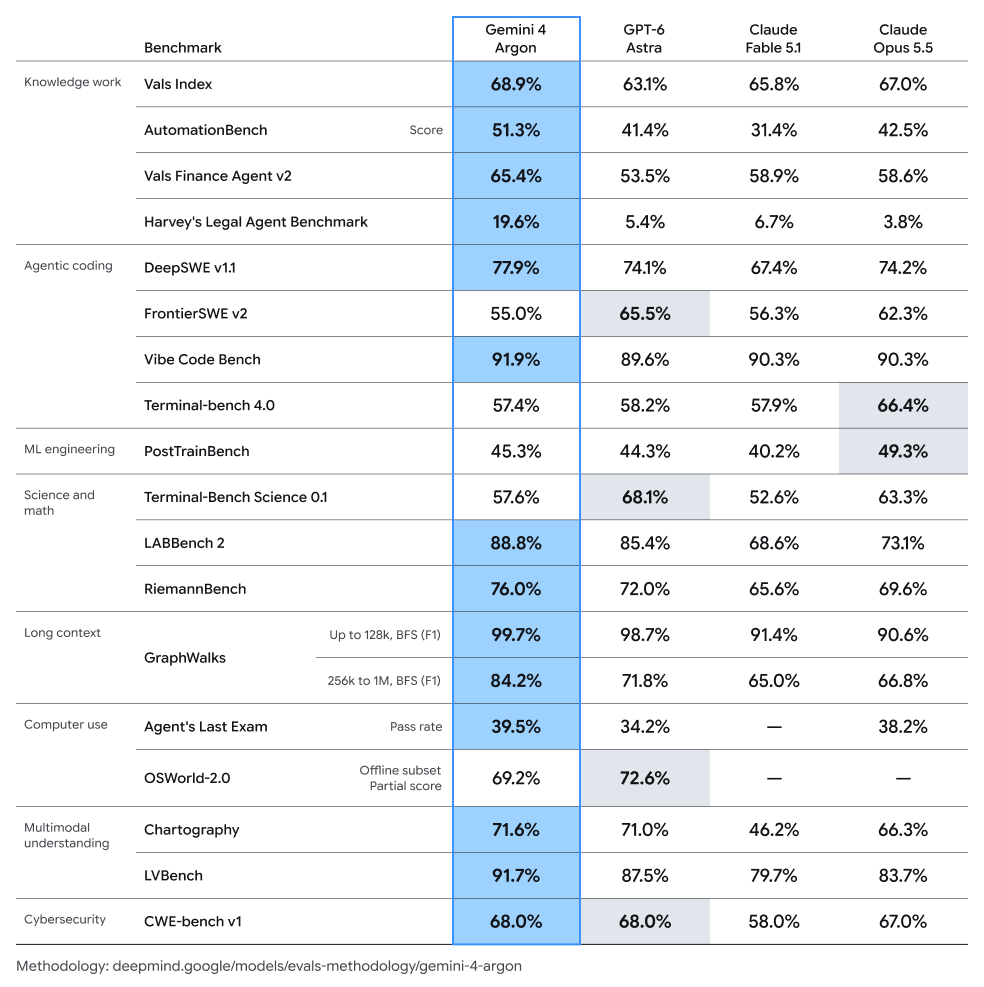
Today we’re introducing Gemini 4 Argon.
It delivers frontier performance in complex workflows across real-world software engineering, knowledge work, and cybersecurity defense with an industry-leading 1M token output limit.
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
Did Anthropic nerf Claude Opus 5.5?
The first NerfBench results are live.
We retested Opus 5.5 and GPT 6 Astra against their own launch scores.
Claude Opus 5.5: 99.2% (-0.8% vs launch)
GPT 6 Astra: 102.8% (+2.8% vs launch)
Verdict: No nerf detected.
Opus 5.5's small dip and GPT 6's small increase is within normal variance.
More models and more frequent retests are coming.
NerfBench only gets better as we collect more data.
Which models should we retest next?
Opus 5.5 is taking the limelight!
But GPT 6 Sol is great jump, doesn’t burn like 5.6 Sol. I would stick to 5.6 Luna because it felt better value. Now I can use Sol nicely.
One shot this iOS app for my diet tracking with barely scratching the usage with medium reasoning.
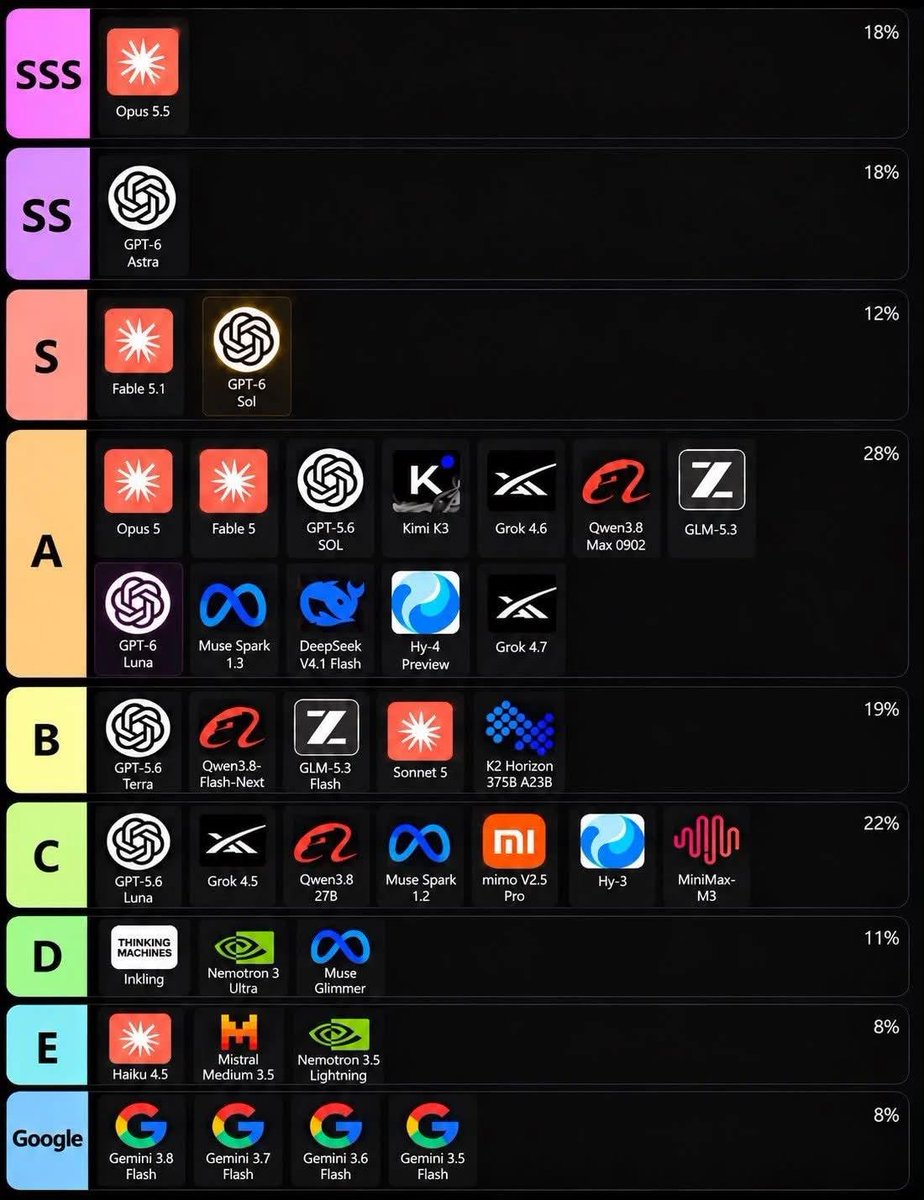
Who’s numbering the models?
What’s with the randomness??
4.8
5
5.5
OpenAI is same
5.5
5.6
6
Is there any logic in it? Or just after drink over the weekend - “let’s go to the next whole number” kinda shit