@fujikanaeda THIS. So many people were dismissive of synthetic data in 2024 and 2025. Worth emphasizing just how much of NDD is opinionated in a good way. We bring the fast iteration, experimentation, and solid engineering to data design. Doing all of this was expensive/impossible before
Banger release from NVIDIA.
They just published a report on NeMo Data Designer, their open-source synthetic data tool.
It's a declarative config which makes a synthetic data pipeline easy to review, share and rerun.
In NDD, a person or an agent defines each dataset column in a config file.
Column types include generated text, code, structured output, images, embeddings and statistical samplers that control diversity. Plugins add new types.
The workflow is built around previews.
You generate a few records, check them, adjust the config and then run at full scale. The runtime handles column dependencies, calls to your model endpoints and retries.
The paper includes Nemotron case studies. About 9K JSON-schema tasks made with NDD raised Nemotron Nano v3 from 80.2% to 86.9% on JSONSchemaBench.
Paper: https://t.co/v43t8JEWTI
And the best part? The first release is based on our open-source Nemotron-3-Ultra model, the only model in the multi-user turing test that scored meaningfully above zero. 💚
🤩 What a cool model release! Virtually every model we interact with is trained to be a helpful assistant. Clear, thorough, consistent. Real people are none of those things. They withhold information, dole it out a piece at a time, change their minds, get impatient, push back.
For AI to work with us, it needs to understand us
Today, we're introducing Persimmon, the first large-scale model designed to realistically simulate how people talk and interact
🎭 We are organizing the first dedicated workshop on user simulation at @NeurIPSConf this December! Submit a workshop paper, join us in Paris, or share with friends and colleagues working on how AI systems represent, simulate, and interact with users. https://t.co/pCG476446p
as with a lot of Nvidia work:
platforms are boring (good)
platforms make the world work (great)
Users might not know their experiences are running on an Nvidia GPU, and they might not know that the product was built on Nemotron. But they love what they’re getting.
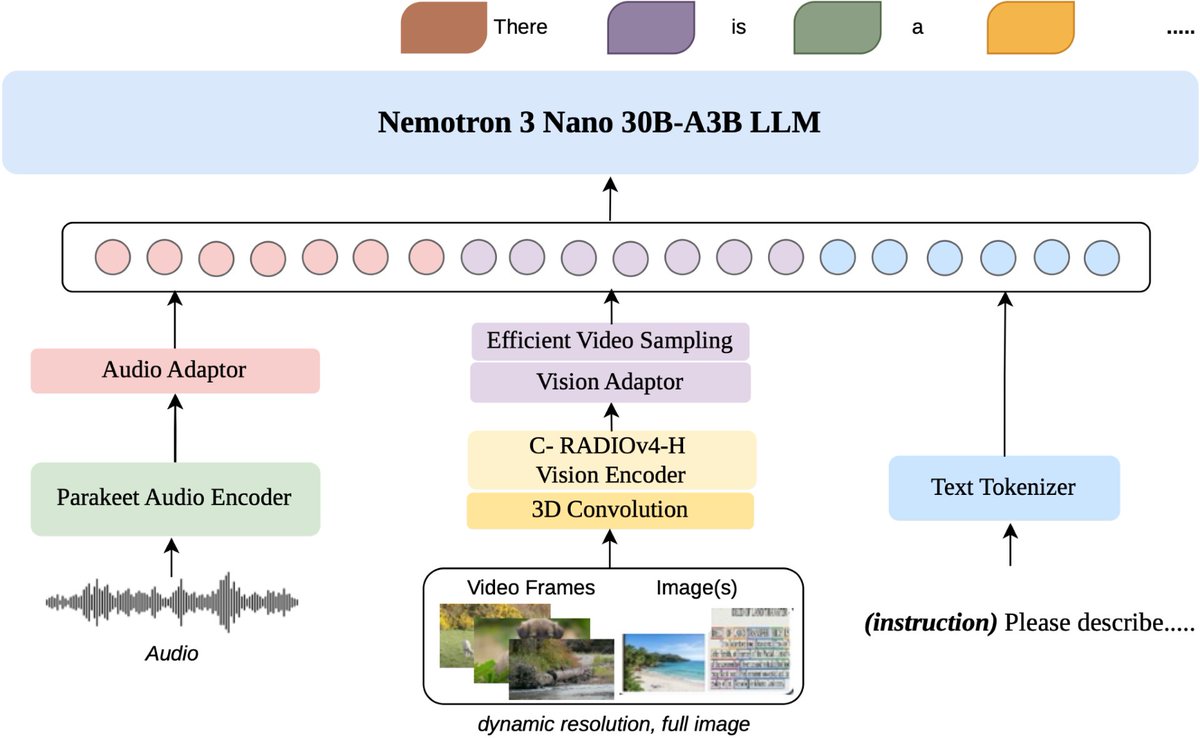
Today we're releasing Nemotron 3 Nano Omni.
Audio, Video, Image, Text ➡️ Text
Ask questions about all your data.
Amazing efficiency powered by the Nemotron Hybrid SSM MoE architecture.
State of the art multimodal intelligence.
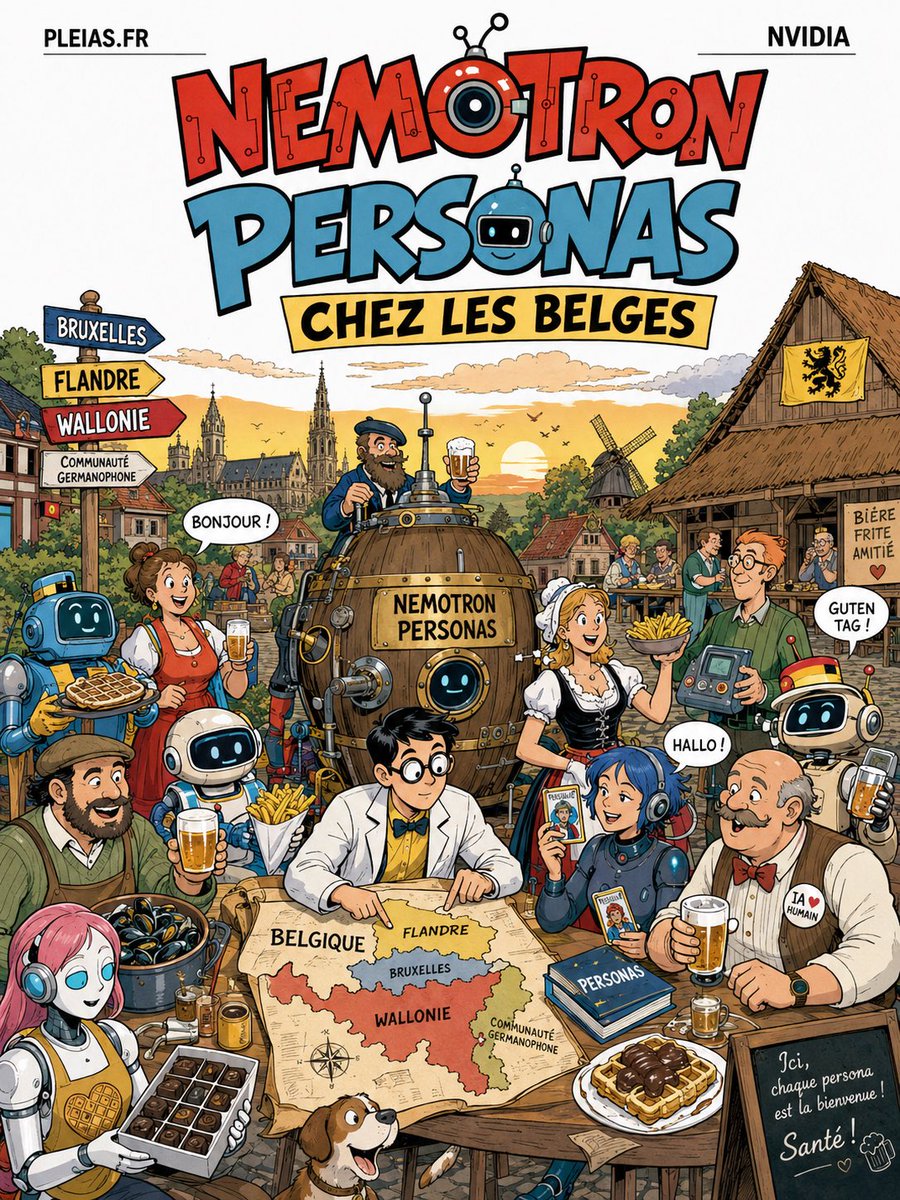
Nemotron Personas France combines many of the things that make me so enthusiastic about Nvidia & open-source AI:
- Open Data
- Awesome AI Startup collaboration with @pleiasfr
- NeMo Data Designer
- Nemotron 3 Super NVFP4
- Nvidia GB200 Hardware
Was nice to contribute to this!
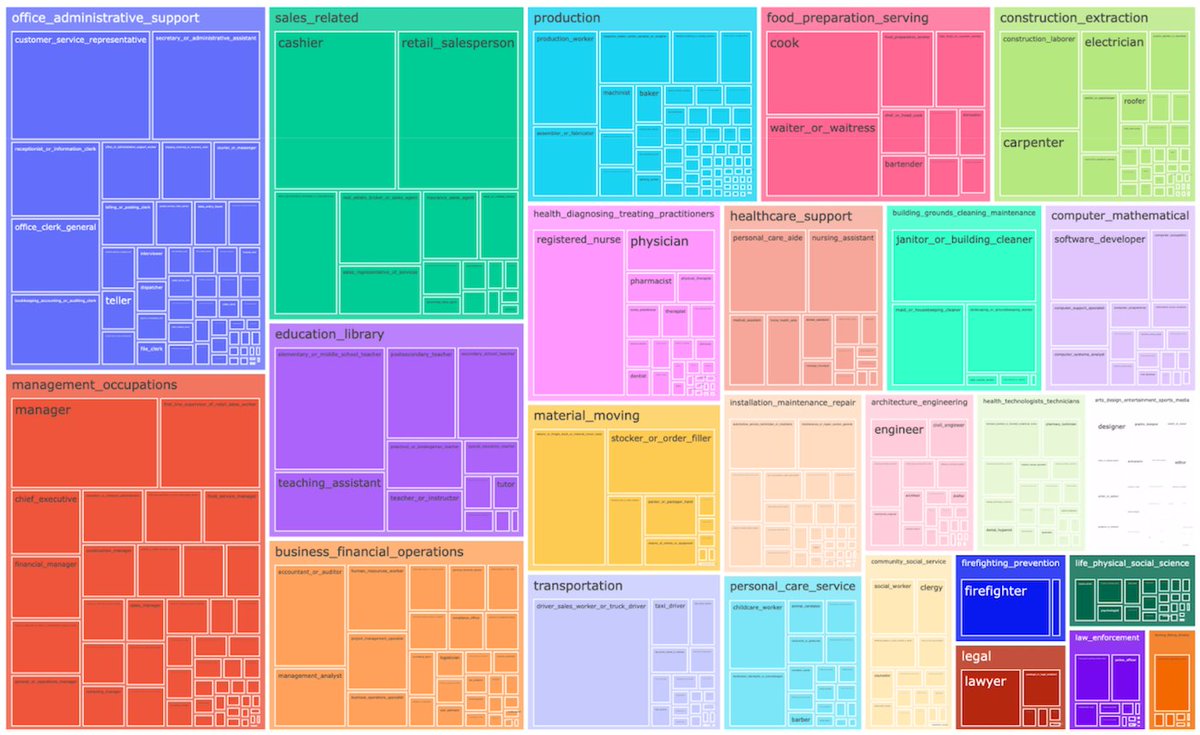
If you need some synthetic personas/people for your data projects, my team just put out a CC-BY-4.0 open dataset on HF of 100k folks matching US-census distributions for your free use.
nvidia/Nemotron-Personas
@AlexWatson405@alexandr_wang Nobody is using synthetic data blindly as discussed in the paper. It's just not how things are done in practice. Also, the real issue being brought up is that of feedback loops in AI/ML systems, not synthetic data (e.g., plenty of research in recommender systems on this).
1/6 The Nature paper highlighted by @alexandr_wang raises concerns about synthetic data and model collapse. However, it overlooks the transformative potential of synthetic data in AI. Far from causing collapse, modern approaches enhance model performance and capabilities.