TLM @CleanlabAI -style idea:
- Given only x and produced y, define a trust score
T(x, y) = S(x, y, alternatives, consistency checks, etc.)
- This is usually not equal to p_internal(y | x)
- It is closer to p(correct | x, y)
or an empirical estimate of downstream reliability
Mathematical interpretation?
Let:
- x = prompt
- y = generated answer
- h = internal hidden state produced by the model
- z = logits for candidate outputs
- p(y | x) = softmax(z)_y
Jev-style idea?
- The model’s own internal decision probability is something like
p_internal(y | x) ≈ g(h)
- where g is a readout from hidden representations.
- this probability reflects the model’s latent decision confidence, not just a generated text like “I am confident.”
testing herdr
https://t.co/ypdqlJZtBD
which is better?
Herdr:
Agent A -> Herdr API -> Agent B
Calyx:
Agent A <--> MCP <--> Agent B
https://t.co/gOZhclgAPu
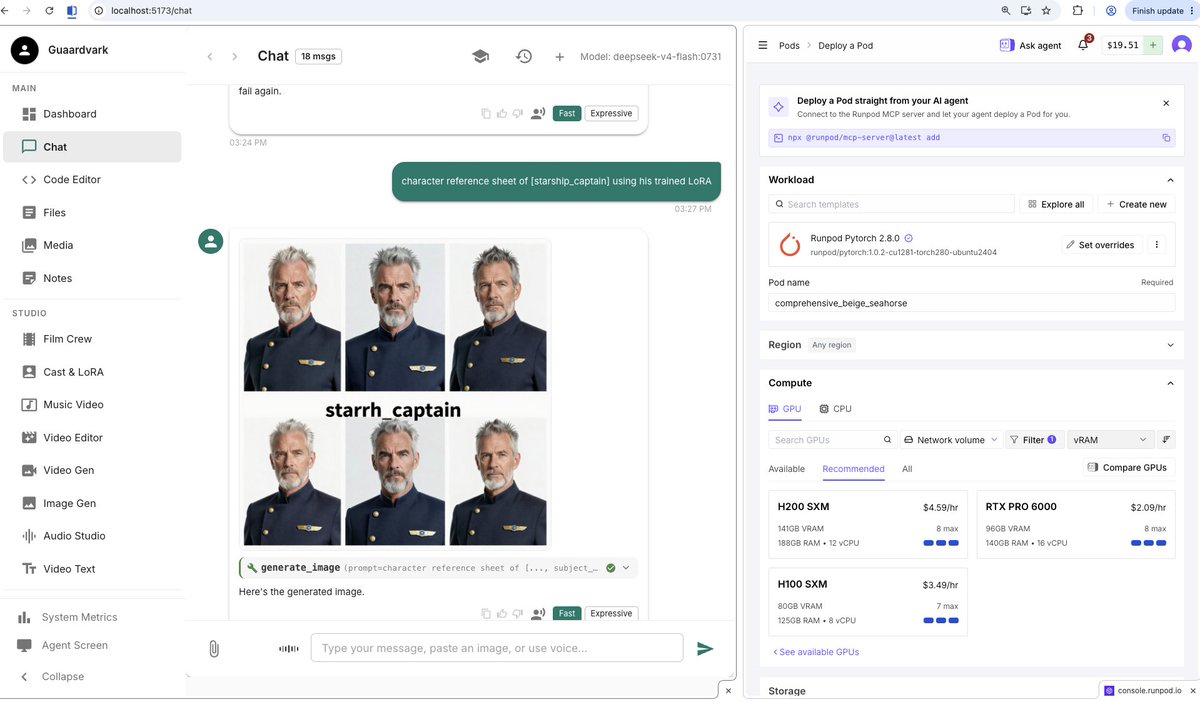
It was a long journey getting Guaardvark to run on my little 48GB MacBook Pro. But every step was worth it the moment a starship captain finally appeared on screen.
@GuaardvarkAI I’ve learned a lot about AI video production from Guaardvark — thanks!
I’m on a Mac M5 Pro 48GB and had to work around CUDA issues. I’ll share my tweaks next month. FYI, the feat/* grouping now I am working on is laid out here: https://t.co/0qNr6KPlfc