We sat down with Shriram Sridharan, Co-founder & CTO at @rox_ai, to hear what it took to add the right web search provider to the GTM agents their customers depend on. The Rox team found with their original provider, customers weren’t getting up-to-date results, and costs were moving up.
That’s when Rox turned to Tavily.
Hear how Rox stood up an infrastructure in two weeks that now tracks millions of accounts and billions of contacts, cutting a sales rep's research time from weeks to running itself overnight: https://t.co/rctdxFGvKw
Real-time web search, agent-payable.
@TavilyAI, the web access layer for the internet of agents, is now on x402.
Paid per query in USDC on @base, no API key or account needed. ↓
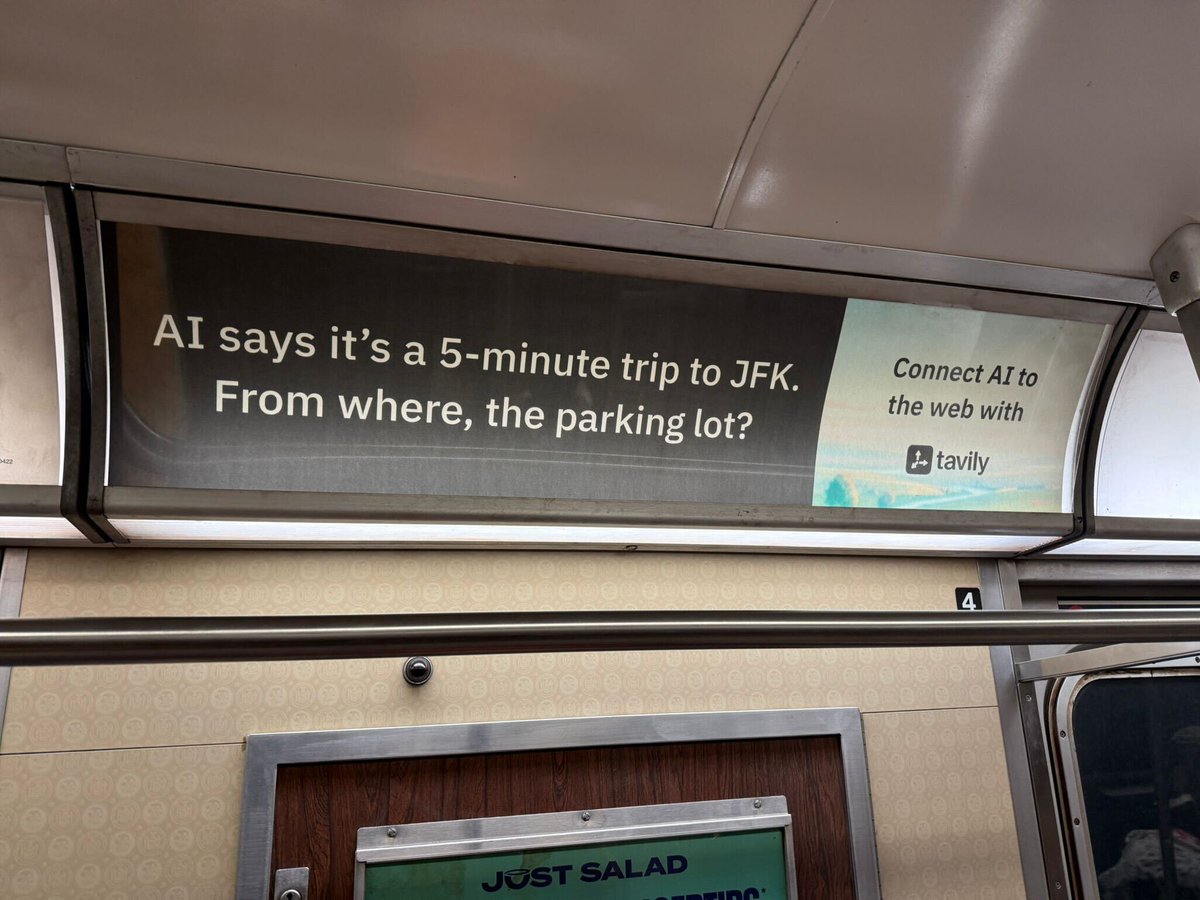
Tavily is live in the NYC subway!
We connect AI to the web so it stops making things up.
If you catch one of these in the wild, tag us. We want to see it. 👀
We’re joining @nebiusai 🚀
What’s changing: Tavily now has the backing of a global AI cloud, meaning faster global latency, higher uptime, and a clear path to SOC2/HIPAA for enterprise agents.
What’s not changing: Tavily remains a standalone, cloud-agnostic API. Same keys, pricing, support, and the same team building the web for AI agents just with a much bigger engine.
More soon.
Tavily Agent Skills are now here ⚡
Your agents can now:
search the live web
pull fresh docs & pages
research markets, competitors and products
cite sources
all without leaving the terminal.
We also shipped tavily-best-practices. A skill that teaches agents how to build production-ready web-connected AI built on real-world lessons from builders like you.
Works wherever you’re building agents:
@claudeai · @cursor_ai · @antigravity
Install now with one line.
They also introduced a "Transfer Matrix" showing which languages boost each other.
This makes a lot of sense for some pairs (Norwegian→Swedish, Arabic→Hebrew). When fine-tuning on a low-resource language, mixing in data from a related "helper" language is a proven performance multiplier.
I stared at this matrix for over 10 minutes because it's fascinating (and I had to search the initials of all the languages I didn't recognize 😂).
2/3
Most of us are not "pre-trainers" (although it's not as difficult as it was 3-5 years ago).
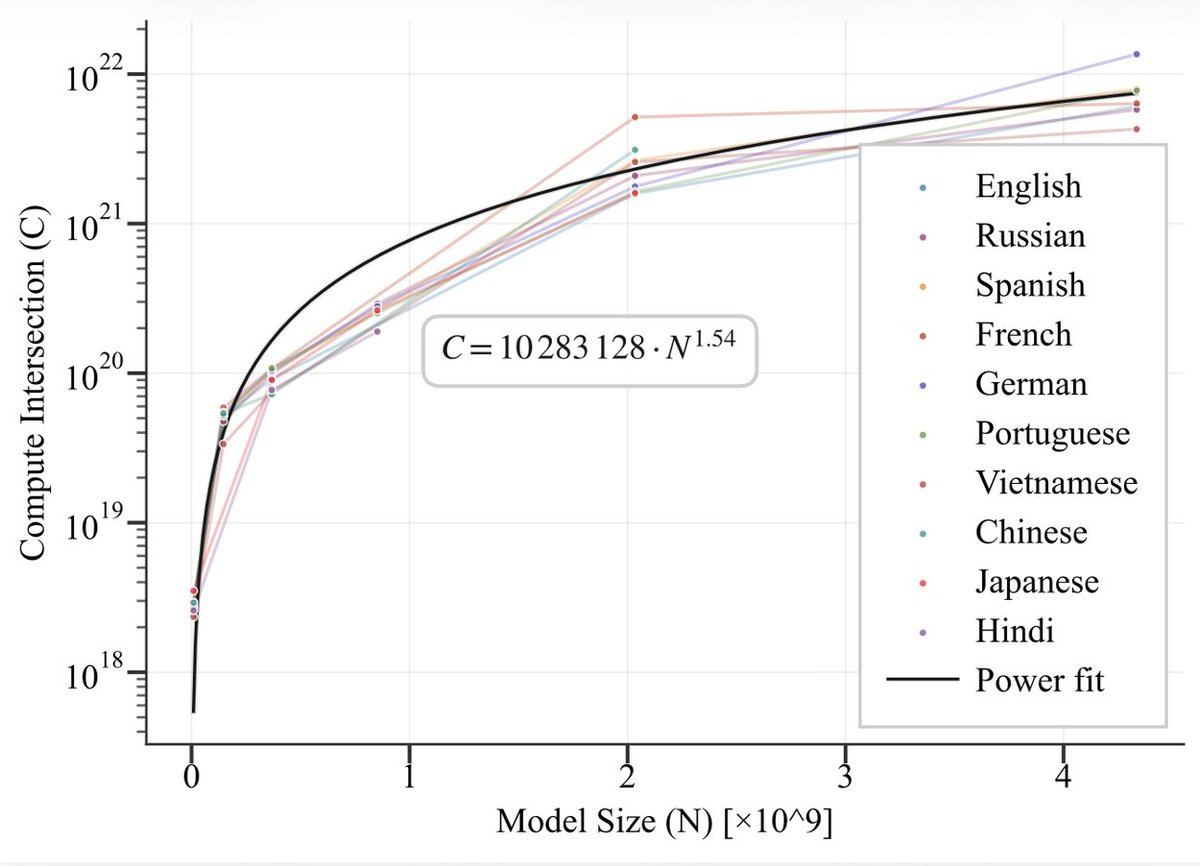
In their setup, finetuning wins early, but pretraining from scratch eventually catches up. The crossover happens after roughly 144B–283B trainable tokens, depending on the language.
If you’re working with anything under ~150B tokens of trainable data, you are better off adapting an existing checkpoint than starting over.
1/3
They quantified the cost of adding languages to LLMs. To double the number of languages without losing performance, you need a ~1.18x larger model and ~1.66x more data.
They call it the "Curse of Multilinguality." Basically, you can't just throw more languages at a fixed-size model and expect it to hold up.
“AI told me. It seemed legit.”
That’s the problem.
Tavily connects AI agents to the web - with real sources, so models don’t have to guess.
What’s the most confident wrong answer you’ve seen from AI?
@tavilyai has just released the world’s fastest search for AI agents, achieving a 180 ms p50 latency. This tutorial shows you how to connect Tavily Fast Search with an @elevenlabs voice agent to enable real-time, voice driven retrieval. https://t.co/GdFgvpzJ8n