Highlighting recent advances in multi-GPU and tensor parallel support in llama.cpp
Over the last few months llama.cpp maintainers and engineers from NVIDIA collaborated to improve the multi-GPU performance in ggml. This resulted in significant performance gains on RTX systems and laid the groundwork for hardware-agnostic tensor parallelism in ggml.
For more information on this and other advancements in the low-level inference engine of llama.cpp, check the technical blog by @NVIDIARTXSpark below
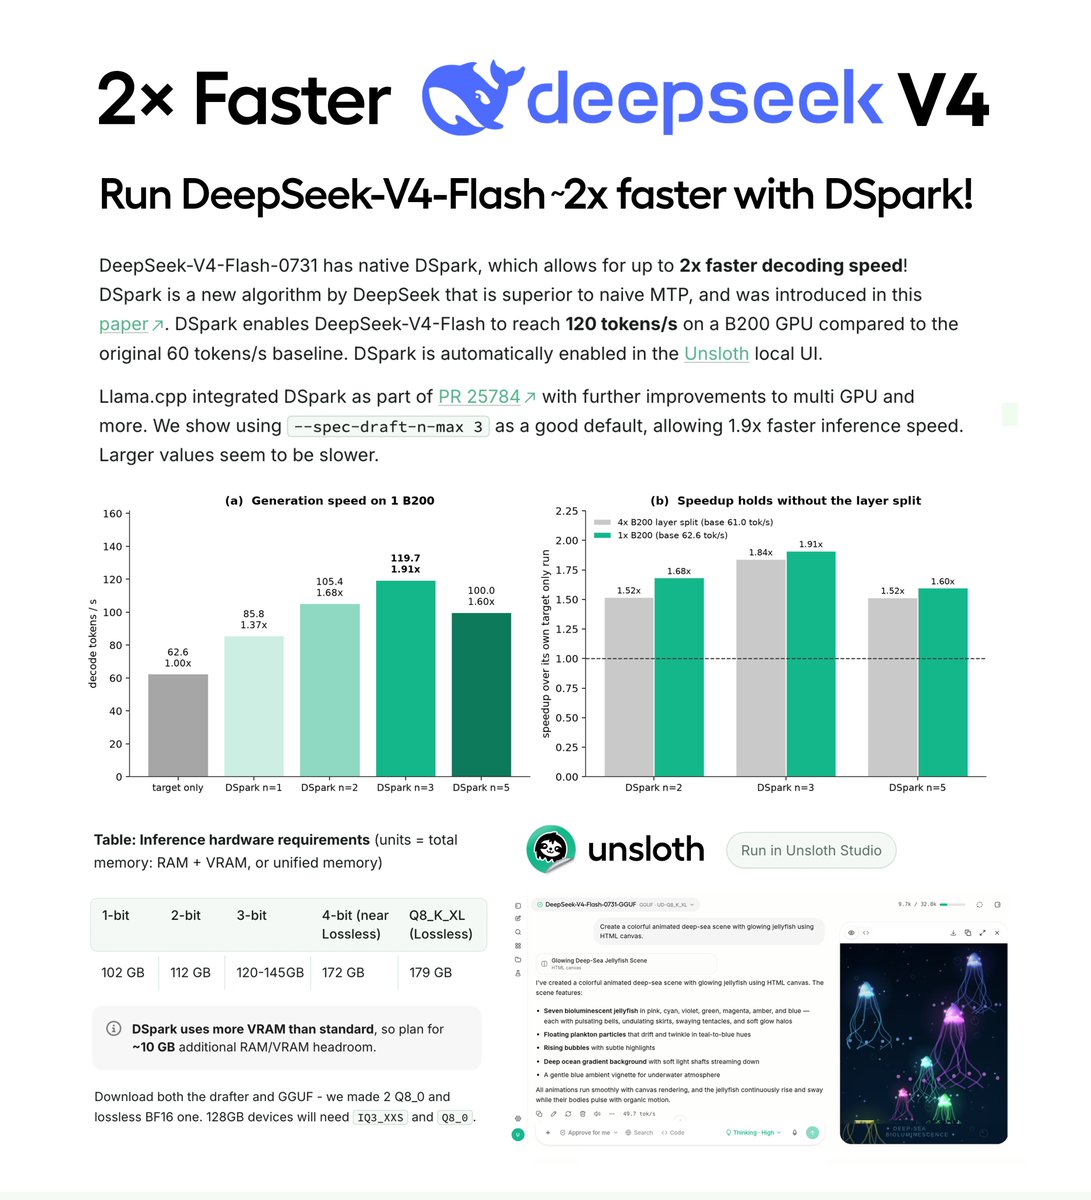
DeepSeek-V4-Flash can now run 2× faster locally with DSpark! ⚡️
DSpark enables V4-Flash-0731 GGUFs to generate ~1.4–2× faster with no accuracy change.
DeepSeek-V4-Flash-0731 can reach at 120 tokens/s.
GGUFs: https://t.co/ac6uOI8mZA
Guide: https://t.co/mCZZkpa95X