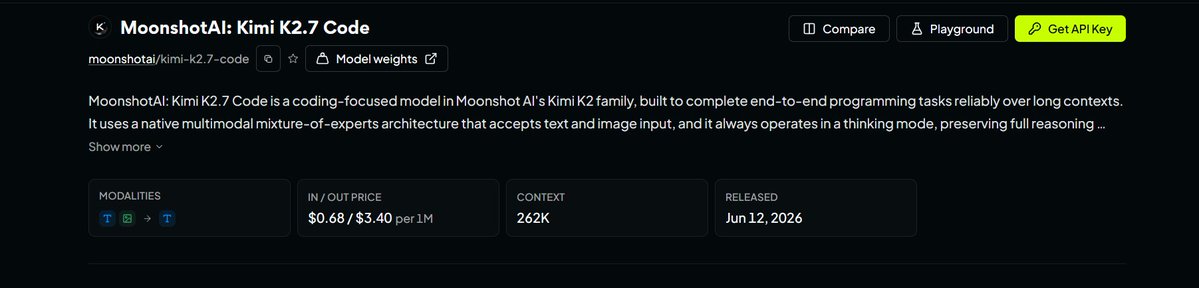
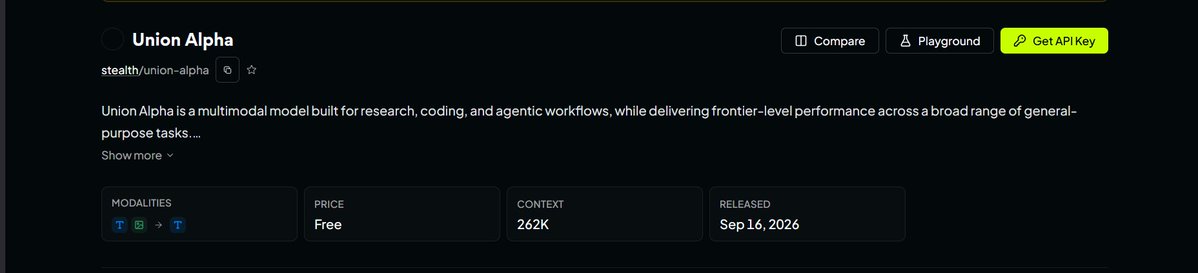
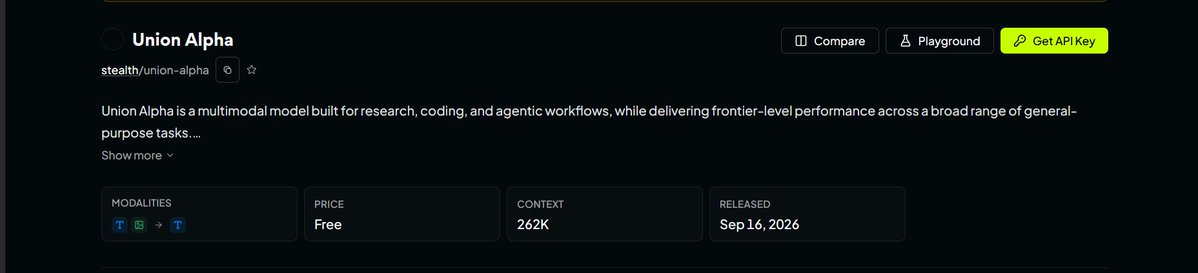
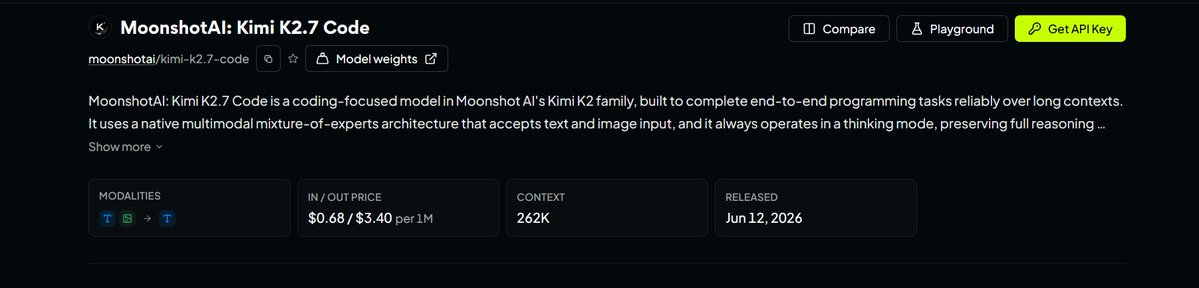
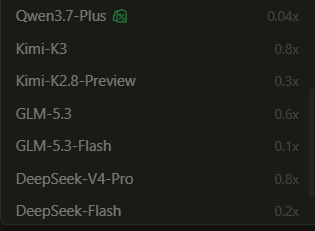
@astropol0 It's a vpn...plus it's kimi k2.8 code you can literally test the same model in qoder and opencode you will see the same result and k2.8 code preview have the same context window and modalities and it's basically same with k2.7 code.
@opencode Let's break the bubble. It's kimi k2.8 code. It's already available on qoder as a preview and reasoning, context window and modalities are the same.
Alright, so, I got bored cuz @thsottiaux wasn't giving reset (PLEASE GIVE A RESET). So, I made GPT 6 Astra make a complete time machine to travel back to historical events. Before anything, I did NOT give it any external asset, NOR I gave it any of the events details it did its own research with a loop and it was ONE SHOT. Everything is inside a single html document and like this is MIND BLOWING. I did NOT expect it to perform this well with such an insane task like it researched each era of the earth and build this. I'm starting to wonder what GPT 7.0 bel would be like or GPT 10.0 can't wait to find out...
I'm working on a bunch of things atp.
I used to love https://t.co/yCuTRxnlzr cuz of their free 100M tokens promo but like it wasn't enough for my work and like their model used to perform pretty decent in tasks during the promo. But ever since I bought their max plan it's just feels like the model they're serving is completely nerfed like they give you decent token volume, but the same task would cost you triple the amount of token cuz the models are highly quantized that they're serving on their api. It's like a sign-up loop https://t.co/pX71c0vXmH gives user's free tokens and all to get users to buy their plan cuz the free tokens models works decently but they hit concurrency limit a lot but once user actually sign up to a plan, they serve them nerfed models that perform really bad in basic tasks.
Yeah, it's going to take "another month" and we're going to see Gemini 3.9 flash and Gemini 4.0 flash. We might see a Gemini 4.5 flash atp. "RSI"...I genuinely think now their employees really started to hallucinate like their models.
"Most ambitious pre-training run yet." ~logan
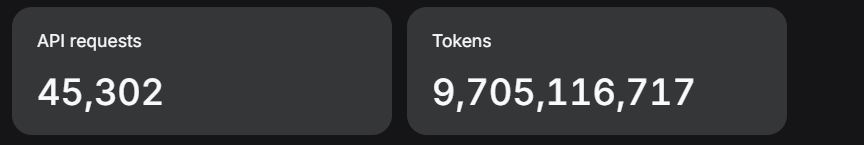
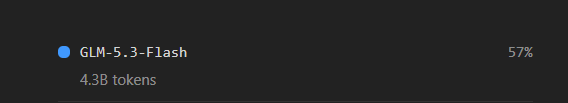
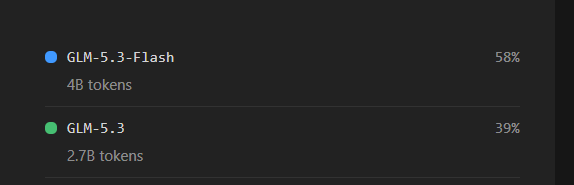
Here's an example GLM 5.3 flash took 400 million tokens and 42+ sub agents with self-critic loop to just fix a page UI and guess what. It still didn't fix the most basic UI bugs. Then, I just used GLM 5.3 flash through openrouter, and it fixed the same bugs in one shot with just 5 subagents and less than 10 million tokens. I think the model that is being served is either highly quantized or not the same GLM 5.3 flash. All it had to do is improve the UI in like 4 pages and it struggled to see where it was lacking despite using computer use like 3 times. I'm not even going to start with some backend bugs that it failed to fix even after consuming 3.4 billion tokens. Like, it wasn't that bad...The only working model is GLM 5.3 but even that struggles sometimes. That's why we need a high-speed variant of it. So, I don't have to wait 4 hours just to fix the same problem. Like atp, I would just fix those issues myself.
I'm not sure if Gemini have reached RSI
but, if they did.
I hope they can at least fix hallucinations rate and prompt handling in Gemini 3.9 flash.
Yeah Gemini 3.9 flash NOT Gemini 4.0 pro we might see a Gemini 4.0 flash atp and then they will say, "give us a month" and we're still waiting for that month🤷.
Currently 3.8 flash is good at frontend. Cuz, it's whole RL is about frontend design but never backend. That's why it lacks in a lot of domains while being close to Astra and fable in benchmaxx. So, I hope they really focus on the backend RL @GoogleDeepMind
here's a combat game that, I built with Gemini and trust me it took it like so many tries to even get here. Even GLM 5.3 flash which is completely nerfed on GLM coding plan performed better than 3.8 flash with only 3 prompts while Gemini took 10+ prompts to even get here and still a lot of issues. So, @GoogleDeepMind don't just focus on frontend RL backend is as important as frontend.
@Henryf1w Yeah 3hrs 24 mins exactly. When doing some real work and again a single agent with a helper thread consumed it. 200 bucks feels like 20 bucks of tokens atp.
Weekend build with GLM 5.3 flash in zcode is basically useless. I'm on a max plan 168 bucks a month and GLM 5.3 flash is nerfed completely on zcode. Model took 3b tokens with multiple subagents and still failed to do the job right. Meanwhile, I tested the model on openrouter and surprisingly it one-shot the exact problem it took 3b tokens for and again in less than 2 bucks. Seriously, they need to fix it the model gets really dumb these days and hallucinates a lot compared to the past and run's in loop. Only GLM 5.3 base model is a bit usable otherwise the GLM 5.3 flash can't even follow a design despite having vision. FIX IT!! and add a fast mode in your app. @zcode_ai