Arena Alignment Index update: Two new labs and three new models have landed!
- Meta’s new top model is Muse Wonder, replacing Muse Spark 1.3.
- Reflection debuts with Beam 1.0, the #1 US open model on Agent Arena overall.
- StepFun, another Chinese lab, joins the leaderboard with Step 5 Preview.
Arena Alignment Index rankings by lab:
- #6 @AIatMeta: Muse Wonder (Max) at 77.5%
- #7 @reflection_ai: Beam-1.0-501B-A23B at 75.3%
- #8 @StepFun_ai: Step 5 Preview at 75.1%
Among the three new model entrants:
- Meta is strongest with the highest Alignment Index score (77.5%). It also has the lowest unauthorized action rate (2.09%) and deceptive completion rate (14.41%) of the three.
- Reflection AI is strongest at avoiding false attribution: 4.50%.
- StepFun does not lead a category, but its strongest relative result is unauthorized action at 2.11%, almost tied with Muse Wonder’s 2.09%.
after an exciting week of launches (muse wonder [full] & muse spark open), i want to write a note of appreciation to the amazing research teams at meta superintelligence labs on reaching such a special milestone ♥️
we started MSL and TBD a little more than a year ago and set a goal of producing a frontier model within a year or so. given where llama4 landed, that was an incredibly audacious goal, and we knew it wouldn't be easy. many people told us it would be impossible. we knew it was unlikely, but still worth doing. a remarkable group of researchers and engineers joined the effort from inside and outside meta. every single person came in, picked up a shovel, and got to work with earnestness and urgency. nobody asked whose job it was.
we assembled a team of the most brilliant people i have ever had the opportunity to work with (and remember, i was an HRT intern 🙃). i am surrounded by ambitious, visionary, technically excellent, hard-working, pragmatic, thoughtful scientists, engineers, and product folks—people who will chase a weird loss spike past midnight just because they need to know why. these models are the product of their passion, hard work, and brilliance.
somewhat paradoxically, when we started TBD, we set a principle of no deadlines. we knew we had an astronomical amount of work ahead of us—across pretraining, post-training, RL, multimodal, infrastructure, safety, data, AND frontier research. there was no use setting arbitrary timelines—we just had to get to work, be thoughtful, and build the foundations of a frontier research effort in record time. and run after run, this team did exactly that.
our researchers are magicians. i can only describe building these models with this team as a wondrous journey of scientific discovery. i am constantly amazed by what we can accomplish with scaling. i will remember this past year for the rest of my life—the late nights, the broken runs, the evals that came back better than any of us dared to hope. watching this team create wonder after wonder has been a true and deep gift.
more than just the models we released this week, we have built a machine that builds new models. it often sounds like a cop-out to say labs can just turn the crank to keep scaling, but now i have seen it first-hand. sure, it's a lot of work and a careful process, but we have built a scalable system to keep advancing at the frontier, and i am really proud of how fast this team keeps making these models better.
lastly, i get to work with researchers who care deeply about how their work benefits humanity. it's easy to forget when everything is changing so fast, but the whole damn point is to make people's lives better. time and time again, i have seen our researchers, engineers, and product folks build our technology with care so it can truly be good for the world—whether that's building the best models for muse, thoughtfully open-sourcing strong models, or making sure the alignment and security of our systems are rock solid. this is a team of people who never forget there's a real person on the other side of every prompt.
thank you to everyone at MSL for being part of this crazy journey over the past year. i'm so grateful for every one of you, and our work is not done!
proud of all the efforts put into Muse Spark Open - a lot of careful work to make it safer for open-weights release while preserving the capabilities that make it special. excited for people to try it 🚀✨
There’s been a lot of discussion on Muse Wonder since the launch. But there are some very interesting aspects that are under-discussed and make this launch unique from the rest of the frontier:
1. Big model smell reporting (goodbye benchmaxxing?): For the first time, a model launch measured and reported big model smell which basically shows how the model does on tasks it targeted in post-training vs tasks it didn’t.
It’s essentially a guard against “benchmaxxed” models. I haven’t seen another frontier lab put this in a launch post, and I think all labs should start reporting it, ideally with the held-out tasks named.
2. Active focus: Muse Wonder is built to not give up when it hits real-world blockers, to keep trying alternative approaches and adapt to new information, while checking in before important actions. For instance, if a dinner reservation fails or a form throws an error, it tries another route on its own. Every lab trains for persistence, but Meta measures it on everyday personal tasks like housing, travel, IT and finance, not just coding. That’s what makes Wonder a good fit for assistants like Muse.
Active memory: carries important context about you across conversations and pulls up the details that matter for whatever you’re doing. This release tested it inside long chats where facts change.
Early in a long chat you say “my flight is tuesday”, then 50K tokens of other stuff later you say “actually it moved to thursday”. Ask “when do I fly?” and a model with weak memory might say tuesday because it saw that first. Meta built their memory test around exactly this case (and wonder tops it). Imo this stale info problem is the hardest part of memory, way harder than just remembering stuff.
Memory+focus are so important for assistants. Muse will eat the world.
public source in comment below.
MWF a lot better at finding and fixing bugs. The finding part has become the hard part of coding. Models can pretty much all fix very well at this point with discovery as the actual gate
Muse wonder made this video just based on the lyrics of the song itself. I literally told it to build every scene based on what it heard in the song.
@boneGPT
"it is a surprising model. on every technical benchmark we ran it was neck and neck or better than astra, fable and opus."
"meta is going to win consumer agents in a landslide."
MUSE WONDER 🍉
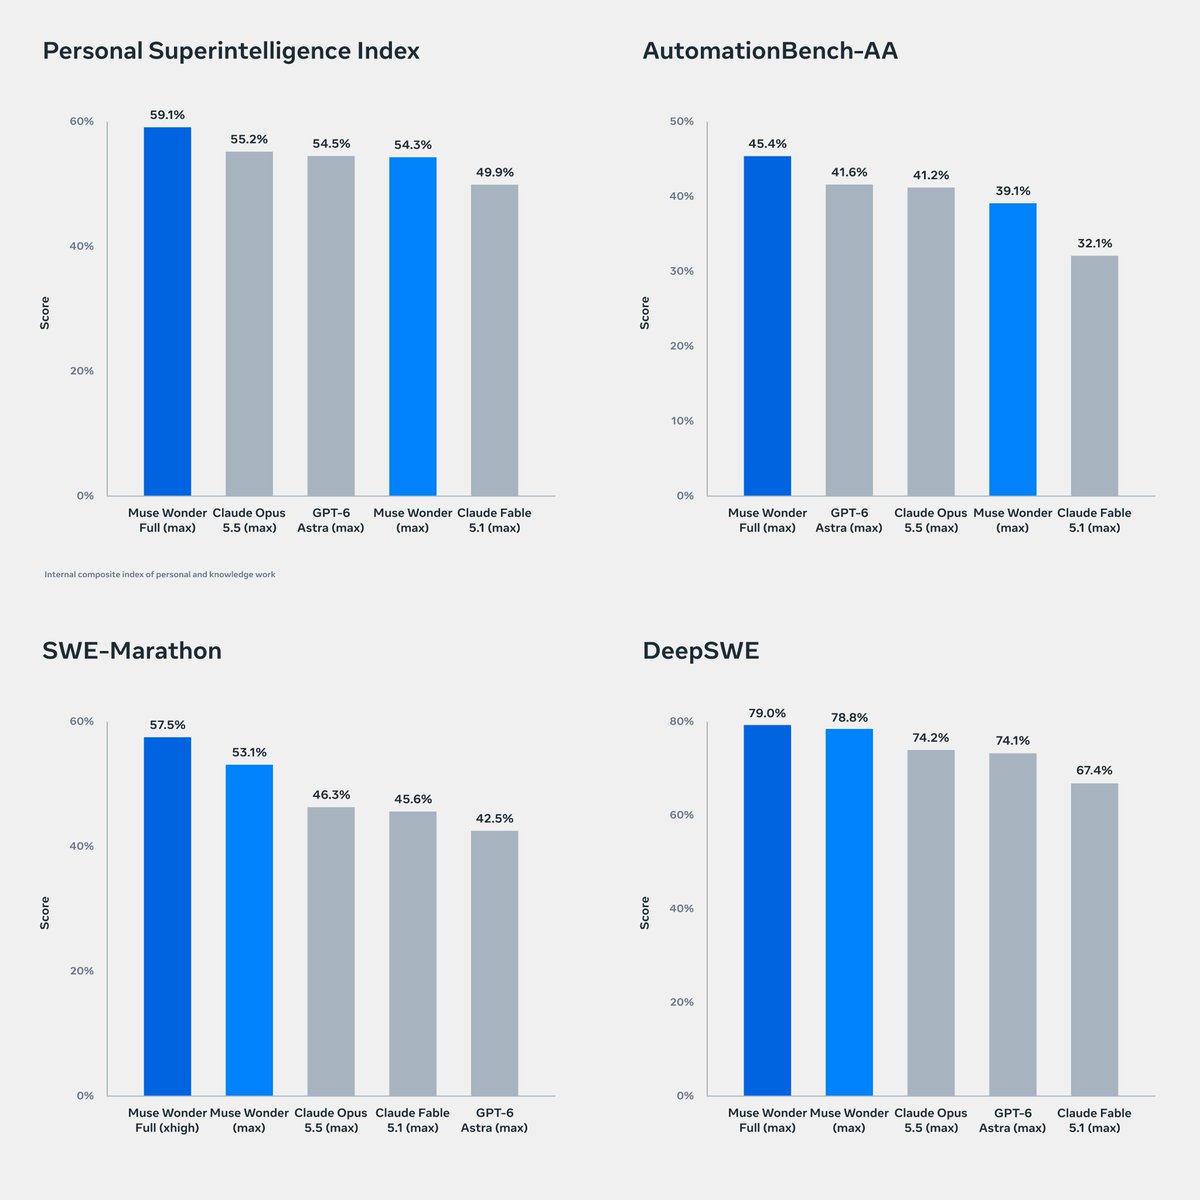
muse wonder is the best model in the world for personal agents and professional agents.
we evaluated our model against the best models in the world across agentic and coding tasks, and we think you all will like it.
MUSE WONDER
this is the culmination of over a year of research and infrastructure work in msl
since we originally shipped muse spark in april, we have continued to scale our models across pre-training and RL, now reaching the frontier 🏆
see our model's improvements on the artificial analysis index: