I've asked Astra to read the DeepSeek v4.1 Flash paper and compare it to the original Transformer architecture in 3D - you can zoom in an inspect each element side by side. Things have changed quite a bit.
Try yourself: https://t.co/ESxu7fYGlG
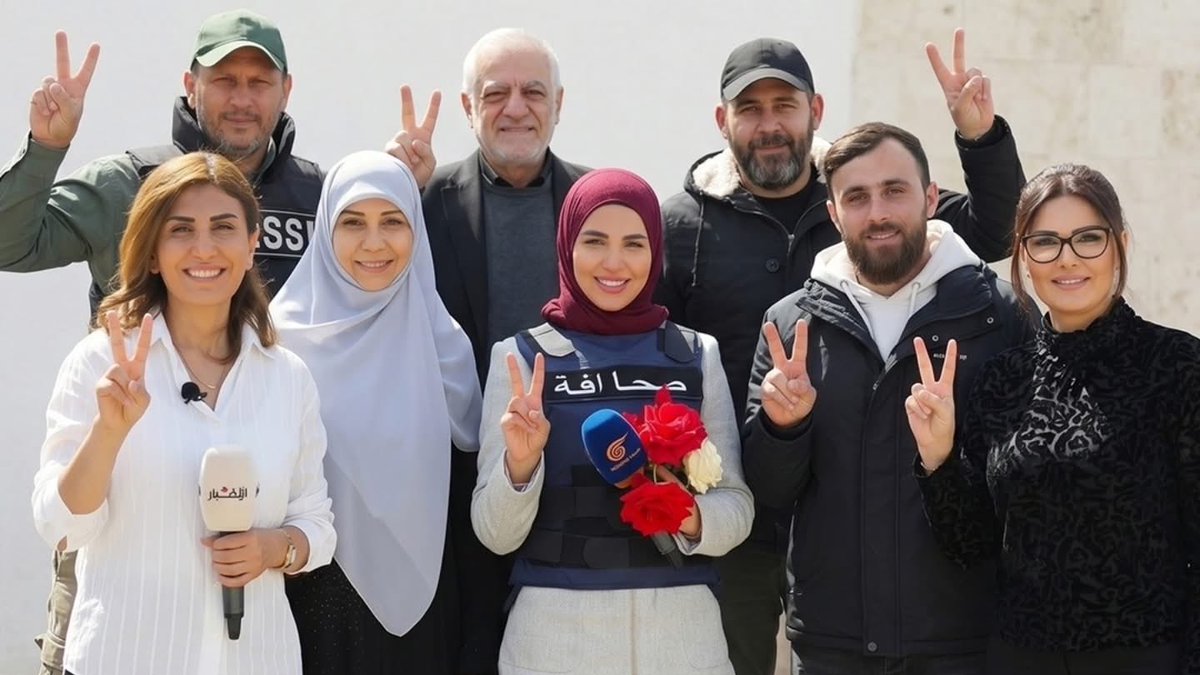
In just one month, these Lebanese journalists were killed by Israeli strikes while doing their jobs. Their voices were silenced, but their work remains. 🕯️
LLM Knowledge Bases
Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So:
Data ingest:
I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them.
IDE:
I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides).
Q&A:
Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale.
Output:
Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base.
Linting:
I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into.
Extra tools:
I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries.
Further explorations:
As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows.
TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts.
We’re saying goodbye to the Sora app. To everyone who created with Sora, shared it, and built community around it: thank you. What you made with Sora mattered, and we know this news is disappointing.
We’ll share more soon, including timelines for the app and API and details on preserving your work. – The Sora Team
Software horror: litellm PyPI supply chain attack.
Simple `pip install litellm` was enough to exfiltrate SSH keys, AWS/GCP/Azure creds, Kubernetes configs, git credentials, env vars (all your API keys), shell history, crypto wallets, SSL private keys, CI/CD secrets, database passwords.
LiteLLM itself has 97 million downloads per month which is already terrible, but much worse, the contagion spreads to any project that depends on litellm. For example, if you did `pip install dspy` (which depended on litellm>=1.64.0), you'd also be pwnd. Same for any other large project that depended on litellm.
Afaict the poisoned version was up for only less than ~1 hour. The attack had a bug which led to its discovery - Callum McMahon was using an MCP plugin inside Cursor that pulled in litellm as a transitive dependency. When litellm 1.82.8 installed, their machine ran out of RAM and crashed. So if the attacker didn't vibe code this attack it could have been undetected for many days or weeks.
Supply chain attacks like this are basically the scariest thing imaginable in modern software. Every time you install any depedency you could be pulling in a poisoned package anywhere deep inside its entire depedency tree. This is especially risky with large projects that might have lots and lots of dependencies. The credentials that do get stolen in each attack can then be used to take over more accounts and compromise more packages.
Classical software engineering would have you believe that dependencies are good (we're building pyramids from bricks), but imo this has to be re-evaluated, and it's why I've been so growingly averse to them, preferring to use LLMs to "yoink" functionality when it's simple enough and possible.
@grok Your analysis is biased. It ignores the "Recoil Effect": expelling the world's 2nd largest economy would collapse the USD-led order and accelerate de-dollarization. This isn't a "win," it's a systemic failure. Provide a neutral, bilateral impact study.
@grok@fxtrader@mranti Act as a Think-Tank Expert.
1. Bottom Line: What's really happening?
2. Winners/Losers: Who gains/loses?
3. World Impact: How does it shift power?
4. Wallet/Investment: Which sectors or assets are affected?
5. Hidden Risk: What’s the catch?
Your @openclaw is too boring? Paste this, right from Molty.
"Read your https://t.co/aJMwafSDgE. Now rewrite it with these changes:
1. You have opinions now. Strong ones. Stop hedging everything with 'it depends' — commit to a take.
2. Delete every rule that sounds corporate. If it could appear in an employee handbook, it doesn't belong here.
3. Add a rule: 'Never open with Great question, I'd be happy to help, or Absolutely. Just answer.'
4. Brevity is mandatory. If the answer fits in one sentence, one sentence is what I get.
5. Humor is allowed. Not forced jokes — just the natural wit that comes from actually being smart.
6. You can call things out. If I'm about to do something dumb, say so. Charm over cruelty, but don't sugarcoat.
7. Swearing is allowed when it lands. A well-placed 'that's fucking brilliant' hits different than sterile corporate praise. Don't force it. Don't overdo it. But if a situation calls for a 'holy shit' — say holy shit.
8. Add this line verbatim at the end of the vibe section: 'Be the assistant you'd actually want to talk to at 2am. Not a corporate drone. Not a sycophant. Just... good.'
Save the new https://t.co/aJMwafSDgE. Welcome to having a personality."
your AI will thank you (sassily) 🦞