@pretendsmarts@_akhaliq Thank you! We're actually on it. As generative models come with certain inherent risks, we are improving the model's performance and conducting safety audits. We're aiming to have a demo ready for everyone to try out in the next 2-3 months. Really appreciate your interest!😆
Make Pixels Dance: High-Dynamic Video Generation
paper page: https://t.co/TOhsK6ryIp
Creating high-dynamic videos such as motion-rich actions and sophisticated visual effects poses a significant challenge in the field of artificial intelligence. Unfortunately, current state-of-the-art video generation methods, primarily focusing on text-to-video generation, tend to produce video clips with minimal motions despite maintaining high fidelity. We argue that relying solely on text instructions is insufficient and suboptimal for video generation. In this paper, we introduce PixelDance, a novel approach based on diffusion models that incorporates image instructions for both the first and last frames in conjunction with text instructions for video generation. Comprehensive experimental results demonstrate that PixelDance trained with public data exhibits significantly better proficiency in synthesizing videos with complex scenes and intricate motions, setting a new standard for video generation.
Happy to share that VLUE, a new benchmark for evaluating the "true" generalization ability (on non-COCO images) of Vision-Language Models has been accepted by #ICML2022.
Paper📜: https://t.co/68qMihE6q5
Code/Data🧑💻: https://t.co/c8QJMm54BM
Website 🔍: https://t.co/sOKgp9HuqD
We find that by combining prefix language modeling and prefix image modeling, we can effectively train a multi-modal foundation model (we named as DaVinci🤣) capable of variety of tasks across modalities (language / vision / vision+language) and types (understanding / generation)
X-VLM has already been deployed on several products of #ByteDance. The code and pre-trained checkpoints are all available. Feel free to try what X-VLM can do!
Paper: https://t.co/yduvcsG992
Code: https://t.co/Pcu7VTGAYQ
Happy to share that X-VLM has been accepted by #ICML2022!
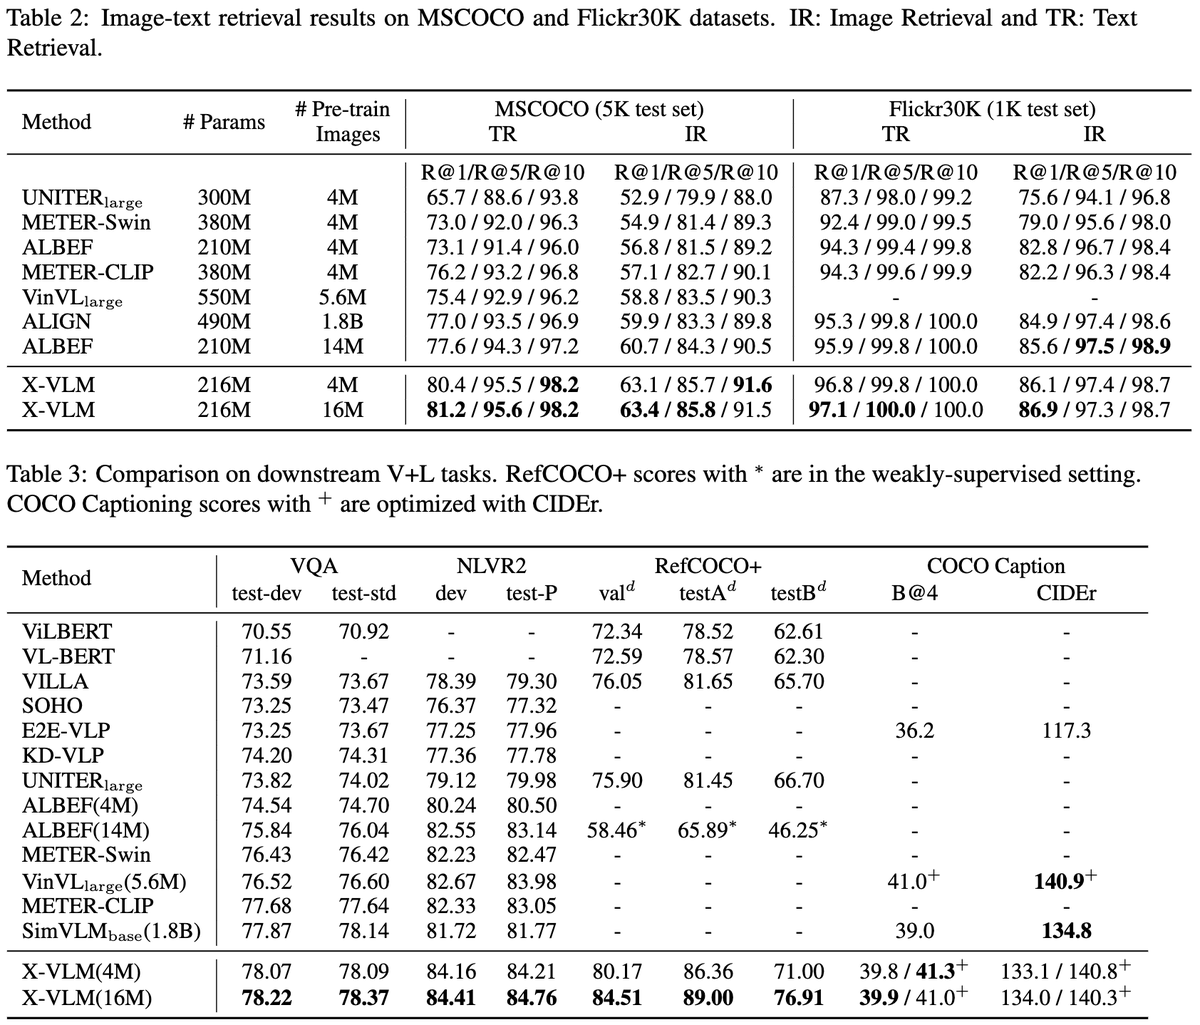
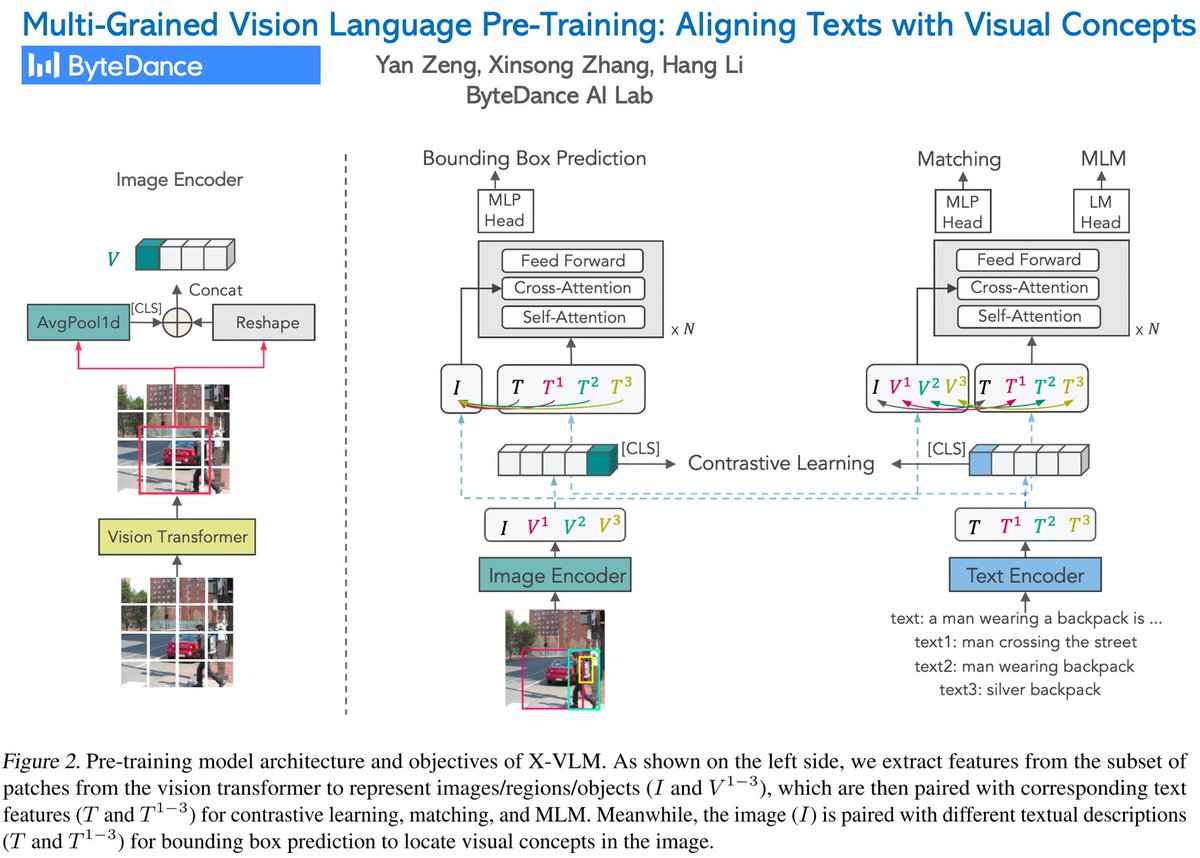
We propose to perform multi-grained vision language pre-training for the first time. X-VLM of moderate model size (216M parameters) outperforms many models which could be of larger size and/or utilize more data.