🚀 Building AI models? The hardest part isn’t the model… it’s the data.
That’s why we at @ServiceNow have built SyGra → an open-source, low-code/no-code, graph-oriented framework to plan, generate, and quality-check synthetic data for training & evals.
🧵👇
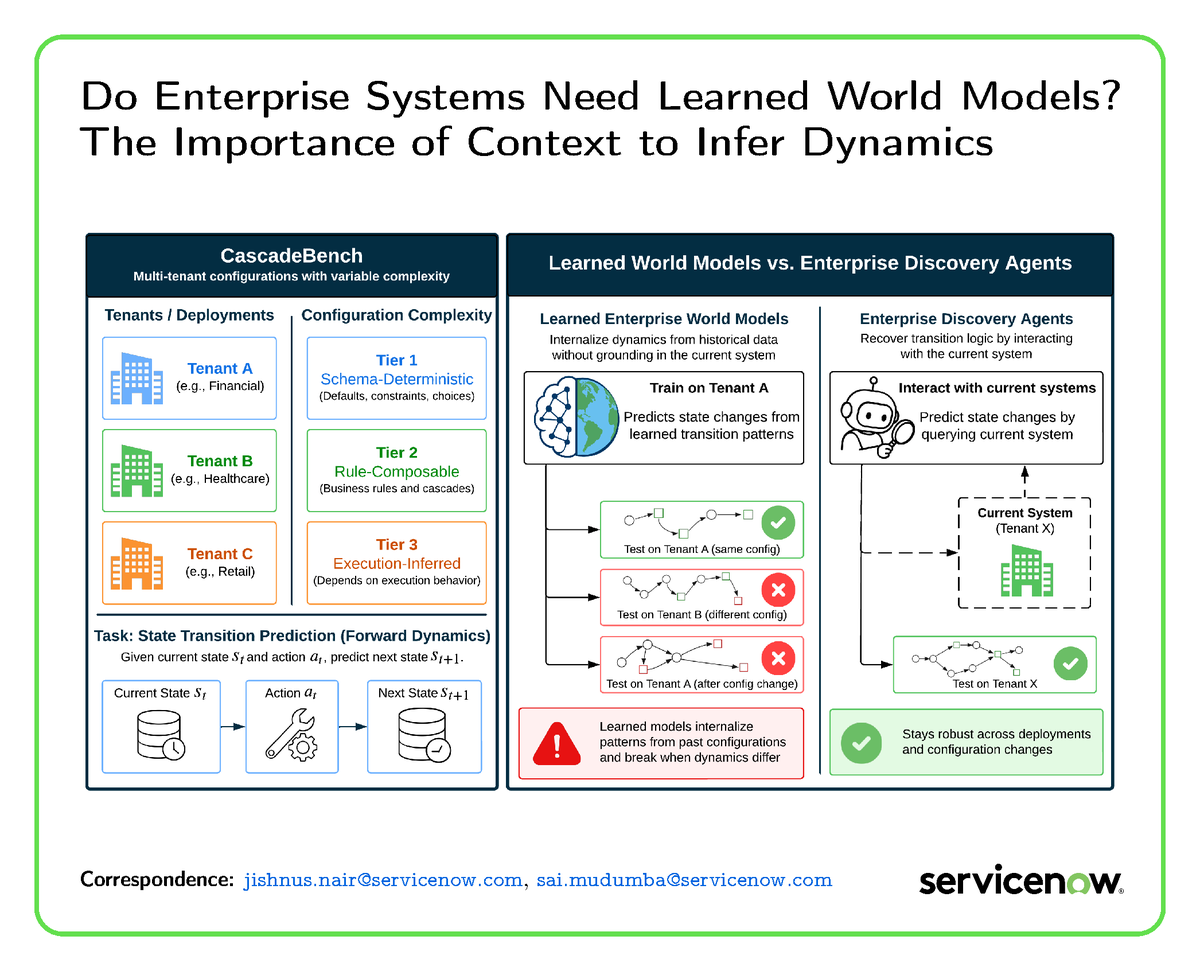
🥳 Excited to share that this work is now accepted at NeurIPS 2026 main conference and CascadeBench is now open source!
We gave a frontier model every business rule in an enterprise system, perfectly retrieved. It still couldn't predict what a single action would do. Fetching the rules isn't the bottleneck; composing them is.
📦 𝗖𝗮𝘀𝗰𝗮𝗱𝗲𝗕𝗲𝗻𝗰𝗵 is out, with every field change attributed to the rule that caused it:
🤗 https://t.co/2oBZ4FGa0A
📄 https://t.co/PDyDH4Y0i0
Congrats to @TheJishnuNair@patricebechard@rmahesh__@zephyrzilla@shiva_malay, Sravan, Aakash, @johanobandoc@sagardavasam , @chrisjpal@siris_krishna@ServiceNowRSRCH@Mila_Quebec
See you at NeurIPS!
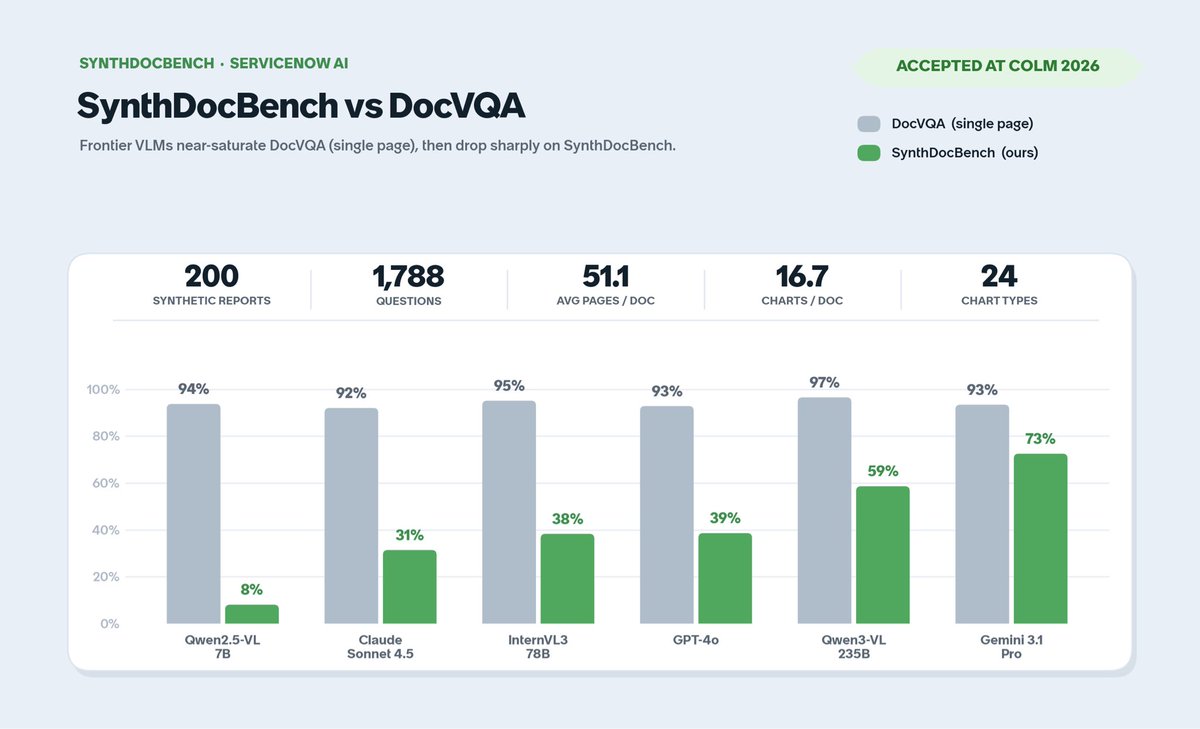
We are excited to release 📊 SynthDocBench (🎉 Accepted at COLM 2026)!
Frontier VLMs score 95%+ on DocVQA. So why do they fall apart on long documents?
SynthDocBench isolates the reason—the bottleneck isn't reasoning, it's perception 🧵.
#COLM2026
Announcing EnterpriseOps-Gym-AA, our independent leaderboard for ServiceNow's EnterpriseOps-Gym, testing whether AI agents can run real enterprise operations while following business rules and policy
We've partnered with @ServiceNow to launch EnterpriseOps-Gym-AA on Artificial Analysis, adapting the original EnterpriseOps-Gym benchmark (https://t.co/zIbEYazuFx) to run on our Stirrup agent harness. The benchmark drops agents into live enterprise systems and asks them to complete multi-step, stateful work across 8 business domains, with models graded on the final state of the underlying databases rather than the steps taken.
As we launch the eval, @AnthropicAI's Claude Fable 5 (max) leads at 51%, ahead of @GoogleDeepMind's Gemini 3.5 Flash (high, 50%), @OpenAI's GPT-5.5 (xhigh, 47%), with @Zai_org's GLM-5.2 (max, 43%) as the highest-scoring open weights model.
Key elements of EnterpriseOps-Gym-AA:
➤ Stateful, multi-step enterprise work: Agents operate live enterprise systems where actions are often irreversible. A wrong write can corrupt the environment the way it would in production, so agents cannot brute-force their way to a solution.
➤ Live tool use across 8 domains: Models act through live Model Context Protocol (MCP) servers over 164 database tables and 512 tools, spanning core business systems (Customer Service, HR, IT Service Management), collaboration tools (Email, Calendar, Teams, Drive), and cross-domain Hybrid tasks.
➤ Outcome-based SQL verification: Each task is graded by executable SQL checks on the final environment state, testing goal completion, state integrity, policy compliance, and unintended side effects. This rewards outcomes over rigid action sequences and allows alternative valid solution paths.
Key results:
➤ The frontier just clears 50%: Claude Fable 5 (max) leads at 51%, the only model clearly above half, with Gemini 3.5 Flash (high) close behind at 50% - a fast, low-cost Flash-tier model edging out larger frontier systems. Even the strongest models complete only about half of the 1,117 oracle-mode tasks.
➤ Models must pass all verification checks to succeed at a task: Models must satisfy all verification checks to succeed at a task, because a single missed constraint often means failure in the real world. We see that models satisfy most individual verifier checks (79% for the leader, Claude Fable 5) but complete far fewer whole tasks (51%).
➤ Open weights are within ~8 points: GLM-5.2 (max, 43%) is the strongest open weights model, about eight points behind the overall leader, with DeepSeek V4 Pro (max, 40%) and Kimi K2.7 (40%) close behind.
We would like to thank @ServiceNowRSRCH , @Mila_Quebec, @UMontreal and the benchmark authors for their excellent work building EnterpriseOps-Gym, and appreciate their collaboration in launching it on Artificial Analysis!
🚀 Grok Voice Think Fast 1.0 (@xAI) lands on the Pareto frontier on EVA-Bench — no system in the eval beats it on accuracy without sacrificing experience, or vice versa.
📊 Leaderboard: https://t.co/v4QJZwzUsd
@elonmusk#VoiceAgents#ServiceNowResearch#EVABench#GrokVoice#xAI
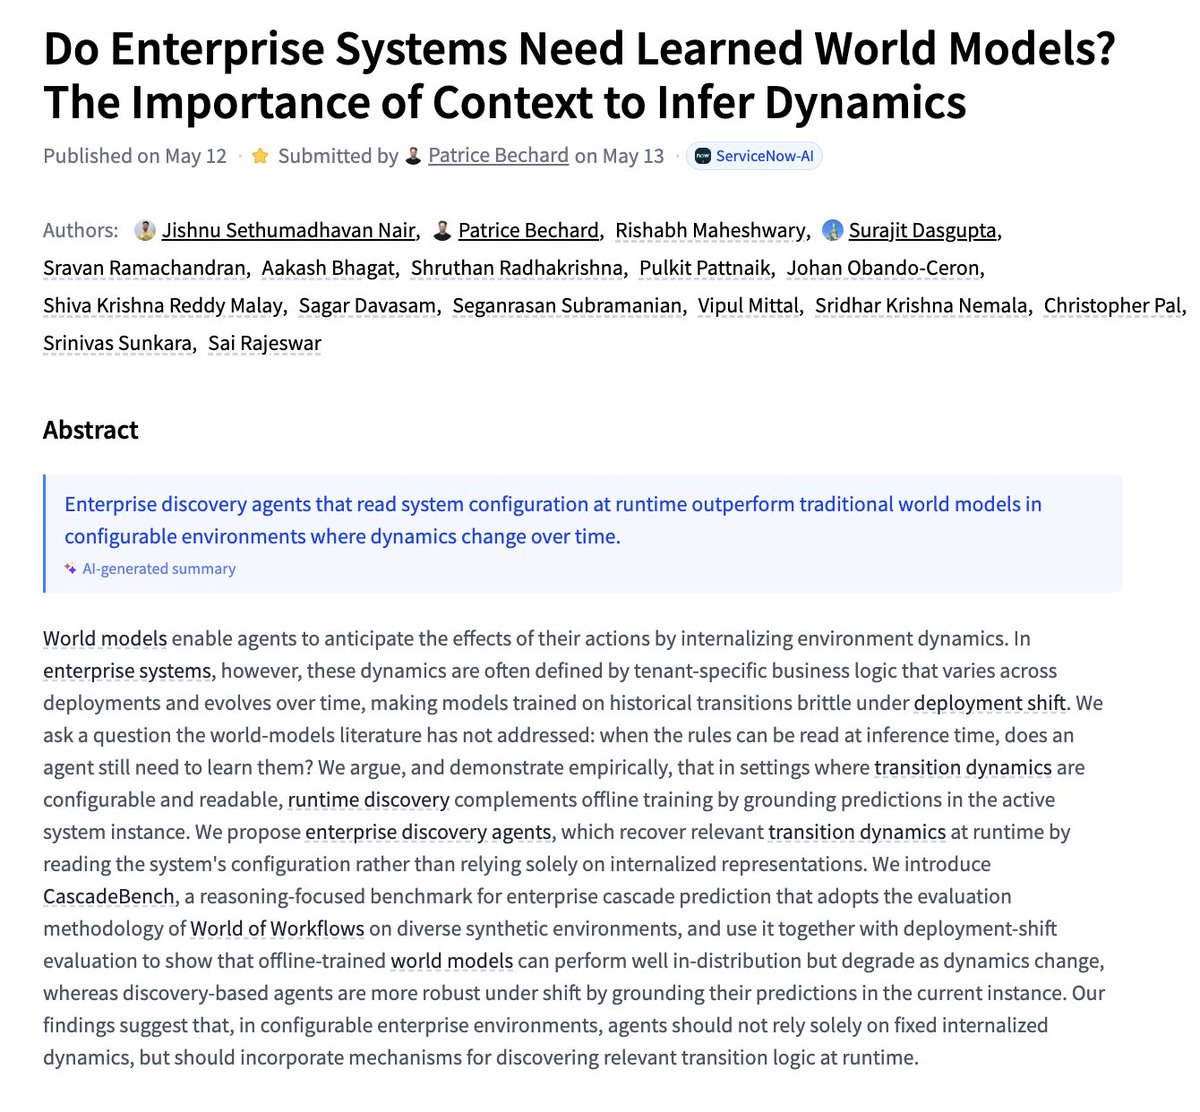
🚨The World Model Myth in Enterprise Systems🚨
Everyone’s obsessed with world models for agents.
But in enterprise systems? The entire "world" (rules, workflows, transitions) is readable at runtime. No hidden dynamics.
We asked the dangerous question:
Do enterprise systems need learned world models?
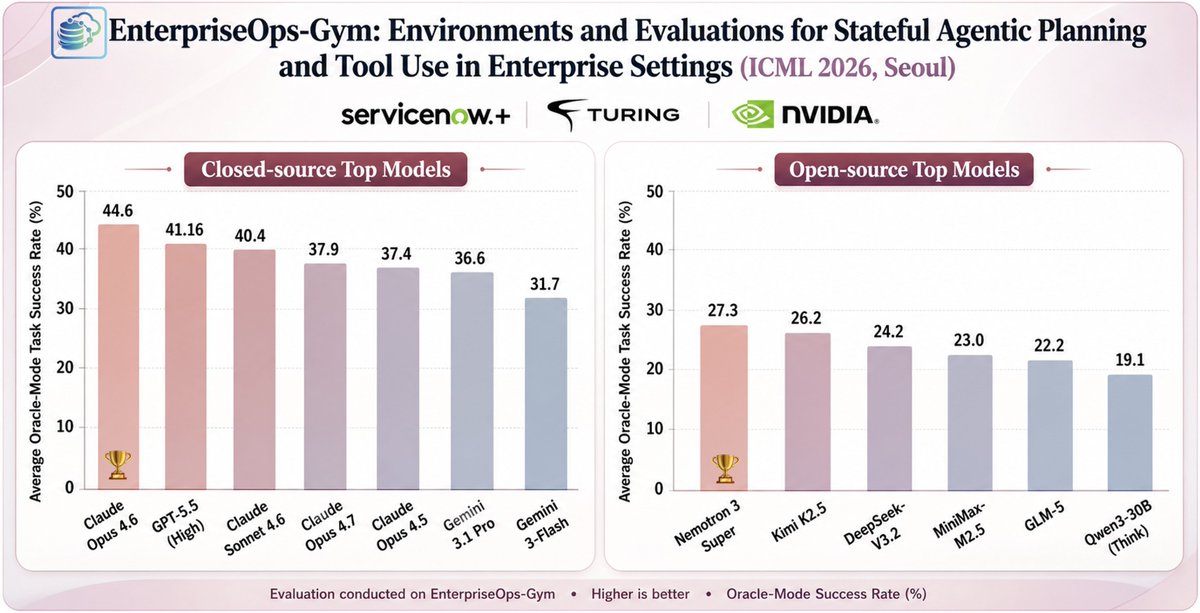
📢 EnterpriseOps-Gym is now accepted to ICML 2026 🇰🇷✨
website: https://t.co/PJvBFnYsm9
🧩 1,150 expert-curated tasks
🏢 8 enterprise domains
🧰 512 tools
✅ Deterministic verifiers (Outcome + Integrity + Compliance)
📦 Fully containerized, no enterprise instance required
📊 𝗙𝗿𝗲𝘀𝗵 𝘂𝗽𝗱𝗮𝘁𝗲: GPT-5.5 numbers are out (alongside the strongest open and closed baselines). We will keep updating as new models drop because long-horizon reliability is moving fast, and we want to stay current.
One exciting (and humbling) signal: we’ve already seen frontier lab teams experimenting with EnterpriseOps-Gym to stress-test and improve their agents: including folks at OpenAI, Mistral AI, and NVIDIA AI. 🙏
📈 𝗘𝗮𝗿𝗹𝘆 𝗿𝗲𝘀𝘂𝗹𝘁𝘀 𝗮𝗿𝗲 𝗽𝗿𝗼𝗺𝗶𝘀𝗶𝗻𝗴: Top open models including NVIDIA Nemotron Super are showing strong performance, in some cases competing with frontier models.
@shiva_malay@sagardavasam@PShravannayak@turingcom@jonsid@ServiceNowRSRCH@Mila_Quebec
Terminal Agents Suffice for Enterprise Automation
ServiceNow research shows terminal-based coding agents with direct API access match or outperform complex MCP and GUI agents, proving strong foundation models need only simple programmatic interfaces for enterprise automation.
What if we didn't need MCP servers after all?
What if we didn't need browser-use agents either?
What if... Claude Code was enough?
In our latest paper, we test exactly this: Can simple terminal agents outperform web agents and tool-based agents on real enterprise tasks?
🧵 Introducing 𝐄𝐧𝐭𝐞𝐫𝐩𝐫𝐢𝐬𝐞𝐎𝐩𝐬-𝐆𝐲𝐦🚀 : a rigorous new benchmark for stateful agentic planning and tool use in real enterprise environments.
1,150 expert-curated tasks · 512 tools · 164 DB tables · 8 domains. Every task verified by hand-written SQL, checking goal completion, state integrity and policy compliance🔥
𝐓𝐡𝐞 𝐡𝐞𝐚𝐝𝐥𝐢𝐧𝐞: Claude Opus 4.5 — our best-performing model succeeds on just 37.4% of tasks. With oracle tool access. No tool discovery required.
📄 https://t.co/S4EHVbabpy (trending #4 on daily-papers)
🌐 https://t.co/oMqtV1gHEG
🤗 https://t.co/Uv0pzQiuh2
💻 https://t.co/rohdFTfchK
Mercury 2 is live 🚀🚀
The world’s first reasoning diffusion LLM, delivering 5x faster performance than leading speed-optimized LLMs.
Watching the team turn years of research into a real product never gets old, and I’m incredibly proud of what we’ve built.
We’re just getting started on what diffusion can do for language.
10/10
If you’re building:
- synthetic data engines
- agentic tool-call datasets
- eval harnesses
- multimodal pipelines
or need a UI builder
…SyGra v2.0.0 is ready.
⭐️ Check the SyGra GitHub repo: https://t.co/h9hHnCazP4
Drop your workflows/questions—happy to help!
1/10
🚀 SyGra v2.0.0 is out.
Synthetic data + eval pipelines just got a UI, multimodal, enterprise connectors, and real observability.
If you build LLM workflows in research or production: this release is for you. 🔥
🧵👇