Introducing OmniShotCut, a sensitive and more informative SoTA on the Shot Boundary Detection.
OmniShotCut can detect shot changes of the video in diverse sources (anime, vlog, game, shorts, sports, screen recording, etc.), and recognize Sudden Jump and Transitions.
OmniShotCut.
Relational shot boundary detection via Shot-Query Transformer.
- detects abrupt cuts and gradual transitions;
- automatic video editing and indexing;
SOTA performance
https://t.co/rMsFr5D2lT
AllenAI releases WildDet3D for promptable 3D detection in the wild
Understands objects in 3D from a single photo—predicting position, size, and orientation. Supports text, point, and box prompts, with optional depth integration.
Thanks @_akhaliq for sharing!
The homepage can be found at: https://t.co/lAZ3IfWpY0
Thank you to all my coauthors: @ChenXuweiyi Matheus Gadelha @ZezhouCheng
Research Work at UVA!
Special thanks @ChenXuweiyi for bridging this opportunity.
Introducing Frame In-N-Out: Unbounded Controllable Image-to-Video Generation
Can we enable video generation to capture a wider and more imaginative world that is not confined by the spatial boundaries of the initial frame?
🚀 Thrilled to share our latest work: Open Vocabulary Monocular 3D Object Detection
💡 Our method OVMono3D-LIFT can detect and localize objects in 3D from a single RGB image for any object category!
🌟 Results on In-the-Wild COCO images:
A 🧵:
#ComputerVision#3DDetection
🚀 Excited to share our latest paper: “Learning 3D Representations from Procedural 3D Programs”
We explore self-supervised learning of 3D representations using procedurally generated shapes, with no reliance on human-designed 3D datasets. We found that Self-supervised 3D representation learning from procedural 3D programs performs on par with learning from ShapeNet across various downstream 3D tasks. Both outperforms training from scratch by a large margin.
👇
📄 https://t.co/0ri6vjgPsU
💾 Dataset: https://t.co/Ynkiaivwi5
🖥️ Code: https://t.co/s4O2b7BryC
#3DRepresentation #PointClouds #SelfSupervisedLearning
We have open-sourced the code and data for "Improved Zero-Shot Classification by Adapting VLMs with Text Descriptions" @CVPR at: https://t.co/imdgtl5nwt
Also, find the poster and video links at the GitHub repo!
Today, I am deeply shocked and saddened by the news that my long-time dear friend, professor Xiaoou Tang of CUHK, advisor to Dr. Kaiming He and my predecessor at MSRA, peacefully passed away at home yesterday. I just had dinner with him last Wednesday in Shanghai! RIP... 🙏🙏🙏
With colleagues from @umassengin, @MajiSubhransu + PhD students Gustavo Perez, Aaron Sun and @ZezhouCheng have developed ZeoNet, a #DeepLearning framework using #ComputerVision techniques to predict the separation performance of zeolite materials. Article: https://t.co/fFSGIFoOwp
@ClimateChangeAI has an excellent post on our work on modeling zeolites. Their 3D structures are predictive of their chemical separation performance, and can be modeled very well using 3D ConvNets.
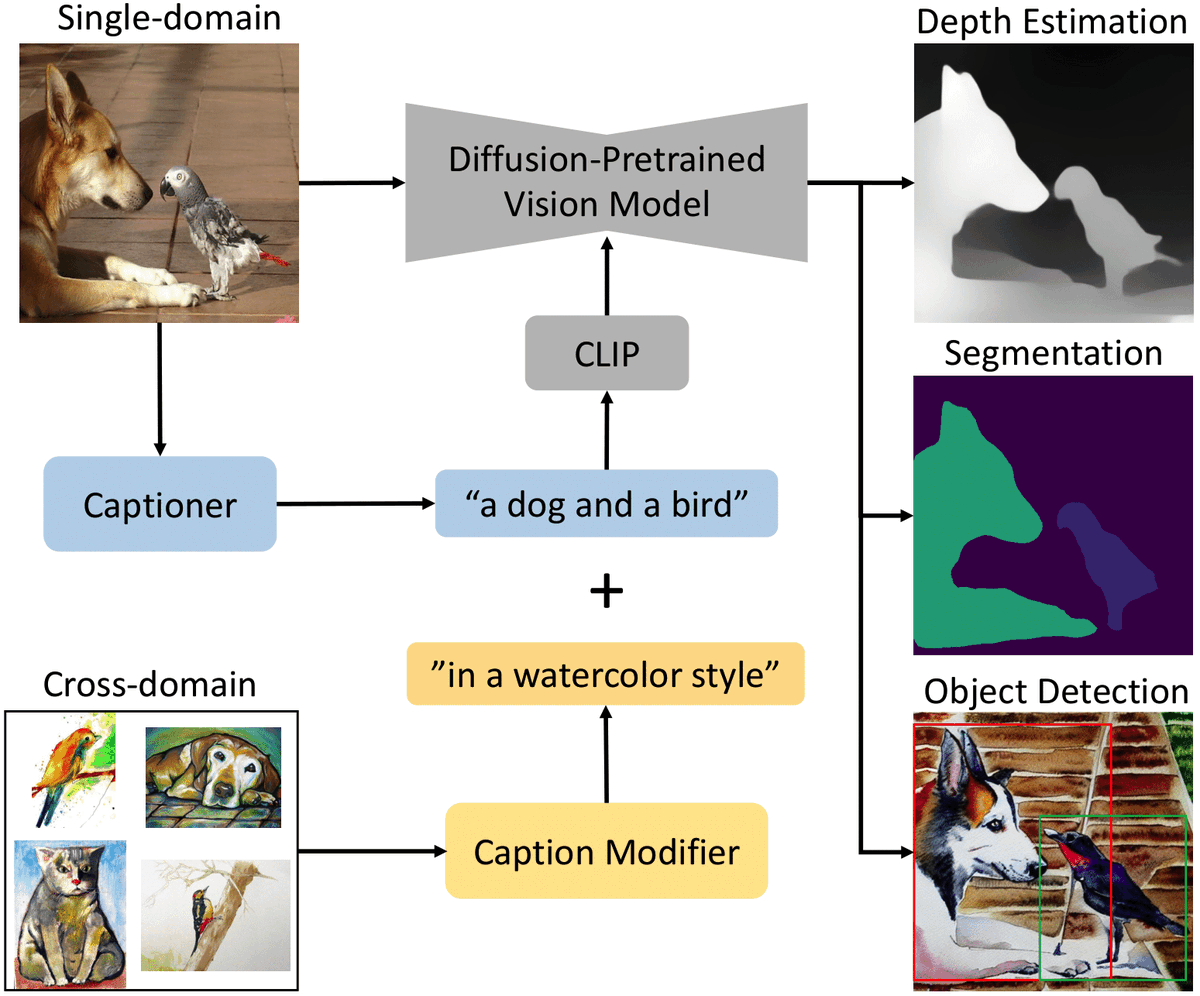
We're excited to share our latest work! We achieve SOTA results in segmentation, detection, and depth estimation, in single and cross-domain, by exploiting image-aligned text prompts in a pretrained diffusion backbone repurposed for vision tasks.
See https://t.co/fGI2UfvJwS
🧵👇
I am eagerly looking forward to my next journey at Caltech w/ @georgiagkioxari and UVA! Massive thanks to my awesome advisor @MajiSubhransu and committee members Dan, Erik, and @jampani_varun! Huge thanks to @HuaizuJiang, @gadelha_m, and many other friends for their support!
Huge congrats to @ZezhouCheng for successfully defending his PhD thesis! He will be starting as an asst. professor at @UVA after postdoc at @Caltech w/ @georgiagkioxari. Prospective students interested in few-shot learning and 3D shape understanding def. apply to work with him.