Just released Parakeet Redux!
A ternary speech-to-text model, built by compressing NVIDIA's Parakeet model from 1.2GB to 178MB.
Runs at 113x realtime on CPU, and beats the base model on the 25-language FLEURS benchmark while staying within 0.3 WER on English.
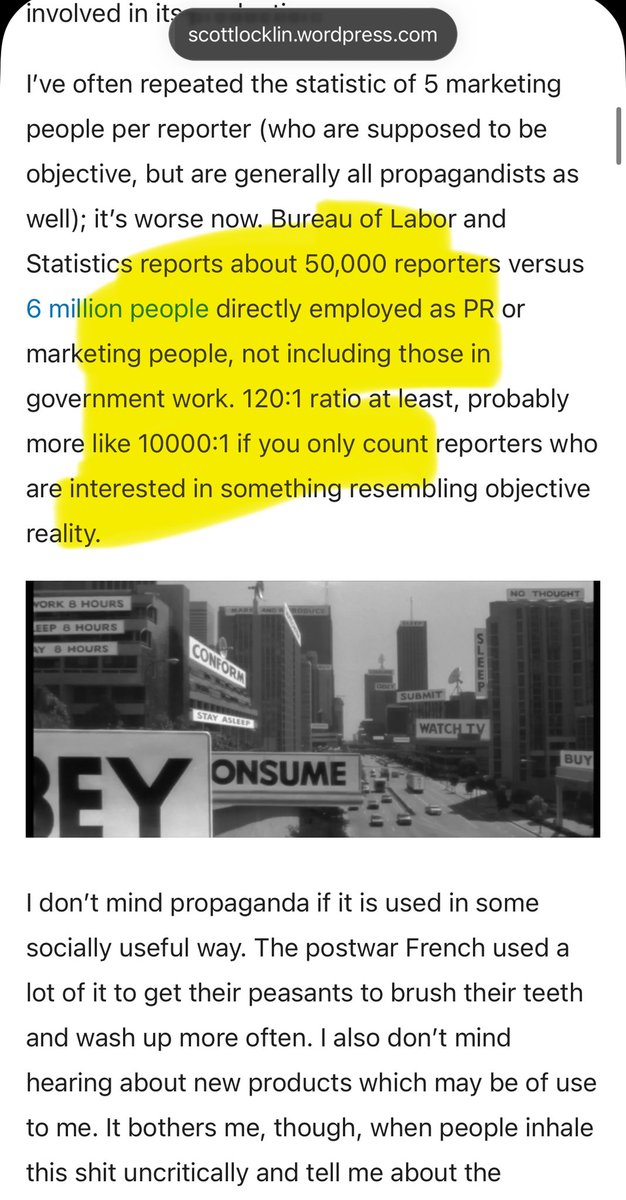
Very good new Locklin article on propaganda. Crazy number: “Bureau of Labor and Statistics reports about 50,000 reporters versus 6 million people directly employed as PR or marketing people, not including those in government work. 120:1 ratio at least, probably more like 10000:1 if you only count reporters who are interested in something resembling objective reality.”
https://t.co/BUlC9v2RhL
@knowledgator This would be used for extracting QA from email correspondences and for example transcripts of interviews.
Would love to do this with a smaller model. Because I feel LLMs having to rerespond with the text and not just
responding with a span is inneficient
@knowledgator Oh thanks
Would a json schema like this be too much for this model?
conversations: [
{turns: [
{
question: "...",
answer: "..."
},
{...}
]},
{turns: []}]
Each conversation is about one topic
@knowledgator This is nice but I have conversations data and I need for the model to semantically understand topics and extract the convos properly. I guess I still have to use a LLM
Bonsai 2 has been evaluated with a low thinking budget for xhigh.
Quantization errors really show their impact on long sequences, and Qwen3.8 27B often needs more than 81K tokens to complete its answer.
For coding problems, like in LiveCodeBench, this is not enough.
Expect some surprises for long-horizon agentic tasks. It's probably not as good as the model card says.
Remarkable work nonetheless, as always.