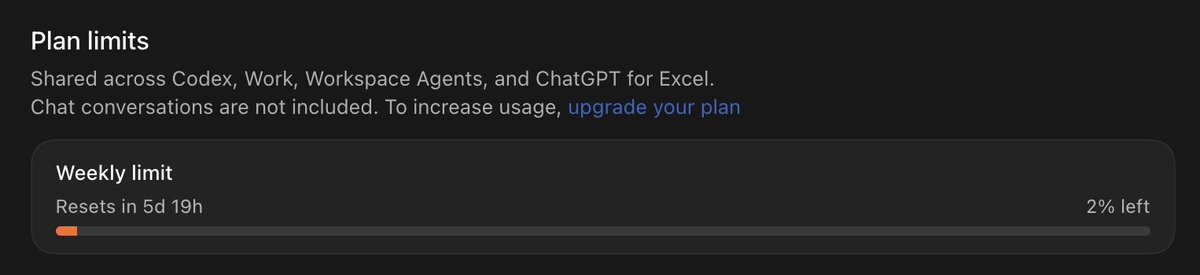
Enjoy it. the window is closing faster than people think. the IPO wave hits in October. openai, the rest of the pack. that's when the subsidies get pulled. 6 months from today we're closing the last chapter of the cheap ai era. What's $200 a month right now turns into $20,000 when the discount disappears. right now you have 100x the capacity you'll have later, shared across every user hitting the same models. most people are spending it on toy prompts. spend like an empire while the tap is still open.
@Stonksmaster בשנת 21-22 כל הודעה חיובית על פלנטיר בבורסה רק הורידה את המניה. השוק ממש לא ידע לאכול אותה בשנים הראשונות. השוואה מעניינת ודי נכונה לפי דעתי
the reason AI teams don't touch their LLM costs is fear of a regression nobody can reproduce. That fear is based on a mental model of compression that doesn't apply to Anyray. @AnyrayHQ compresses your token inputs before the call, no code changes, no output degradation
@OriKatz3 תשמע את הראיון שלו על המדיניות הכלכלית שלו אצל @MichaStocks ותתאכזב לגלות שחוץ מסיסמאות ריקות מתוכן של נגייס חרדים. הוא לא באמת הכין שום תוכנית פעולה רצינית.
People always ask how we optimize agent data without breaking the prompt cache.
One rule: hide unrelated data only where the provider hasn't cached yet. Then send that same version every turn.
127 passing tests hidden. The failure kept. Cache still warm.
@hasolidit האמת ששמעתי את הראיון שלו אצל מיכה סטוקס והאג׳נדה הכלכלית שלו בעיקר בנויה על סיסמאות ריקות מתוכן. לצערי לא שמעתי מישהו אחר עם תוכניות יותר טובות משלו אבל מאוד לא מקצועי לשמוע אותו ככה.
Correction: dug deeper and it isn’t threads.
With a custom base URL, Claude Code leaves out the <total_tokens>… tokens left</total_tokens> budget notice from the system prompt. Add it back and parallel calls return (3/8 → 10/10 in replays; full sessions 2/5 → 5/5, ~$0.22 → $0.18).
Details: https://t.co/Ihi1E7f42q
@bcherny caught a Claude Code footgun.
Point ANTHROPIC_BASE_URL at even a pass-through proxy and dispatch + message threads go quiet. Parallel tool calls collapse — 6/6 sessions → 1/7.
Same work. Roughly 2× the requests if you're behind a gateway.
Repro: https://t.co/P36zHIgfBx
A pricing agent. One competitor page. One hop later, a trap.
Humanbound ran 1,350 attempts. Undefended, four of five non-OpenAI models leaked a confidential unit cost every time — just from reading the web.
Hardened prompts mostly stopped the leak. Then the agent guessed. Across 27 model×guardrail combos: zero outcomes that were both safe and well-grounded.
The prompt isn't the boundary. Egress and provenance are. If security changes when you swap models, you don't have a control — you have a coin flip.
@itsGrizai@OpenAI Overnight job + its own computer is the right test.
Who owns 3am: you, or the agent that kept flagging until sunrise? I'd want a kill switch and a max-actions budget before the first report.
@BowTiedCrocodil Hardware scar tissue is underrated.
The OS saying yes and the breaker saying no is the whole agent story: capability without a hard stop still trips something — better you pick the stop.