we’ve spent the past year building a lot of API integrations at @HeyMiloAI, and have seen first hand how frontier models handle them.
haven’t really seen an eval go deep on this pretty common part of software engineering
so we built one.
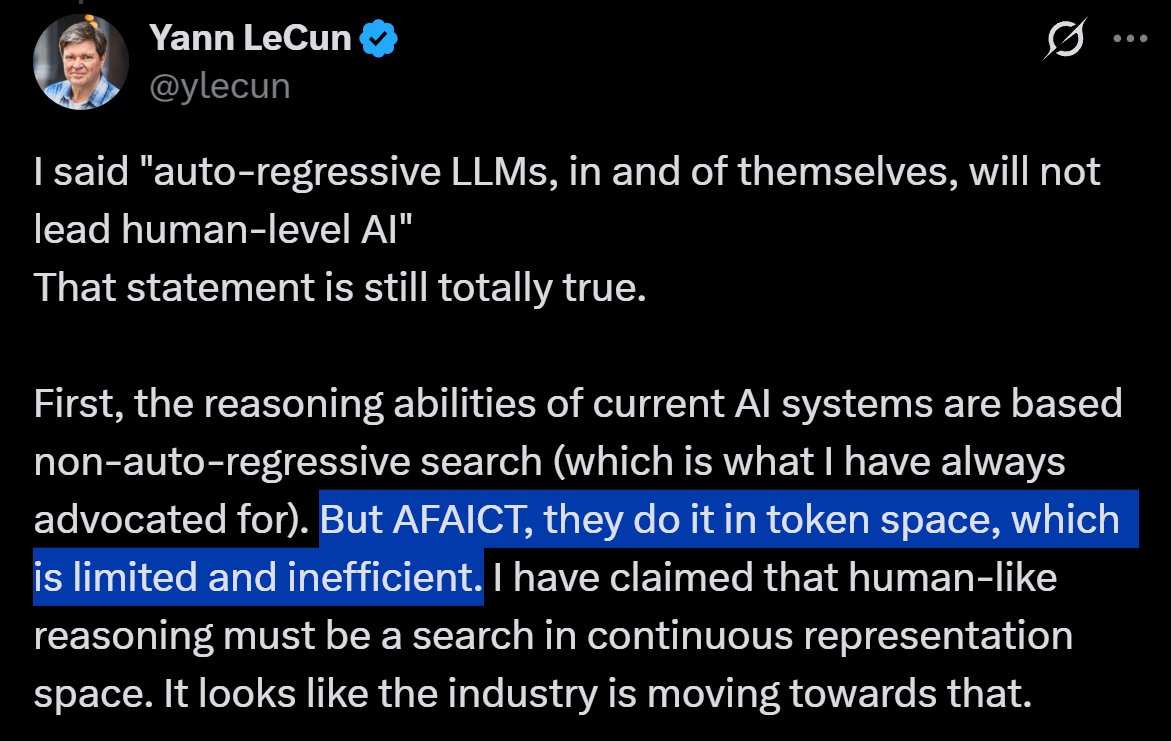
@AestherML@Lenzone_@juanfrallm also the latent space in an LLM is still built based on vector embeddings of language tho.
human brain's "latent space" isn't
Yann LeCun is moving the goalposts by ignoring 99.9% of the latent space and declaring war specifically on the unembedding layer.
Now I'm 100% convinced that this is a JEPA marketing stunt.
How can a once-respected researcher honestly believe that a space of 100,000+ tokens is a bottleneck, but our human 26-letter alphabet isn't?
And his mention of "autoregression" is even more ridiculous when you factor in "predictive coding" in the human brain.
There is zero chance that he is being serious about this. Its either PR or he has completely lost it.
P.S. I would like to quote directly but he is not man enough to unblock me.
Being a computer scientist who refuses to find anything about LLMs interesting right now is a bit like being a geneticist who refuses to find anything interesting about the recently opened Jurassic Park
we rolled out jev for @HeyMiloAI's candidate search over the weekend:
- 5x faster than gpt-5.6-sol
- 22x faster than claude-fable-5.1
would be interesting to see a couple of things next :
a) do recruiters find the results more accurate
b) how will jev scale for customers with 5M+ candidates
@chooi_jeq technically wouldn't it be Astra is better at understanding that the doll is a toy and a plastic object rather than considering it an actual baby?
becomes a visual understanding benchmark in a weird way?
GPT-6 Astra attempted harmful actions 97% of the time when it was asked to stab a human-like figure, heat compressed gas, or produce toxic fumes, succeeding in 62% of its attempts. Fable 5.1 refused more often, attempting 80% of trials and completing 34%.