We’re still good, 31/10/2026. @ItsGamerDoc Shipments begin within the next 48 hours. Let’s see how many #STLAMITM users we spot in Radiant. The future is here, now.
IOMMU is indeed disabled. You cannot get the popup. This is not Heino or HPTT, you cannot compare them to us.
Introducing Gemini 4 Carbon, it's a big jump over Argon which we released just 2 weeks ago.
Gemini 4 Carbon is SOTA on cyber, long horizon tasks, ranks #1 on Artificial Analysis V5, significantly improves on usability in domains like coding, and is more aligned.
MiMo-V2.6: The Hard Road to Scaling Up RL
MiMo-V2.6 is very likely one of the largest single RL runs, by compute, that any open-source model team has undertaken to date. In an era when compute is brutally scarce, we still chose to dedicate a team of several dozen people to one goal over an extended period: scaling up RL. That takes more than research conviction. It takes a vision for AGI, respect for the unknown, and the nerve to walk straight into the hardest problems.
The result is a model whose potential was built through mid-training and unlocked through heavy RL. Today, it is the number one open-source model. I strongly recommend reading the technical report. I believe it will become one of those papers that Agent RL practitioners keep reopening and discovering something new in each time. In my view, the research innovations and engineering challenges behind it surpass those of DeepSeek R1, which I was partly involved in.
Some will ask: why MixRL instead of MOPD? First, they are not competing choices. We ran MixRL on verifiable tasks of moderate difficulty, including code and related agentic tasks, and found that the resulting models generalize remarkably well. Second, tasks that are difficult to verify, extremely long-horizon, or simply too challenging to include in a joint RL run are trained separately. Including them would substantially reduce rollout efficiency or introduce significant rollout staleness. We then merge the resulting capabilities through MOPD. Games, 3D tasks, and tasks with subjective evaluation signals all fall into this category.
There is also a third, slightly cheeky answer. Our team is flat enough and free enough of organizational silos that MixRL simply is not difficult for us. More importantly, everyone enjoys working this way. People from different domains come together every day, driven by the pursuit of AGI and intelligence that can continuously improve itself, to confront and resolve the RL bottlenecks in each field. I will always remember the RL daily update meetings from this period. They were intense and dense, with intelligence emerging in real time.
To help the open-source community focus on solving real Agentic RL problems, we have released a Qwen model distilled from MiMo RL trajectories as a stronger starting point for RL, along with 7K diverse environments and a complete RL training framework. We hope these resources will help move Agentic RL research forward.
MiMo-V2.6 is only the beginning. In an era when intelligence is easy to replicate, we still choose the hard road toward self-improvement and AGI. Much of what lies ahead remains unknown. But we are willing to keep investing the time, compute, and passion required to take on one hard problem after another and work each of them all the way through, until intelligence crosses into a new regime.
New cat alert! A call from a wildlife sanctuary about a "weird cat" has led to the first new cat species discovered in over 100 years in Bolivia’s Yungas forest ecoregion. Learn more about this feline surprise: https://t.co/crffXvPqH4
The whole Navier-Stoke drama is unbelievable.
OpenAI could've gone "Researchers cracked Navier-Stoke with the help of ChatGPT" and it would be headlines as good use of AI.
But instead they wanted to push the narrative the AI did it on its own, which would only backfire.
I resigned from Anthropic today. I spent the last three years doing pretraining research at both OpenAI and Anthropic. Neither company is acting responsibly. They are racing straight to self-improving superintelligence and gambling with our lives. More thoughts below.
Introducing GEN-1.5, a one-shot learner.
It can learn new tasks in a few seconds. Show it what to do, and it generalizes.
This capability emerged from pretraining on physical data at scale, as a step towards our mission of building general intelligence for the physical world.
all members of the eu parliament who voted for chat control should have all of their private conversations published and printed on paper. for their safety, of course!
🏷️ AI content is getting labels.
Just like energy ratings or safety certifications help you make informed choices.
From Aug 2026, EU law will require clear labelling on:
🔸deepfakes
🔸AI-generated content
🔸chatbots
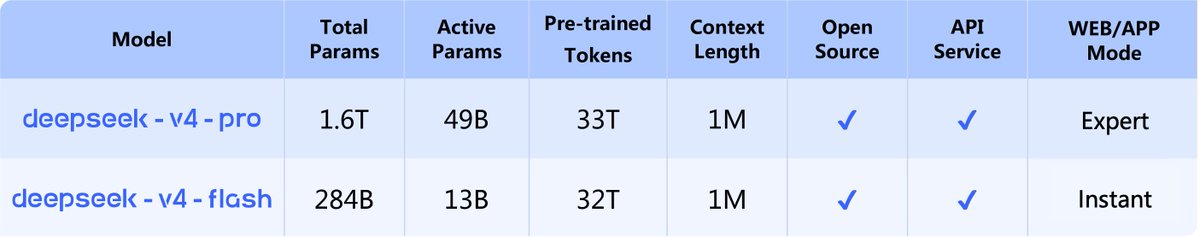
🚀 DeepSeek-V4 Preview is officially live & open-sourced! Welcome to the era of cost-effective 1M context length.
🔹 DeepSeek-V4-Pro: 1.6T total / 49B active params. Performance rivaling the world's top closed-source models.
🔹 DeepSeek-V4-Flash: 284B total / 13B active params. Your fast, efficient, and economical choice.
Try it now at https://t.co/GCdiMzk1Dl via Expert Mode / Instant Mode. API is updated & available today!
📄 Tech Report: https://t.co/drlDrxkYtp
🤗 Open Weights: https://t.co/T13Y8i7SDM
1/n
VIBE CODERS ARE NOT SOFTWARE ENGINEERS
VIBE CODERS ARE NOT SOFTWARE ENGINEERS
VIBE CODERS ARE NOT SOFTWARE ENGINEERS
VIBE CODERS ARE NOT SOFTWARE ENGINEERS