@iTanayVaswani Depending on your definition of "retrieval", hybrid retrieval pipelines have been around for a while (especially for candidate generation in recommender systems)
@__acbraingenome Just when you think there's no hope, a Zhang appears with just the info you need. (This time with model arch details of GPT 6 Astra, nearly a month and a half before the launch 💀)
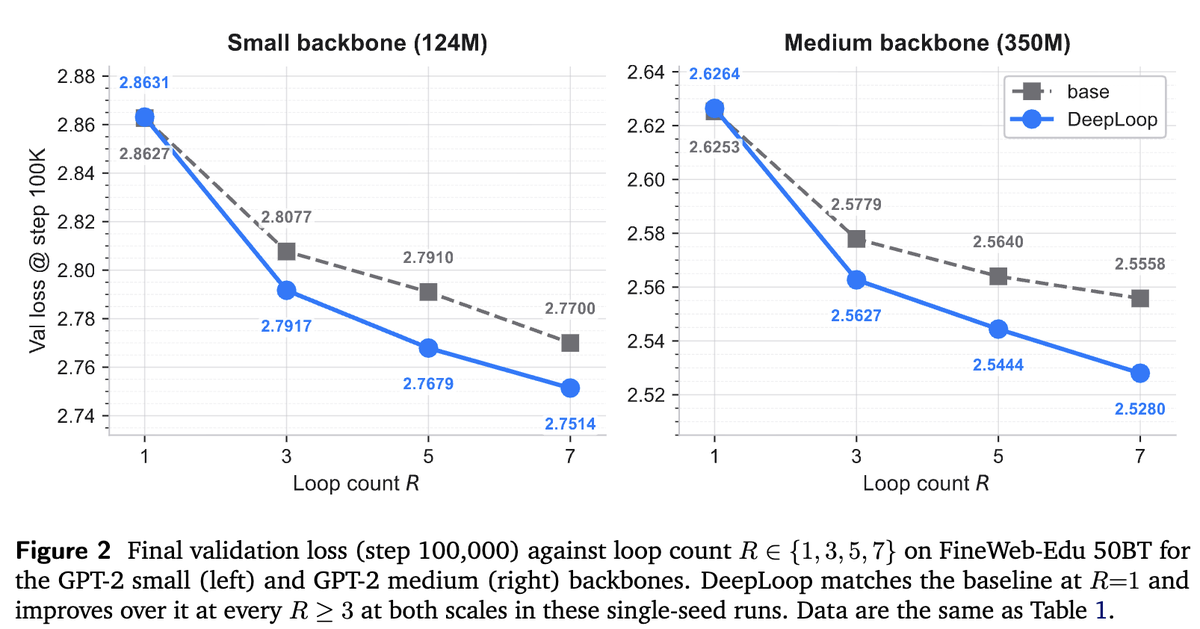
Heard that some frontier models are basically a 48-layer transformer looped twice (48L x 2).
Now we are introducing DeepLoop: Depth Scaling for Looped Transformers (https://t.co/jtxllo9aFF),
making the loop transformer stable and scalable!
@vibespersecond Ahh, so I suppose they're targeting something like "adapter bridges for local models" to be sold the big model orgs.
I wonder how long before we get
api.<your_fav_model_co>.com/v1/latents/
endpoints :)
@shrav_10 Depends. What's your vector storage like? Does it support true prefiltering?
- Yes? (Example: Postgres + pgvector or milvus) Map each user id to an allow list and filter based on RBAC before performing ANN.
- No? Create per RBAC role Vector indexes and use accordingly.
Qwen3.8-Flash can now be run locally! 🔥
The 125B MoE model outperforms Claude-Opus-4.6 (Max).
Run on 75GB RAM via Unsloth GGUFs.
Qwen3.8-Flash-Next enables CPU RAM / unified mem setups to deliver near VRAM speeds.
Guide: https://t.co/LLMclyJTeL
GGUF: https://t.co/vXkjO3W0fj
Everyone guessed who made Ox Alpha today. I fingerprinted it instead. One page, 9 infrastructure probes: tokenizers, error codes, hidden templates. I ran • the mystery model against 12 suspects. One family matches every tokenizer test: GLM. Plumbing does not lie. Tool in reply, bring your own keys. Link in reply
@SaiyamPathak Not me, but a cool problem:
"Good model, but not multimodal? Graft the vision encoder of another model"
Something that the talented folks at @baseten did to give Kimi's vision to GLM5.2:
https://t.co/KO3DVG0ULX